
MapReduce splits a big job into many small map tasks, moves the results by key in a shuffle, and adds them up in reduce tasks. This post walks one word count through every step, with a recreated diagram and the same idea in T-SQL.
Horizontal and Vertical Scaling for Databases
Horizontal and vertical scaling solve different SQL Server capacity problems; compare larger machines, additional nodes, and the costs each brings.
How Apache Spark Works: Driver, Executors and Partitions
How Apache Spark works comes down to a driver that plans the job, executors that run it, and data cut into partitions. This post follows one sales total through two stages and a shuffle, and compares it with a parallel plan in SQL Server.
What Is NoSQL? Data Models, the CAP Theorem and Trade-Offs
What Is NoSQL? It is a family of data models other than the classic table, each built for one kind of access pattern. This post covers the four data models, eventual consistency and the CAP theorem in plain words, and how to choose.
Cohort Retention Tables in T-SQL: From Raw Events to a Grid
Build a retention grid from raw orders with five rows you can check by eye. Includes the DISTINCT rule and why unfinished months show NULL.
Counting Current Connections by Login, Host and Application
Try counting current connections by login, host, application and database, then inspect sleeping transactions and save a baseline.
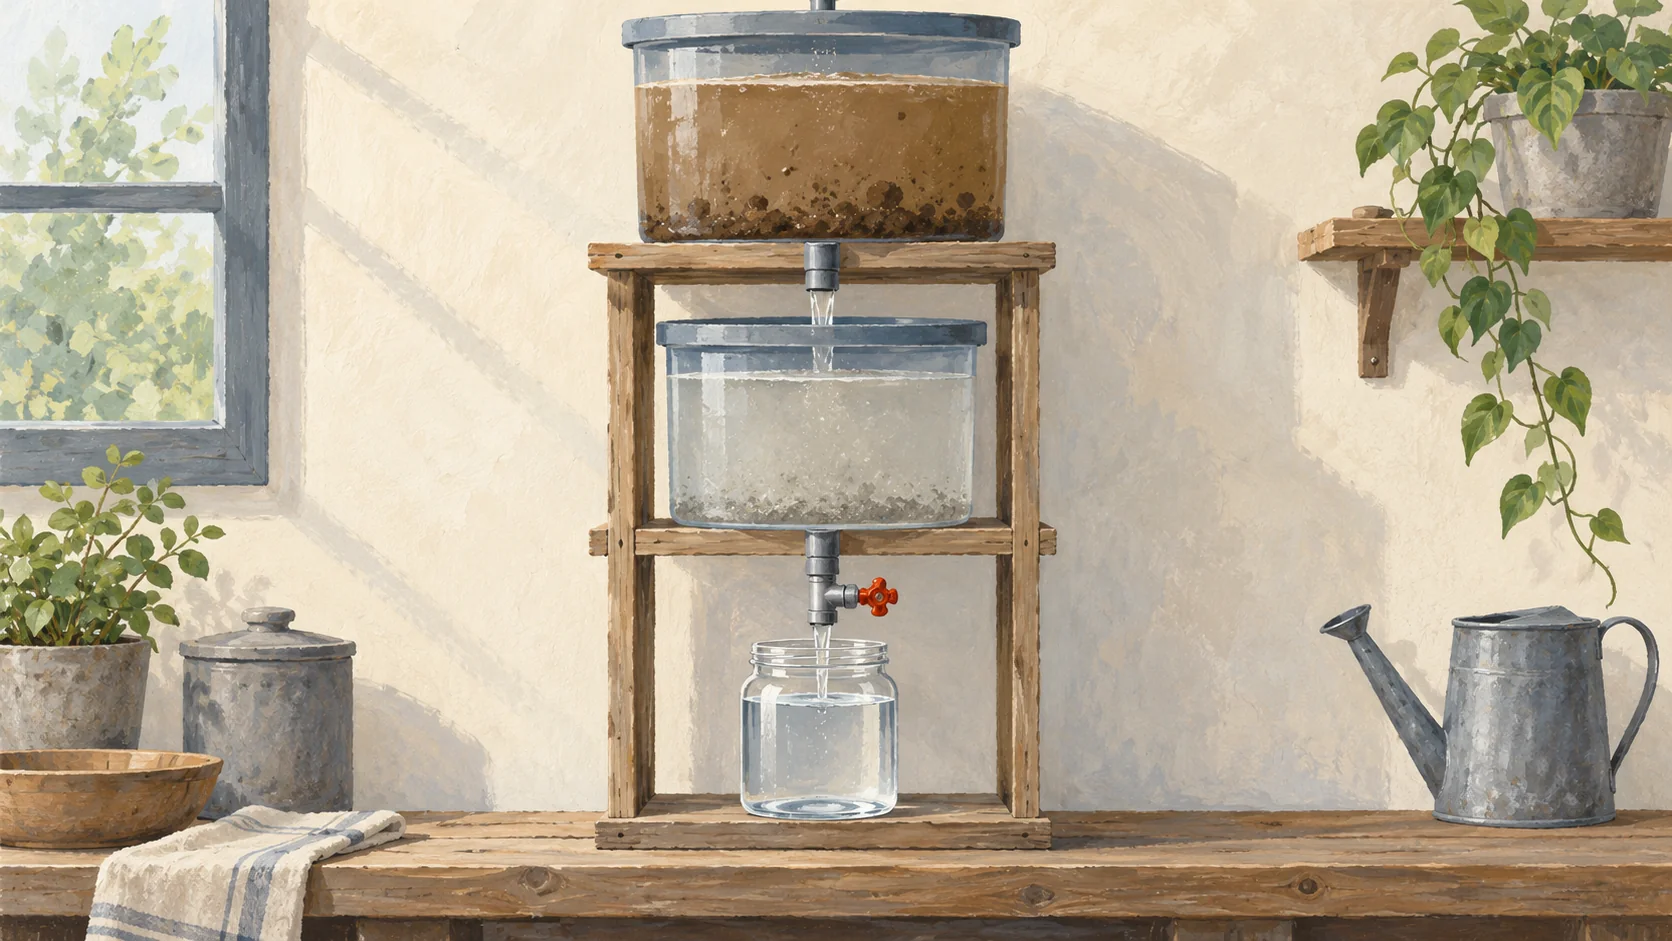
Big Data Architecture Today: The Lakehouse and Medallion Layers
Big Data Architecture today is a pipeline with four jobs: ingest, store, process and serve, with governance underneath. This post explains the lakehouse, the bronze, silver and gold layers, batch and streaming, and where SQL Server 2025 fits.
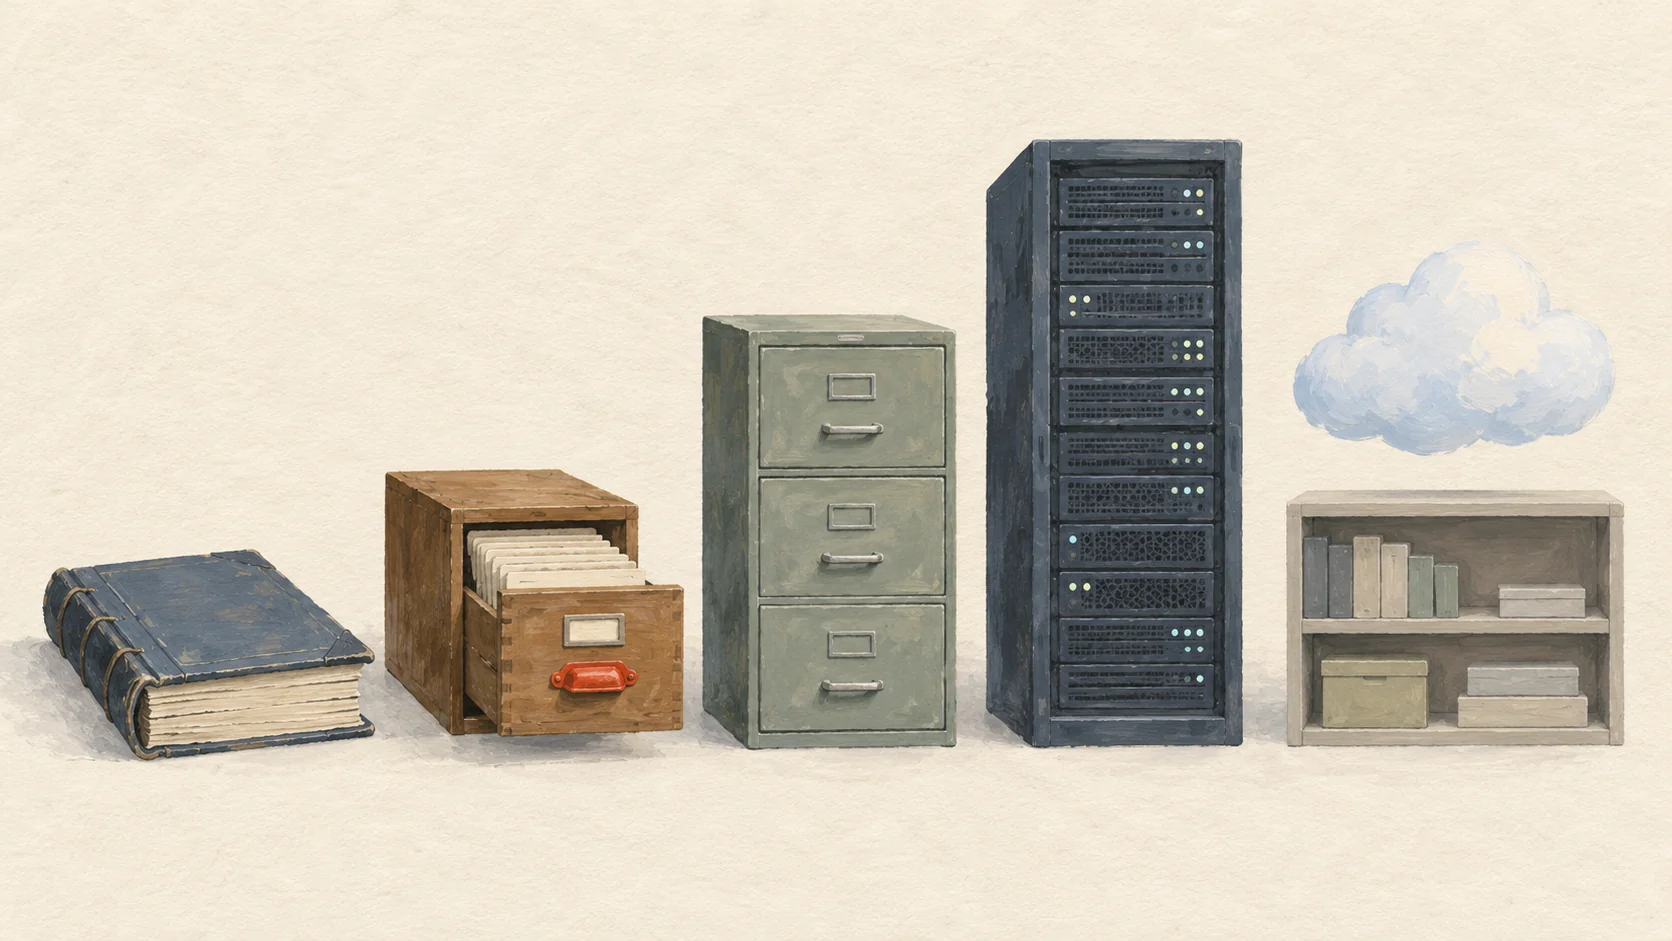
Evolution of Big Data: From Flat Files to the Lakehouse
Evolution of Big Data follows one pattern: data grew, the old tool strained, and someone built the next one. This post walks from flat files and the relational model through warehouses and the cloud to the lakehouse.
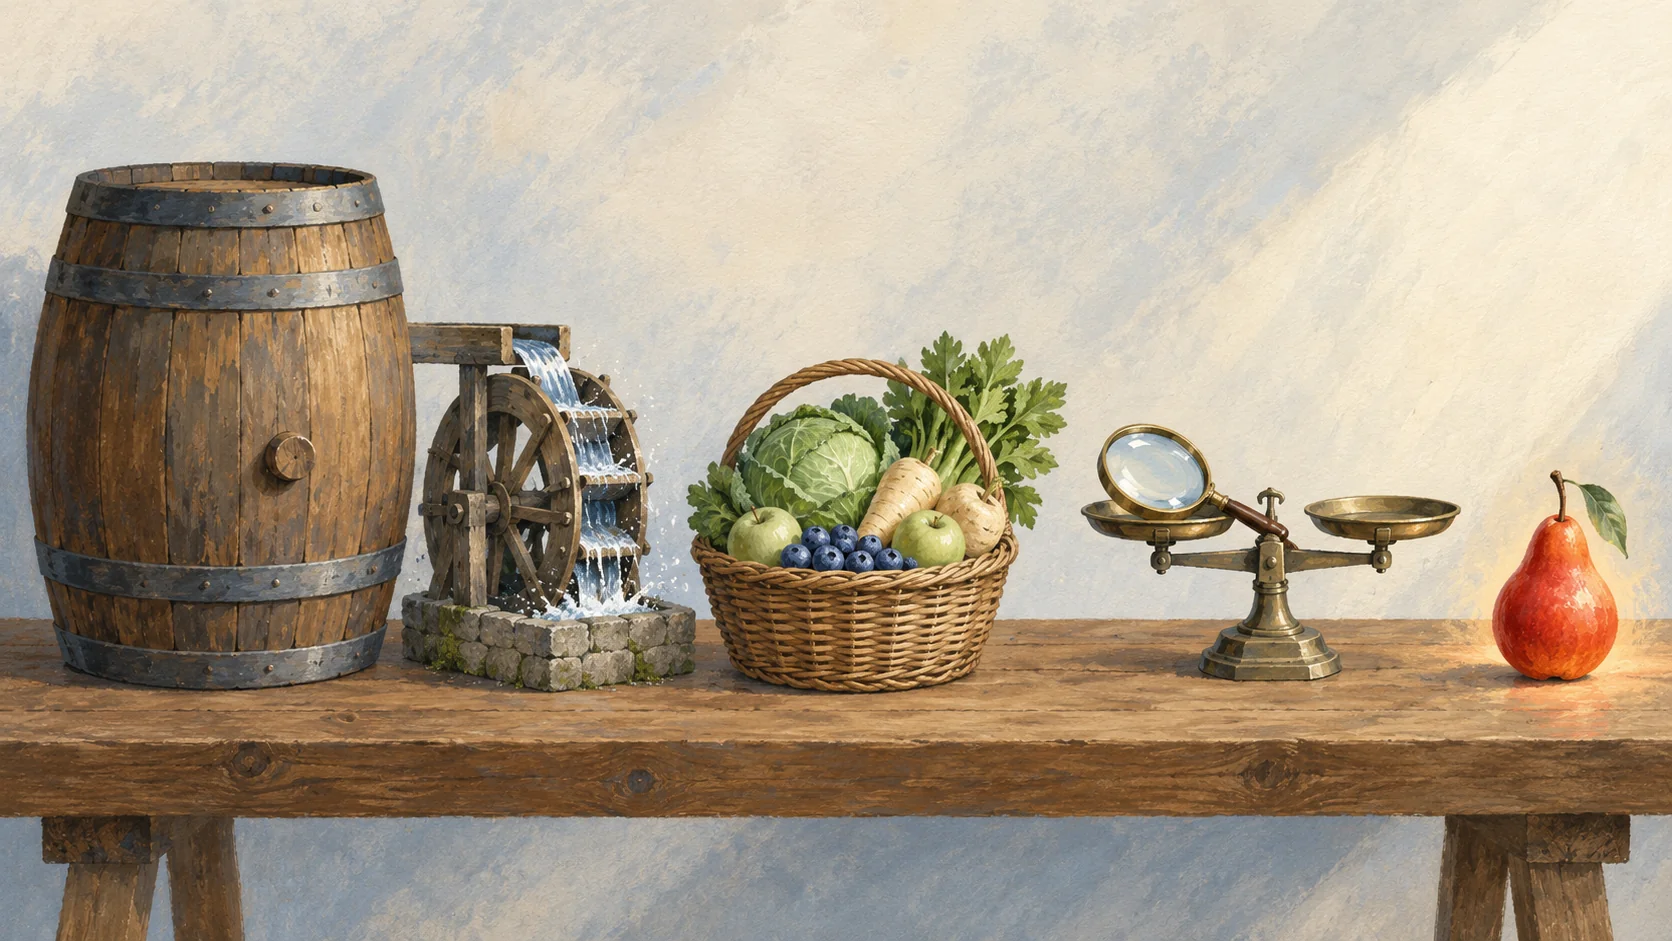
The 5 Vs of Big Data: Volume, Velocity, Variety, Veracity and Value
The 5 Vs of Big Data are volume, velocity, variety, veracity and value. This post walks a grocery chain through each one, so you can ask the same five questions about your own data before you choose a tool.
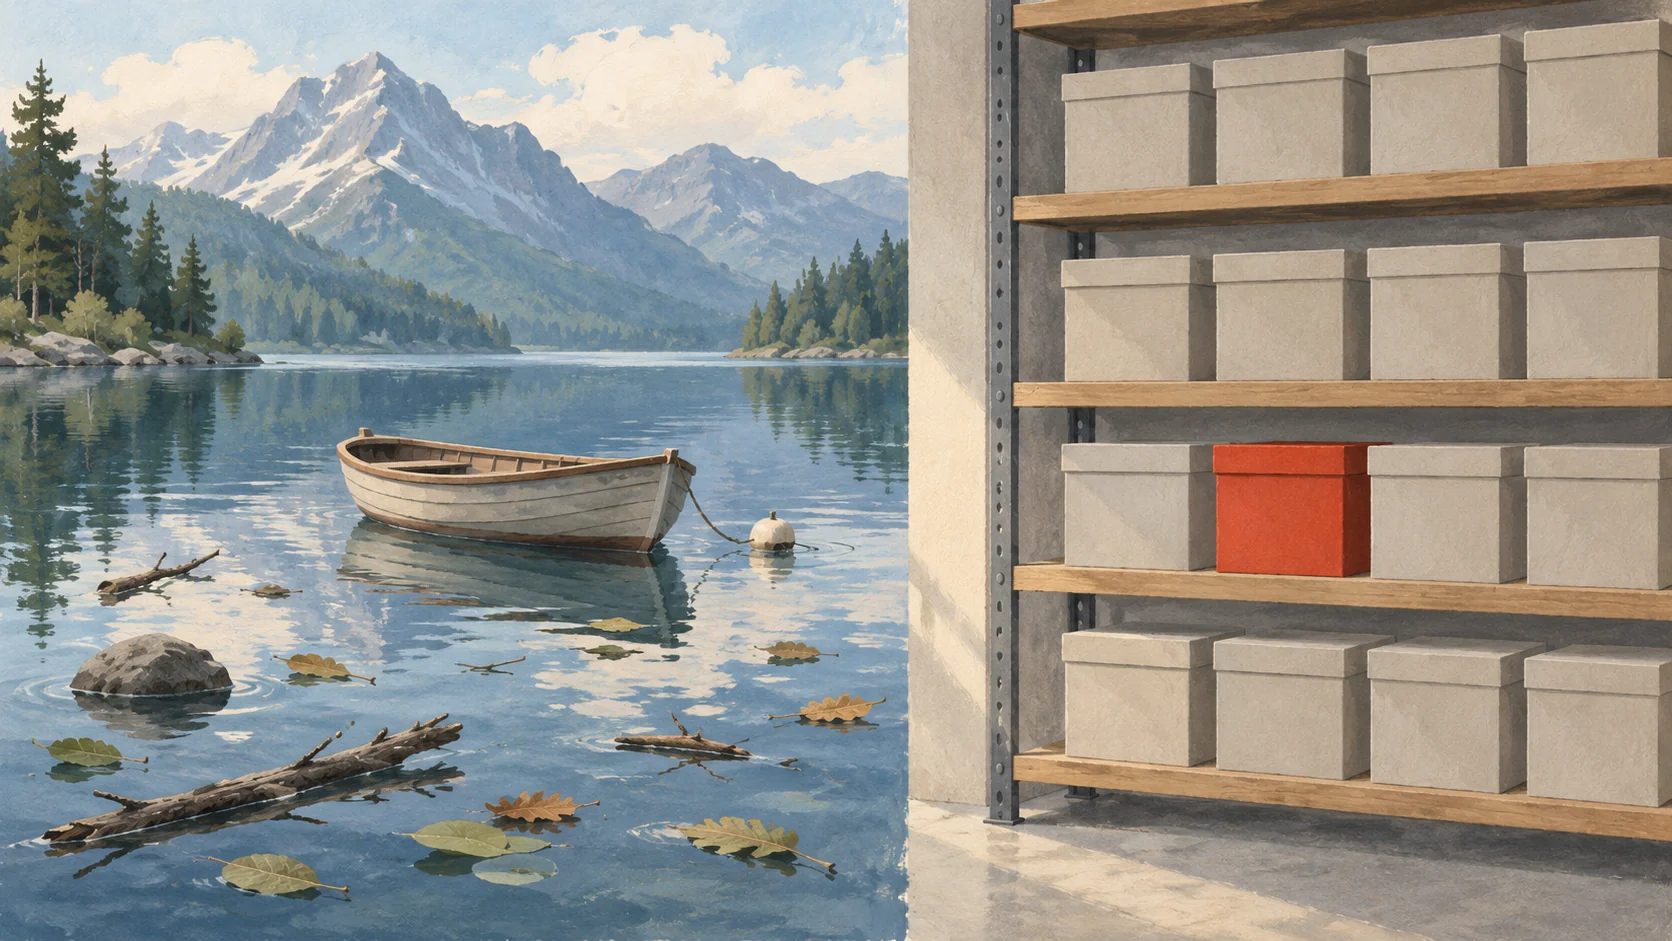
Data Lake vs Data Warehouse: What Each One Is For
Data Lake vs Data Warehouse is a choice between raw files and cleaned, modeled tables. This post compares schema on read with schema on write, who uses each, and why many teams combine them in a lakehouse.