
Understand entity-attribute-value query costs, lost types, indexing limits, and alternatives using real columns, sparse columns, or JSON.
JSON or Real Columns: Deciding Where Attributes Live
Putting everything in a JSON column is tempting. Here is what it costs in reads, type checks and null handling, and when to promote a property.
Vertical Partitioning: Moving Rarely Used Columns Off a Hot Table
Moving rarely used columns to a side table can cut reads, or change nothing. Here is how to measure it and what it costs your writes.
Polymorphic Associations: Why One Column Cannot Point at Many Tables
One column that points at many tables cannot be enforced by SQL Server. Here is the demo, the orphans it allows, and a design that says no to bad rows.
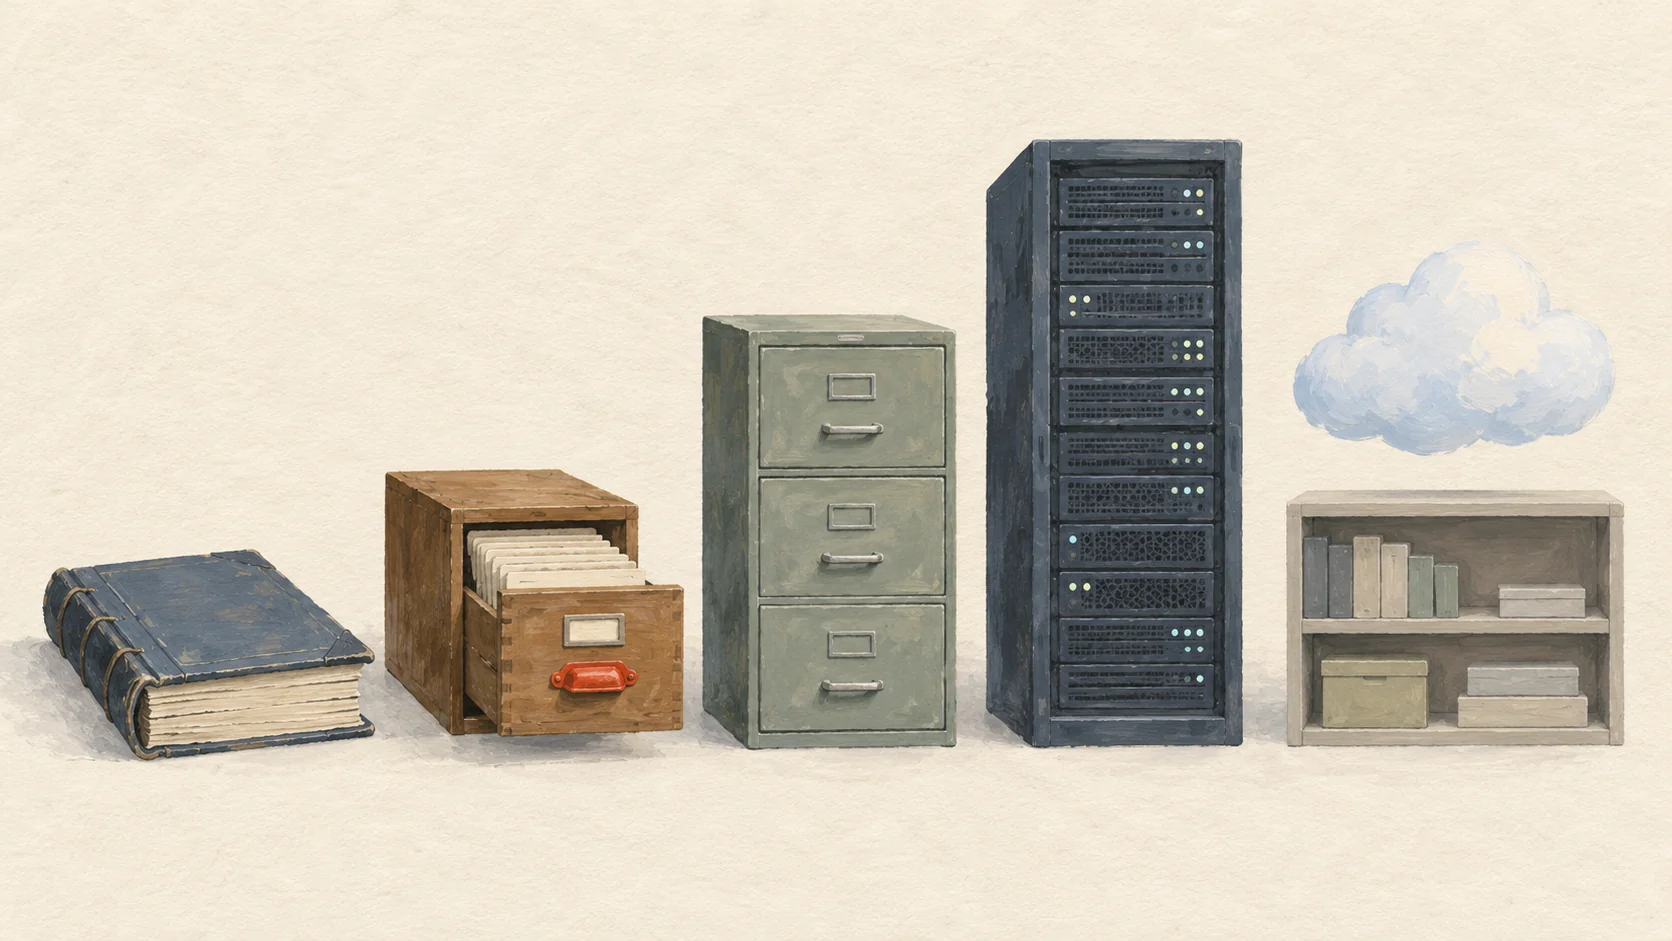
Evolution of Big Data: From Flat Files to the Lakehouse
Evolution of Big Data follows one pattern: data grew, the old tool strained, and someone built the next one. This post walks from flat files and the relational model through warehouses and the cloud to the lakehouse.
Turning a Comma-Separated Column Into a Proper Child Table
A list stuffed in one column makes every search a guess. Split it, clean it and move it into a child table, then check the result before you drop anything.
Tagging With a Many-to-Many Table: Storing and Querying Hashtags
Store hashtags in a tag and bridge table, normalize input, query any or all requested tags, and count weekly trends without scans.