
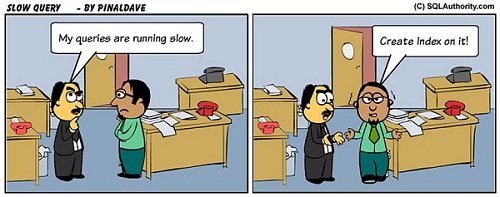
Index write cost is the part of “Create Index on it!” that nobody says out loud. My cartoon captures a conversation I hear during performance tuning. Someone reports a slow query, and someone else suggests an index before anyone has investigated.
An Index Is One Part of the Answer
Performance tuning remains one of my favorite subjects. A good index can make a useful difference, so I understand why it comes up first. I don’t want the cartoon to suggest that indexes are unimportant. The point is to avoid treating one answer as the solution to every problem.
So I measured both sides on SQL Server 2025. One side is what an index saves a query. The other is what it adds to every INSERT.
What One Index Saves
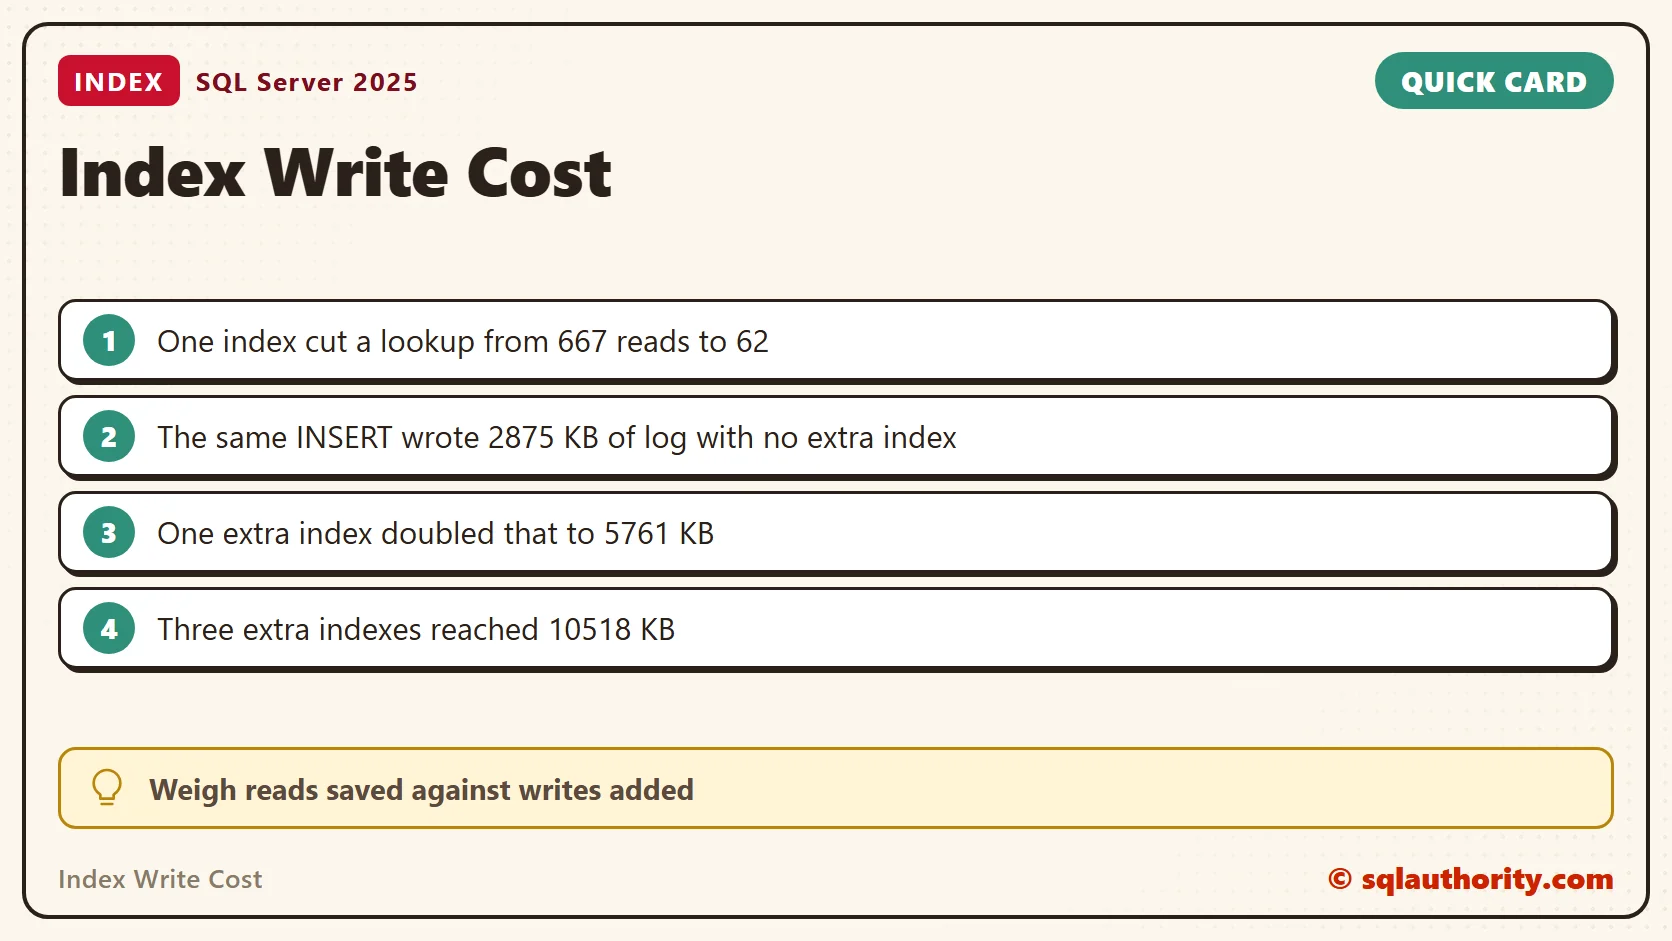
My test table holds 100,000 meal rows. Looking up one customer’s 20 meals with no index on CustomerId took 667 logical reads. With the index, the same query took 62.
CREATE TABLE dbo.Meals (
    MealId int IDENTITY(1,1) PRIMARY KEY,
    CustomerId int NOT NULL,
    MealDate date NOT NULL,
    Dish nvarchar(40) NOT NULL,
    Branch char(3) NOT NULL,
    Amount decimal(8,2) NOT NULL);
INSERT dbo.Meals (CustomerId, MealDate, Dish, Branch, Amount)
SELECT value % 5000 + 1, DATEADD(DAY, value % 730, '2025-01-01'),
       CHOOSE(value % 4 + 1, N'Paneer wrap', N'Masala chai', N'Veg biryani', N'Lemon rice'),
       CHOOSE(value % 3 + 1, 'EAS', 'WES', 'NOR'), 4 + value % 20
FROM GENERATE_SERIES(1, 100000);
SET STATISTICS IO ON;
SELECT COUNT(*) AS n, SUM(Amount) AS total FROM dbo.Meals WHERE CustomerId = 42;
GO
CREATE INDEX IX_Meals_Customer ON dbo.Meals (CustomerId);
GO
SELECT COUNT(*) AS n, SUM(Amount) AS total FROM dbo.Meals WHERE CustomerId = 42;
SET STATISTICS IO OFF;
SELECT i.name, ps.in_row_data_page_count AS pages
FROM sys.indexes AS i
JOIN sys.dm_db_partition_stats AS ps ON ps.object_id = i.object_id AND ps.index_id = i.index_id
WHERE i.object_id = OBJECT_ID('dbo.Meals');
That is about a tenth of the work. The index isn’t free to store either. It took 174 pages next to the table’s 663.
What Every Index Adds to an INSERT
A nonclustered index holds an entry for every row. Each new row has to be written to the table and to every index. I inserted 20,000 rows inside a transaction, read the log space it used, and rolled it back.
CREATE OR ALTER PROCEDURE dbo.MeasureInsert
AS
BEGIN
    SET NOCOUNT ON;
    DECLARE @t0 datetime2 = SYSDATETIME();
    BEGIN TRANSACTION;
    INSERT dbo.Meals (CustomerId, MealDate, Dish, Branch, Amount)
    SELECT value % 5000 + 1, DATEADD(DAY, value % 730, '2025-01-01'),
           CHOOSE(value % 4 + 1, N'Paneer wrap', N'Masala chai', N'Veg biryani', N'Lemon rice'),
           CHOOSE(value % 3 + 1, 'EAS', 'WES', 'NOR'), 4 + value % 20
    FROM GENERATE_SERIES(1, 20000);
    DECLARE @log bigint = (SELECT d.database_transaction_log_bytes_used
        FROM sys.dm_tran_database_transactions AS d
        JOIN sys.dm_tran_current_transaction AS c ON c.transaction_id = d.transaction_id
        WHERE d.database_id = DB_ID());
    ROLLBACK TRANSACTION;
    SELECT (SELECT COUNT(*) FROM sys.indexes WHERE object_id = OBJECT_ID('dbo.Meals') AND type = 2) AS extra_indexes,
           @log / 1024 AS log_kb,
           DATEDIFF(MILLISECOND, @t0, SYSDATETIME()) AS ms;
END;
DROP INDEX IX_Meals_Customer ON dbo.Meals;
GO
EXEC dbo.MeasureInsert;
GO
CREATE INDEX IX_Meals_Customer ON dbo.Meals (CustomerId);
EXEC dbo.MeasureInsert;
GO
CREATE INDEX IX_Meals_Date ON dbo.Meals (MealDate) INCLUDE (Amount);
CREATE INDEX IX_Meals_BranchDish ON dbo.Meals (Branch, Dish);
EXEC dbo.MeasureInsert;
| Extra indexes | Log written (KB) | Elapsed (ms, average of 4 runs) |
|---|---|---|
| 0 | 2,875 | 118 |
| 1 | 5,761 | 328 |
| 3 | 10,518 | 572 |
One extra index doubled the log for the same 20,000 rows. Three extra indexes nearly quadrupled it. The elapsed times came from four runs on a busy desktop, so trust the direction more than the milliseconds. The log numbers repeat: a second full run gave 2,881, 5,754 and 10,524 KB.
The log is not the only bill. Every extra index also takes space in the data file, in memory and in the backup. It has to be rebuilt or reorganized too. None of that shows up in the query that the index was built to help.
When the Cost Is Worth It
I accept the write cost when users wait on a frequent query that reads a small slice. I question it when the table takes constant inserts and the query runs once a day. The numbers above give you both sides of that decision.
Three Habits I Keep
First, I measure the read and the write together, as above, before I keep an index. Second, I look for an existing index to extend before I add another, as in Overlapping Indexes With INCLUDE Columns. Third, I judge an index as unused only after watching it through a full business cycle. Index Usage Stats Reset explains why a short window misleads.
A More Useful Conversation
Before discussing a new index, I’d ask these questions:
- Which query is slow, and what response time do users need?
- Does it happen with every parameter value?
- What changed before the problem appeared?
- What does the actual execution plan show?
- What evidence would demonstrate that our change helped?
The test above adds one more to the list. How many writes per second does this table take? A table that loads in batches pays the cost in every batch. A table that is mostly read can carry more indexes.
Keep the Whole Workload in View
Check the effect on other queries before keeping an index change. An improvement for one statement is useful, but the database serves more than one statement. My performance tuning work follows that broader view.
For the unused side of the same trade, read Index Slows Down SELECT? What an Unused Index Costs You. For the width of an index, read Wide Covering Indexes: The Cost of INCLUDE Everything.
A new index is not free, it is a trade you can measure.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

18 Comments. Leave new
Hi,
Can you elaborate each point with example ?
Anyone ?
Thanks.
Dear sir,
That picture tells me that,the GREEN MAN knows the structure of the database and the BLACK MAN’s knowledge on the subject……
Very nice cartoon… Indexes are not the painkillers.
I gues you meant indexes are not the ONLY painkillers
Yes, indexes aren’t silver bullets. One should consider them carefully and check that after index has been created it is actually used. Otherwise you end up index which slows inserts and does no good on selects.
But I’m seeing more and more totally non-indexed databases these days. Even databases which has tables without clustered index. There’s one database which was crawling because a single select could do thousands table scans. In these cases it is totally safe to blurt “create index on it”.
We nice cartoon indeed. Thanks for solving the confusion. Would like to hear on those points in more detail in future post. Thanks
Yes It is very nice cartoon presented. In Most of cases when we get issue on query performance we seen same answer that is indexing.
Cartoons are Great way to communicate the message, you have used cartoons in your earlier posts also and are very nice!
Indexing is a critical issue and Planning of them should be done carefully. Which fields to be made as clustered indexed and their data type(ideally should be of fix width and non nullable). Which fields to be used in non clustered index? Also Covering Indexes and Filtered Indexes. Creating Indexes is important but too many indexes can also cause performance issues. Monitoring, Indexes that are not in use and fragmentation of Indexes. Using Re-Organize and Re-Build(should be used when fragmentation is quite high as it can cause huge transaction logs, in full recovery mode). In all it is a very important aspect of performance tuning.
I agree with everyone on expanding on each point mentioned above.
If you can expand on each of those above mentioned performance tuning points as a series of posts, you’ll be a real life saver for many..
Hi Pinal,
Nice cartoon..
Always I can see, you suggest people to tune up Indexes for query performance, and that is good practice indeed.
But I believe joins used in query also affects in different ways. Tuning up Joins in proper way can improve the performance.
Sometimes we use Join with select query with join statement and sometimes we use table name with join statement.
Can you please write about using smart ways of using joins to improve performance.
When not to use sub queries and when not to use joins.
You wrote about basics of joins here
http://blog.sqlauthority.com/2009/04/13/sql-server-introduction-to-joins-basic-of-joins/
It will be my pleasure if you write or refer some article for best ideas of using joins and sub queries, when to use and not to use.
Can you write about how to identify and understand “Execution Plans”
Thanks a lot for all your Posts..
Hi all readers, please give your suggestions and ideas about my question.
Thanks.
The cartoon clearly illustrates how performance issues are dealt with, like a quick fix without analyzing the root cause.
I found dealing with a database in which some tables gained 2 to 3 millions rows per day really focused the mind on indexing. With that amound of data loading, too many indexes can be a big problem too. I have come accross developers who just index every column in a database, “just to be on the safe side”. Once you have the painful experience of trying to insert large amounts of data regularly into tables with lots of indexes it focuses the mind.
I also found different versions of SQL Server behave differently. When loading millions of rows into SQL Server 2000 it proved best to drop the indexes, do the insert and rebuild them. With the same system on SQL Server 2005 it is no longer neccessary to do that.
“I have come accross developers who just index every column in a database”
I wrote a script that goes through every index in the db, checks if they aren’t used and returns how many kilobytes they take disk space. I ran it through one of our badly behaving database and got some interesting results. Unused indexes, that were probably inserted “just to be sure”, takes space A LOT and are updated a lot. So they are there just ruining performance.
At the same time there are some queries that needs indexing badly. Although tables has indexes they aren’t used because all the joins and indexes doesn’t match.
Marko,
Your script sounds very interesting. I did write an application that did a similar things using SQL SMO, reporting on the tables and indexes in a database and how much space they used. In fact, it could do this for all databases on all Servers on a network . However, I did not even think about the issue of checking if an index is used or not. I would love to know how you checked in an index is used or not.
I don’t have the original one at hand but I used something like this.
select o.name table_name, i.name index_name, user_seeks, user_scans, user_lookups, user_updates, used_page_count * 8 used_kb
from sys.dm_db_index_usage_stats s
join sys.objects o on o.object_id = s.object_id
join sys.indexes i on i.object_id = s.object_id and i.index_id = s.index_id
join sys.dm_db_partition_stats ps on ps.object_id = i.object_id and ps.index_id = i.index_id
where s.database_id = db_id() — only current database
and s.index_id > 1 — omit heaps
and (user_seeks = 0 and user_scans = 0)
order by used_kb desc
Weicco,
Thanks for this, I will try it out.
Could you share the script you used?
Hi Pinal,
This cartoon is OK but if query is not working, this is always good to first check if indexes are required for the given query and if required, then if indexes are present or not. Indexes are not the fix for everything but they come first into the line of fire. In other words, if you have a table of a million rows and you select from this table with a column in WHERE clause, then what can you do, to get the results faster, other than creating an index?
Again, as obvious, optimization on creation of indexes is required to depending on amount of SELECTs vs INSERTs/UPDATEs/DELETEs in the system.