
Question: How do you find the cardinality or uniqueness of a column? Count distinct values, then decide what comparison you need.
This came up in my SQL Server Performance Tuning Practical Workshop. We were discussing cardinality estimation and compatibility levels. A participant asked what cardinality meant for one column.
It’s a fair question. In this context, the distinct-value count tells us how many different values the column contains. Dividing that count by a row count gives a ratio, not the percentage of rows that occur only once.
SELECT COUNT_BIG(*) AS total_rows,
       COUNT_BIG(SalesOrderID) AS non_null_rows,
       COUNT_BIG(DISTINCT SalesOrderID) AS distinct_values,
       CAST(COUNT_BIG(DISTINCT SalesOrderID) * 100.0
            / NULLIF(COUNT_BIG(SalesOrderID), 0) AS decimal(6,2))
            AS distinct_to_non_null_pct
FROM AdventureWorks2025.Sales.SalesOrderDetail;
The query names both counts so the denominator is visible. COUNT_BIG(DISTINCT ...) excludes null values. Here the denominator also excludes nulls, and NULLIF avoids division by zero for an empty or all-null column.
A ratio is not a uniqueness constraint
A small example makes the distinction clear:
DECLARE @Example table (Value int NULL);
INSERT @Example VALUES (10), (10), (20), (NULL);
SELECT COUNT_BIG(*) AS total_rows,
       COUNT_BIG(Value) AS non_null_rows,
       COUNT_BIG(DISTINCT Value) AS distinct_values,
       CAST(COUNT_BIG(DISTINCT Value) * 100.0
            / NULLIF(COUNT_BIG(Value), 0) AS decimal(6,2)) AS distinct_to_non_null_pct
FROM @Example;
The result is four total rows, three non-null rows, two distinct values and a 66.67% ratio. Only the value 20 appears once. The two rows containing 10 aren’t individually unique.
A ratio of 100% among non-null rows means those values don’t repeat in the current data. It doesn’t prevent future duplicates. A suitable UNIQUE constraint or index enforces that rule.
I use these counts to understand the data before discussing indexes. I wouldn’t choose an index from this ratio alone. Predicate values, distribution, statistics and the actual workload still matter.
Want to try this yourself? Here is how to install AdventureWorks.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

1 Comment. Leave new
Hi Pinal,
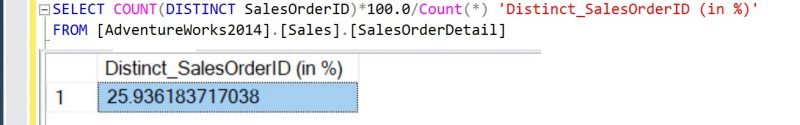
I’m having trouble understanding the true meaning of the single cardinality percent number (25.936% in your example). I also don’t have a copy of AdventureWorks handy, so I created a simple example:
Create database NutriciousFoods;
go
Use NutriciousFoods
go
create table Foods
(
product varchar(50) not null primary key,
category varchar(50) not null
);
create index idxCategory on Foods (category);
insert into Foods (product, category) values (‘Tomato’, ‘Vegetable’);
insert into Foods (product, category) values (‘Broccoli’, ‘Vegetable’);
insert into Foods (product, category) values (‘Celery’, ‘Vegetable’);
insert into Foods (product, category) values (‘Lettuce’, ‘Vegetable’);
insert into Foods (product, category) values (‘Spinach’, ‘Vegetable’);
insert into Foods (product, category) values (‘Arugula’, ‘Vegetable’);
insert into Foods (product, category) values (‘Apple’, ‘Fruit’);
insert into Foods (product, category) values (‘Pear’, ‘Fruit’);
insert into Foods (product, category) values (‘Banana’, ‘Fruit’);
insert into Foods (product, category) values (‘Grape’, ‘Fruit’);
go
— Look at data
select * from foods
order by category, product;
— Determine Cardinality or Uniqueness using Pinal’s formula:
SELECT COUNT(DISTINCT category)*100.0/Count(*) ‘Distinct_Category (in %)’
FROM dbo.Foods;
–> Result = 20%
Question # 1) When considering the above data, what does this 20% refer to?
I created the above table in Oracle, insert the same data, and then use the ratio_to_report method, I get values that makes perfect sense:
select category, (ratio_to_report(count(*)) over() * 100) as “PctTotal”
from foods
group by category
order by category;
–> Category PctTotal
Fruit 40%
Vegetable 60%
This type of information seems more useful, where one gets a percentage for each unique item. I believe this type of information is useful to help troubleshoot parameter sniffing issues.
Question # 2) What is the easiest way in SQL Server to get the same type of information that Oracle’s ratio_to_report displays? I was able to create a query that uses two Common Table Expressions, but I’m wondering if there might be an easier way to get the same result:
with v
as (
select distinct category, Cast(count(*) as decimal) As CategoryCount
FROM dbo.Foods
group by category
),
t
as (
select count(*) as TotalRows FROM dbo.Foods
)
select category, (CategoryCount*100 /TotalRows) as PctTotal
from v, t
order by PctTotal;
Thank You,
Tom