
Interview question: How do you add a column at a specific location in a SQL Server table?
Answer: ALTER TABLE ... ADD appends the new column to the table definition. If you want a different display order, name the columns in that order in SELECT. Changing the table definition’s ordinal position requires rebuilding the table and is usually unnecessary.
I have heard three reasons for wanting a column in the middle. They sound persuasive until we separate how a table is defined from how a result is presented.
The Result Looks Wrong With SELECT *
Yes, SELECT * shows columns in the table definition’s order, and adding a column puts it at the end. But an application or report should ask for the columns it needs, in the order it wants them:
-- Open a fresh query window; do not replace an existing temporary table.
IF OBJECT_ID(N'tempdb..#Orders') IS NOT NULL
    THROW 50126, 'Temporary demo table exists. Open a fresh window.', 1;
CREATE TABLE #Orders (OrderId int, Quantity int);
INSERT INTO #Orders (OrderId, Quantity) VALUES (1, 3);
ALTER TABLE #Orders ADD Note nvarchar(100) NULL;
SELECT OrderId, Note, Quantity
FROM #Orders;
DROP TABLE #Orders;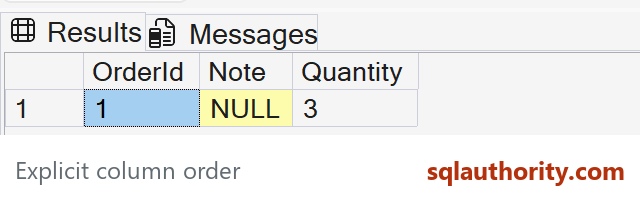
Note was added last, yet it appears between the other two columns in the result. Naming columns also prevents a later schema change from unexpectedly altering an application’s SELECT * result shape.
The Table Looks Untidy in the Designer
I understand the desire to group related columns visually. That preference alone rarely justifies rebuilding a populated table. Re-creating it can affect dependencies, permissions, metadata and downtime. SQL Server Management Studio blocks that sort of designer change by default for a reason. Keep the definition stable and order columns in the query or report where the order matters.
Adjacent Columns Must Make a Query Faster
I once compared this claim to saying that learning to swim helps you drink water. Both topics involve water, but one doesn’t follow from the other. Likewise, two columns appearing next to each other in a result doesn’t make a query faster. Check the actual plan, reads, indexes and predicates when performance is the concern. A deliberate index can matter far more than the table designer’s visual column sequence.
There can be specialized storage and row-layout considerations when a table is redesigned. Those need measured evidence for a real workload, not a blanket rule to move two frequently selected columns side by side.

Column order is not a table problem, it is a SELECT list choice, so name your columns.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

6 Comments. Leave new
I am not satisfied of your solution 2.
Yes, you are right, but sometimes you want a select * to return something beautiful, with all the things where you expect them. Yes, this is irrational :-)
But when you have some serious downtime available, you can still copy all data to a new table, delete the old one and rename the new to replace the old. Of course, FK must also be taken care of.
I understand and appreciate the answers and commentary to the question presented in this article (and mostly agree). But I think the real answer should be: “You can’t, unless you recreate the table with the new column and migrate the data.” Followed by the commentary above and additional points on why recreating the table is, generally speaking, probably a bad practice.
Love the blog!
I get what you are saying in THEORY, but in PRACTICE I dIsagree. When doing interactive data analysis on tables with a large number of columns, I find that SELECT * is useful when you may not know which column has the data you are looking for. Keeping columns logically grouped/ordered is helpful. If you want to see an example of a mess caused by the inability to place columns in logical order, look at MS Dynamics CRM tables.
Ideally, SQL Server would have a clause in the ALTER TABLE statement like Informix SQL has (I used Informix in past life).
It was basically of the format: ALTER TABLE tablename ADD newcolumn TYPE BEFORE existingcolumn
I agree with Mark’s comment regarding the correct answer to this question.
I also think the theoretical reasons for SQL behaving this way should have been pointed out. Namely, SQLs origins in Relational Database Theory.
A table in SQL is a set, with every row being an element of that set.
Each element has attributes that apply to that specific element.
The attributes in SQL are columns.
When you want a specific element, for example Customer, it’s meaningful to talk about the Name, or Address.
It’s not meaningful to say give me all Customer’s where [Attribute 9] contains Texas.
That’s not a RDBMS, that’s a list.
It goes to the heart of SQL that the columns of an row have no order.
See first paragraph https://en.wikipedia.org/wiki/Relation_(database)
I’m firmly in the camp of never relying on the ordinal position of the columns for anything. But playing devil’s advocate, you could also create a view which can be altered at any time (thus also altering the ordinal of each returned column.
Totally disagree. What about using nice way to copy table structure using {select top 0 * into [#mytbl] from [mytable]}? What about replacing totally hardcoded unpivot structure to transform columns to rows using xml and *? You must hardcode all columns, right? So, you need rewrite your code after table columns updated? No. Just use xml with * instead of hardcody unpivots. What about programmability comfort, when you have large set of colums, but, theyre related logically? Code readability does not matter? What about adding column after rowversion column, and before it? Hudge, hudge difference!
So, my opinion is: wrong answer, no job. Right answer is: you need recreate table, if adding column to not last position. And please comfortably, but with arguments use *. And using normal forms to infinity is waste of time and code readability. Need to keep smart balance here.