
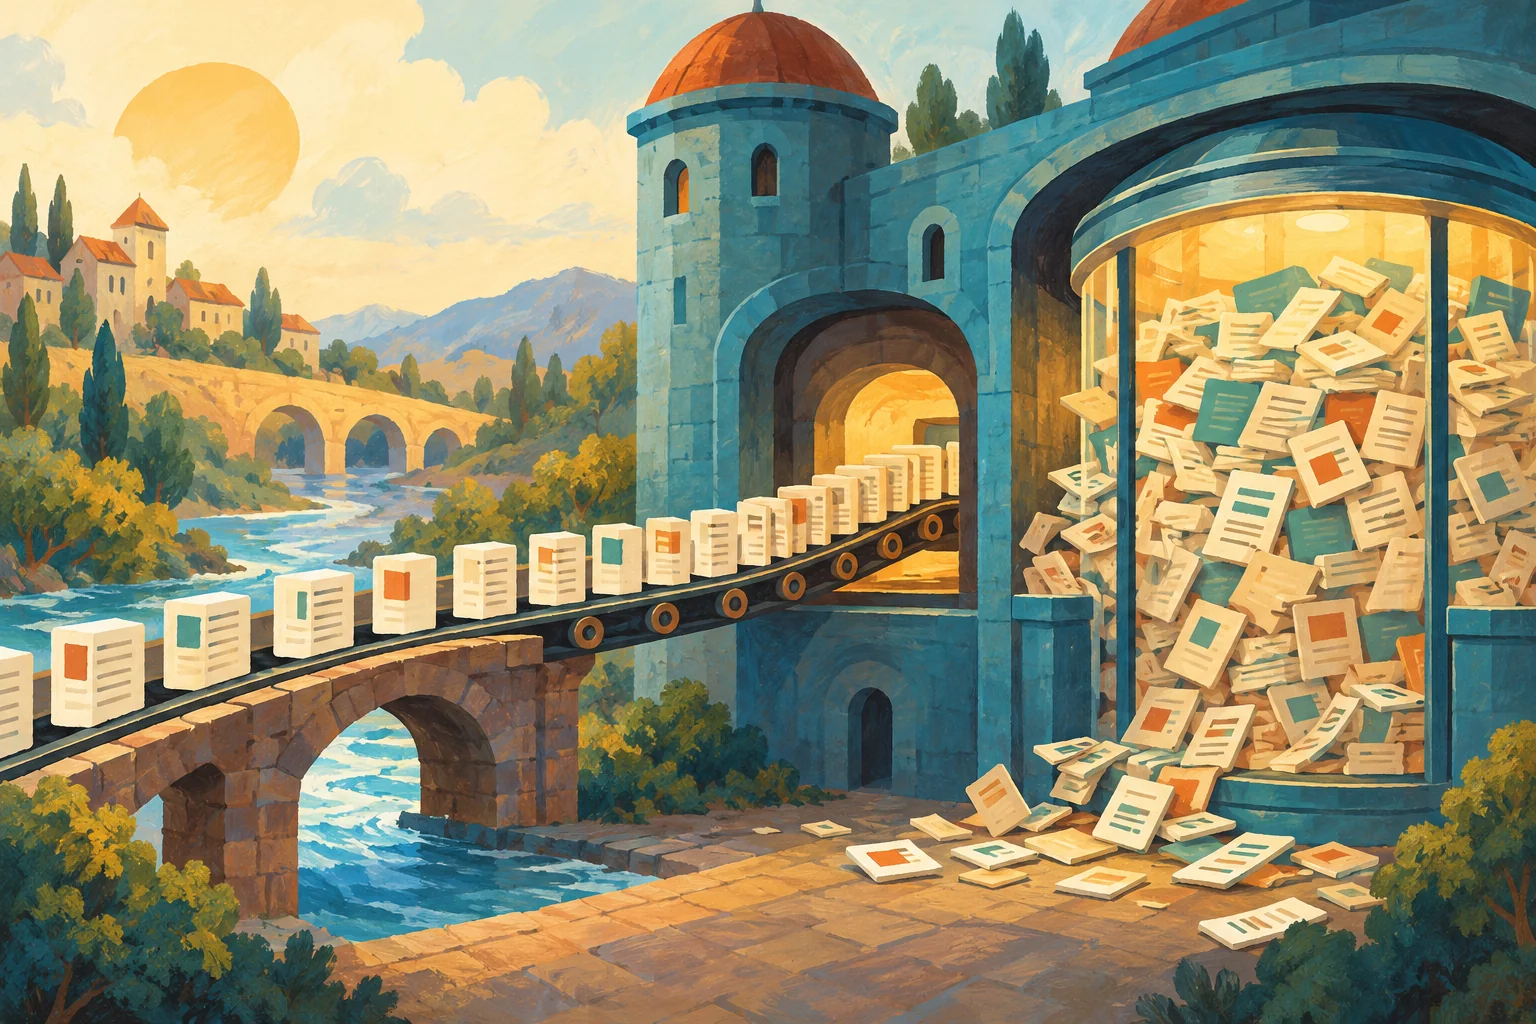
A growing redo queue means a secondary has log records waiting to be applied. In this 2018 client case, an availability group had one primary, one synchronous secondary and one asynchronous secondary. Both secondaries developed increasing redo queues, and the logs repeatedly reported that the version store was full.
The Evidence in This Case
The investigation observed a latch wait associated with APPEND_ONLY_STORAGE_FIRST_ALLOC and the following error:
The version store is full. New version(s) could not be added.
A transaction that needs to access the version store may be rolled back.
Please refer to BOL on how to configure tempdb for versioning.
The drive containing tempdb was short of space, and tempdb could not grow. That was the finding in this case. A latch name alone does not establish the cause of every redo delay.
Measure the Local Secondary
Run this query directly on the affected secondary. It reports local AG databases; an instance without an availability group can return no rows. Run these diagnostic queries with appropriate server visibility. The state DMVs require VIEW SERVER STATE on SQL Server 2019 and earlier, or VIEW SERVER PERFORMANCE STATE on SQL Server 2022 and later. Catalog metadata is also limited by the permissions of the login.
SELECT DB_NAME(database_id) AS database_name,
       synchronization_state_desc, synchronization_health_desc,
       is_suspended, suspend_reason_desc,
       redo_queue_size AS redo_queue_KB,
       redo_rate AS redo_rate_KB_per_second,
       last_received_time, last_hardened_time, last_redone_time
FROM sys.dm_hadr_database_replica_states
WHERE is_local = 1
ORDER BY database_id;
The redo queue and rate are in KB and KB per second. Take samples over time and compare them with workload and storage activity. The reported rate is based on periods when redo was active; dividing the queue by that rate is not a guaranteed catch-up time.
Synchronous commit confirms log hardening on the required synchronous secondary, not that every record has already been redone for readers. A large redo queue can therefore coexist with synchronous commit, delay readable results and increase failover recovery time.
To inspect requests for the affected database, replace the placeholder below. The result may be empty if the name is wrong, the activity has finished or the relevant work is not represented as a current request. Use it alongside error logs and AG monitoring.
DECLARE @DatabaseName sysname = N'YourAGDatabase';
SELECT session_id, command, status,
       wait_type, wait_time, last_wait_type,
       wait_resource, blocking_session_id
FROM sys.dm_exec_requests
WHERE database_id = DB_ID(@DatabaseName)
ORDER BY session_id;
Check Tempdb Capacity and the Volume
USE tempdb;
GO
SELECT SUM(CAST(version_store_reserved_page_count AS bigint))
           / 128.0 AS version_store_MB,
       SUM(CAST(unallocated_extent_page_count AS bigint))
           / 128.0 AS free_extent_MB
FROM sys.dm_db_file_space_usage;

SELECT f.name, f.type_desc, f.size / 128.0 AS file_size_MB,
       f.max_size, f.growth, f.is_percent_growth,
       v.volume_mount_point,
       v.available_bytes / 1048576.0 AS volume_free_MB
FROM sys.database_files AS f
CROSS APPLY sys.dm_os_volume_stats(DB_ID(), f.file_id) AS v
ORDER BY f.file_id;
The first result measures tempdb version-store reservations and free extents. The second shows file size, growth settings and free space on the underlying volume. max_size and non-percent growth are in 8 KB pages; max_size = -1 means growth is not capped by that file setting, while growth = 0 disables automatic growth. It does not create extra disk capacity.
Several files can share one volume, so do not add the repeated volume-free values together. Also check file limits and failed-growth messages. Version storage depends on SQL Server version and ADR configuration; this tempdb counter does not describe every possible persistent version store.
For disk-based tables, readable secondaries use row versions to provide snapshot-based reads. Tempdb can also hold temporary statistics and query workspace. Long-running reads can increase retention pressure. The original article linked to Microsoft’s readable secondary replica guidance, which explains this workload.
The Workaround Was Specific to the Incident
The client temporarily disabled read access on both secondaries. The original notes report that version-store pressure fell and redo caught up. That describes the observed incident; it is not a guarantee that disabling reads will immediately remove every version or resolve an unrelated redo bottleneck.
Restricting secondary reads can interrupt reporting and read-only routing. Plan that operational change with the application owner, and address the capacity or workload cause. Do not start by shrinking tempdb: a file that needs to grow for normal work still needs that capacity. The original shrink step is not a general recommendation.
When space is available, investigate other causes such as I/O latency, CPU contention, suspended data movement, blocked redo and heavy read workloads. Compare measured queue progress after the chosen change. The local verification for this refresh checked the read-only scripts, not a live reproduction of this multi-replica incident.
A redo queue is not a diagnosis by itself, it is a measure of work the secondary has yet to apply.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

1 Comment. Leave new
I am having this same issue your user was having but my tempdb has 162gb of space and is only 36gb on 6 6gb files.
I have very fast sendrates but then the redo rate is literally only 25k on this one server but I have 4 other nodes where servers have 120k-250k redo rates. Which causes my 1 server to fall behind on redo rate and I don’t know why :'(