
My index optimization checklist fits on one page, and I hand it to every junior DBA before I open a slow query. Most slow queries trace back to a handful of boring mistakes. Fix those first, and the interesting tuning, the part that needs experience, starts from a clean table.
The one-page checklist
These are the twelve rules I check, in the order I check them. All twelve are also on the card right below the list, so you do not have to print the whole page.
- Give every queried table a clustered index. A heap is fine for a staging table, not for a table people read.
- Keep the clustered key narrow, unique and steady. An ever-increasing int is the usual winner, because every other index carries a copy of it.
- Create the clustered index first. Adding it later rewrites every nonclustered index.
- Index what you filter and join on. WHERE and JOIN columns come first, foreign keys included.
- Equality columns first, range column last. Column order inside the key matters a lot.
- Keep keys narrow and use INCLUDE for the rest. Wide keys cost space in every index level.
- Do not index a column with few distinct values on its own. A four-value status column rarely earns an index alone.
- Drop duplicate and unused indexes. Each one slows every insert, update and delete.
- Treat missing-index suggestions as hints. Check them against indexes you already have.
- Keep statistics fresh and rebuild by need. Reorganize or rebuild only large, badly fragmented indexes.
- Build with SORT_IN_TEMPDB when tempdb sits on its own fast disk. It is an option on CREATE INDEX.
- Look at the actual plan after every change. An index you never saw used is only a guess.
Print this card. Open it in its own tab and print it, and it fits on one sheet. Keep it next to your desk and tick each rule before you start tuning.

I retired two old rules from my own list. “Rebuild indexes frequently” was a calendar habit, not a tuning step. “Most selective column first” is not a rule either, as you will see below.
Find the heaps first
I will build a demo with two small tables. DemoOrders has a clustered primary key and three nonclustered indexes. DemoLog has nothing at all. The setup also loads 100,000 order rows.
DROP TABLE IF EXISTS dbo.DemoLog;
DROP TABLE IF EXISTS dbo.DemoOrders;
CREATE TABLE dbo.DemoOrders (
    OrderId int NOT NULL CONSTRAINT PK_DemoOrders PRIMARY KEY CLUSTERED,
    CustomerId int NOT NULL,
    OrderDate date NOT NULL,
    Filler char(100) NOT NULL DEFAULT 'x');
CREATE TABLE dbo.DemoLog (LogId int NOT NULL, Message varchar(100) NOT NULL);
CREATE INDEX IX_Demo_Customer ON dbo.DemoOrders (CustomerId);
CREATE INDEX IX_Demo_CustomerDate ON dbo.DemoOrders (CustomerId, OrderDate);
CREATE INDEX IX_Demo_DateCustomer ON dbo.DemoOrders (OrderDate, CustomerId)
    WITH (SORT_IN_TEMPDB = ON);
INSERT dbo.DemoOrders (OrderId, CustomerId, OrderDate)
SELECT n, n % 500, DATEADD(day, n % 1095, '2024-01-01')
FROM (SELECT TOP (100000) ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) AS n
      FROM sys.all_objects AS a CROSS JOIN sys.all_objects AS b) AS t;
Now rule one. This catalog query lists tables that are heaps.
SELECT s.name AS SchemaName, t.name AS TableName
FROM sys.tables AS t
JOIN sys.schemas AS s ON s.schema_id = t.schema_id
JOIN sys.indexes AS i ON i.object_id = t.object_id AND i.type = 0
ORDER BY s.name, t.name;
It returns DemoLog and nothing else. On a real server, expect a longer list. Some heaps are on purpose. The rest deserve a conversation.
Equality first, range last
The question is simple. Which orders did customer 42 place in March 2025? Two indexes hold the same two columns in opposite order. Same query, same rows, one index hint each.
SELECT COUNT(DISTINCT CustomerId) AS Customers, COUNT(DISTINCT OrderDate) AS Dates FROM dbo.DemoOrders;
SET STATISTICS IO ON;
SELECT COUNT(*) AS OrdersFound
FROM dbo.DemoOrders WITH (INDEX (IX_Demo_CustomerDate))
WHERE CustomerId = 42 AND OrderDate >= '2025-03-01' AND OrderDate < '2025-04-01';
SELECT COUNT(*) AS OrdersFound
FROM dbo.DemoOrders WITH (INDEX (IX_Demo_DateCustomer))
WHERE CustomerId = 42 AND OrderDate >= '2025-03-01' AND OrderDate < '2025-04-01';
SET STATISTICS IO OFF;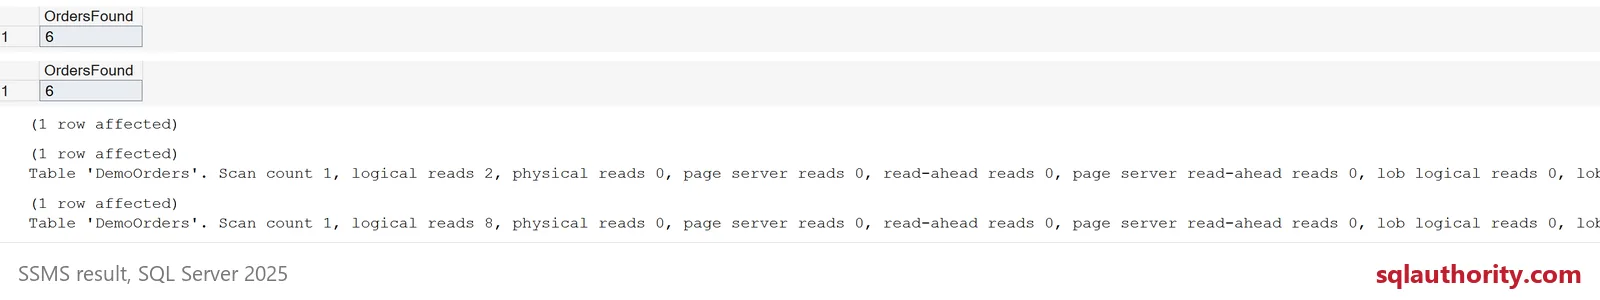
Both queries find the same 6 orders. The reads differ. The customer-first index needs 2 logical reads and the date-first index needs 8. The index starts at customer 42 and reads one tight slice. The other index walks the whole month of every customer, then discards most of it. Note that the table has 1,095 distinct dates but only 500 customers. The more selective column was the date, and it still lost. Equality first is the better rule. The gap grows with the table.
Spot duplicate and unused indexes
First, list the key columns of each nonclustered index.
SELECT i.name AS IndexName,
       STRING_AGG(c.name, ', ') WITHIN GROUP (ORDER BY ic.key_ordinal) AS KeyColumns
FROM sys.indexes AS i
JOIN sys.index_columns AS ic ON ic.object_id = i.object_id AND ic.index_id = i.index_id
JOIN sys.columns AS c ON c.object_id = ic.object_id AND c.column_id = ic.column_id
WHERE i.object_id = OBJECT_ID('dbo.DemoOrders') AND i.type = 2
GROUP BY i.name
ORDER BY i.name;
IX_Demo_Customer and IX_Demo_CustomerDate both start with CustomerId. The first can answer nothing the second cannot, so it is a duplicate in all but name. Next, check which indexes anyone reads.
SELECT i.name AS IndexName,
       ISNULL(u.user_seeks + u.user_scans + u.user_lookups, 0) AS Reads,
       ISNULL(u.user_updates, 0) AS Writes
FROM sys.indexes AS i
LEFT JOIN sys.dm_db_index_usage_stats AS u
       ON u.object_id = i.object_id AND u.index_id = i.index_id AND u.database_id = DB_ID()
WHERE i.object_id = OBJECT_ID('dbo.DemoOrders') AND i.type = 2
ORDER BY Reads, i.name;
IX_Demo_Customer shows 0 reads and 1 write. It is paying for every insert and earning nothing. Two cautions. These counters reset when the server restarts, so check after a full business cycle. And a clustered or unique index may exist for a reason beyond reads. Once the checklist is done, the fun part begins: real workloads, real plans, and experiments.
DROP TABLE IF EXISTS dbo.DemoLog;
DROP TABLE IF EXISTS dbo.DemoOrders;
Pin this list up, then go and run the queries on your own server.
An index is not free speed, it is a bill paid on every write.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.


16 Comments. Leave new
Hi skareEmOff,
I do not think that is possible.
Regards,
Pinal Dave (SQLAuthority.com)
Hi,
I have a question about clustered indexes. Is it possible to configure SQL server to create a non-clustered index for a primary key by default?
I am trying to keep my SQL vendor-independent and in standard SQL I can not specify non-clustered as many DBs will not accept it.
thank you in advance
Hi Gopal,
Thanks you very much.
Yes, index is integer columns performs way better than datetime columns too.
Kind Regards,
Pinal Dave (SQLAuthority.com)
Hi Pinal,
I understand that
Index on Integer Columns performs better than varchar columns
But do Index on Integer Columns performs better than datetime columns too? or they are same? I think later.
Also I must compliment the work you are doing. All I can say is after spending time on this site (which went right up there to my favourite’s) I am more motivated to know all about sql server.
Thanks.
Best Regards,
– Gopal
By definition the Primary Key is a clustered unique index but if you really would just rather put the clustered index on a different set of fields that you can just change the index on the Primary key and make it just a unique index and then use the clustered index for whatever fields you like.
Hi Pinal
Love your blog, always very useful for reference. Just out of interest, if we have large db tables with 100m+ rows will an index on a datetime field (low selectivity) perform much worse than an index on a derived (or computed) integer column?
This the above assuming that we are only concerned with the date part and not time for these queries….
Would be interested in finding out your expert opinion…. ;-)
Thanks and keep up the good work.
Andrew
Hi Pinale,
Your last sessions in the tech-ed india 2011 was fantastics.
Thanks for that. I have attended both of them.
Here one doubt on indexing.
Is it a good idea to index datetime columns.
Lets say we have a table in which we keep daily transaction details. The table size is very large and at any time we only required the today’s transaction of the user.
So I was thinking of indexing by date column desending and after that by the user id ascending.
Please share your views
Thanks
Aditya
Yes create an index on the datetime column and make sure you use the query in such a way that it will make use of the index
Hi Pinal,
I want to know about the Index fill factor, Index fragmentation and defragmentation, Paging and linking of indexes.
I know all about the above, but not have confidence on the same, so if you can provide some book or link reference for the same, it would be highly appreciated.
Best Regards,
Mahesh
Hi Pinal,
I have several questions that i’d like to ask
1. How could we check if the indexes that we have created were good or bad i.e. degrading the performance, or overlap with other indexes? I am afraid that i’ve added too many indexes that causing degradation in my application.
2. Is there a way to delete several indexes and statistics all at once without knowing the full name and the table name i.e. only part of the indexes or statistics name.
Your blog is very informative, thanks for sharing :), keep up the good job.
Thanks,
Adi
These are not true:
– “Each table must have one Clustered Index.”
– “Clustered Index must exist before creating Non-Clustered Index.”
That can be a recommendation, but not a “must”.
Primary key and unique constraint are logical constructs (constraints) that are phisycally backed-up by an unique index. All three of them: PK, unique constraint and unique index can be created as NONCLUSTERED if you specify that keyword, and you surely can have a table without a clustered index.
Such tables are called HEAPS. It is just a type of physical structure, as CLUSTERED structure also is.
Developer and DBA should know when it is better for a table to use heap, and when it is better to have clustered index structure of a table. If you are not sure – measure and be sure!
If you have a table that is rarely accessed by a primary key (no child tables that reference it, e.g. fact table), and it is wide (has many columns), and frequently modified (heavy on insert/update/delete), you should try with a heap as a phisycal structure.
Each phisycal structure should be considered and used when appropriate.
I would add a very neat new feature of SQL 2008: FILTERED INDEXES.
Ordinary clustered or non-clustered indexes always have exactly the same number of rows as the table they are created on. For huge tables, you have huge indexes (although smaller than table itself).
If you are interesting in fetching just a small portion of rows, e.g. non-processed rows in a large table that has 99.9% of rows which are “processed”, you will benefit from filtered index greatly.
It will be very very small compared to the table, and lightning-fast, containing only rows you are interested in (un-processed).
You can have partitioned indexes on non-partitioned tables or non-partitioned (global) indexes on partitioned table. Or pertitined index and partitined table by a different partitioning schema. But if you have the same partitioning schema for table and all it’s indexes, you get some benefits (easy and super-fast EXCHANGE PARTITION feature is one of them).
Almost every detail about the indexes and their structure, how they are partitioned, what space so they take, are they used at all and much much more you can see with this add-in for SQL Management Studio:
http://www.sqlxdetails.com
Great source!
2 questions:
1. Is a qood idea to have GUID as PrimaryKey on a table? (Clustered index)
2. In case of a 2 column index (non clustered index). One column is GUID (the first -left) and the other is int (possible values: 5) (the right column-2nd). Is there a meaning in changing their order with respect to performance?
1) Short answer: guid is not a very good clustering key. Try alternative solutions. Long answer: GUID takes 16 bytes, and every NC (non-clustered) index on that table will also become wider for 16 bytes per row. That can add-up considerably and slow your system. Another thing is fragmentation (table will become very fragmented very fast, and thus will be slower than optimal), but you can partially avoid it by using NEWSEQUENTIALID() instead of NEWID() function to generate new values. Much better is to use int identity, not null. If you have replication, you can have CL key of two columns: (INT identity, smallint – replication id) which is 6 bytes, much less than 16. Primary key and clustered index are two different and independant things. Choose clustering key wisely, does not have to consist of PK columns at all.
2) For queries that filter both fields there is no measurable difference. But for queries that filter just guid, you should have guid as first column. For queries that filter just on int column, you should not have index because it is not selective and sql would go to full scan anyway. So, (guid,int) is only logical option here.
Don’t be afraid of wider indexes (2-5 key columns, and bunch of included). Consolidate similar indexes into one wider and you will get better overall performance. One has to learn a lot to get the true knowledge about how to do it properly.
HI Pinal,
Can you please explain in detail the difference between cluster index seek (clustered) and Index seek (Nonclustered)..Thanks in advance
If a table has 10 indexes and 5 indexes are useful for a query then how many indexes does SQL server use?
Hi Pinal
What is the difference between Rebuild and Reorganize?
Thanks