
Make loading only new rows repeatable with NOT EXISTS, EXCEPT, source deduplication, and a unique key that protects the destination.
Join Duplicates: Stop Hiding Extra Rows With SELECT DISTINCT
Diagnose join duplicates before using DISTINCT, verify order and payment totals, and choose aggregation or EXISTS for the required result.
Finding Near-Duplicate Rows With REGEXP_REPLACE
Find near-duplicate rows with SQL Server 2025 normalization, group matching labels, rank survivors, and preserve originals for review.
Comparing Data Between Two Tables
Comparing data between two tables uses EXCEPT, full joins, and hashes, with explicit NULL and duplicate rules for trustworthy results.
Data Governance: Catalog, Lineage and Data Quality
Data Governance is how you know what data you have, where it came from, who can see it and whether it is right. This post covers the catalog, lineage, access and data quality, with T-SQL checks you can run.
Unique Constraint on Existing Table: How to Add One With ALTER TABLE
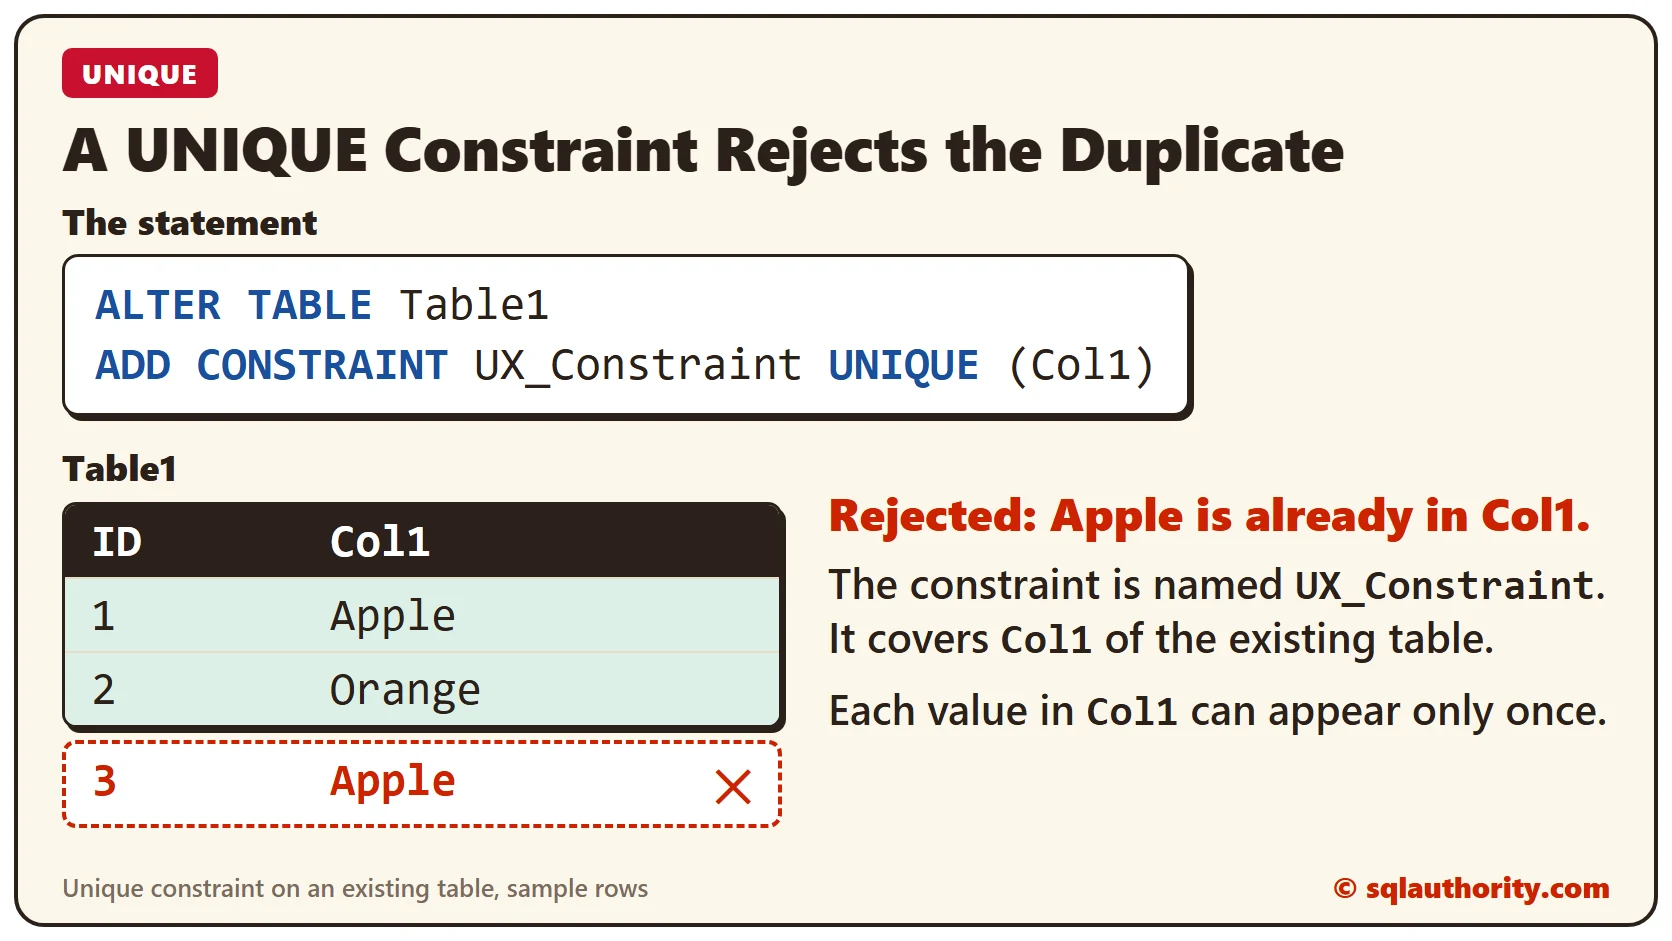
A unique constraint on existing table data takes one ALTER TABLE statement. Here is the script, the duplicate check to run first, and what to know about NULLs, indexes and names.
Finding Duplicate Customers With T-SQL
Find duplicate customers with T-SQL by normalizing names, reviewing fuzzy matches, and merging records only after ownership is settled.