
The memory used by each database is its count of data pages in the buffer pool. One view lists those pages, and a short query turns them into megabytes per database. The view is sys.dm_os_buffer_descriptors.
What the Buffer Pool Holds
The buffer pool is memory where SQL Server keeps copies of data and index pages after reading them from disk. It’s SQL Server’s own cache, not the operating system’s file cache. The view has one row for each 8 KB page in that pool. Group the rows by database and multiply the page count by 8 KB. The result is the memory used by each database for data.
A page is clean when it matches the copy on disk. It’s dirty when a change has not been written back yet. The checkpoint process writes dirty pages out. Both kinds occupy memory, so the query reports them separately.
Build a Database to Measure
The demo database holds one table with 5,000 rows. Each row is 4,000 bytes wide, so the table fills about 20 MB of pages. The load leaves those pages in memory, and most of them are dirty.
SET NOCOUNT ON;
IF DB_ID(N'MemoryByDbDemo') IS NULL CREATE DATABASE MemoryByDbDemo;
GO
USE MemoryByDbDemo;
GO
DROP TABLE IF EXISTS dbo.Seeds;
CREATE TABLE dbo.Seeds (SeedID int NOT NULL PRIMARY KEY, Notes char(4000) NOT NULL);
INSERT INTO dbo.Seeds (SeedID, Notes)
SELECT TOP (5000) ROW_NUMBER() OVER (ORDER BY (SELECT NULL)), 'x'
FROM sys.all_objects AS a CROSS JOIN sys.all_objects AS b;
Query the Memory Used by Each Database
This script groups the buffer pool by database to show the memory used by each database. The variable at the top limits it to one database for the demo. Set it to NULL and the script returns every database on the instance, largest first.
DECLARE @OnlyDatabase sysname = N'MemoryByDbDemo';
SELECT COALESCE(DB_NAME(b.database_id), N'Resource database') AS DatabaseName,
       COUNT_BIG(*) AS Pages,
       CONVERT(decimal(12,1), COUNT_BIG(*) * 8 / 1024.0) AS BufferMB,
       CONVERT(decimal(12,1), SUM(CASE WHEN b.is_modified = 1 THEN 1 ELSE 0 END) * 8 / 1024.0) AS DirtyMB
FROM sys.dm_os_buffer_descriptors AS b
WHERE @OnlyDatabase IS NULL OR b.database_id = DB_ID(@OnlyDatabase)
GROUP BY b.database_id
ORDER BY COUNT_BIG(*) DESC;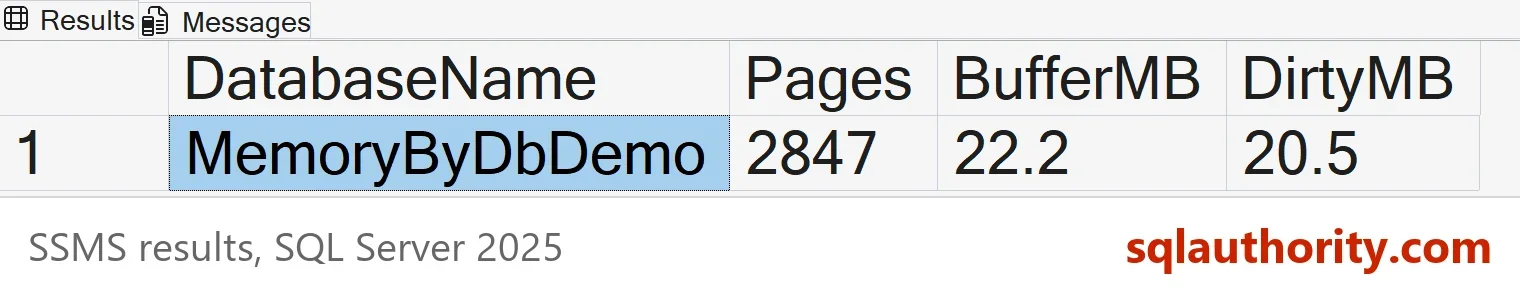
The table takes about 20 MB, and the database’s own system pages add a little more. Nearly all of it is dirty, because the load ended moments ago. Page counts vary by a few pages from run to run. The later results below come from another run, so they differ slightly from this picture.
Run a checkpoint, then the same query again. A checkpoint writes the dirty pages to disk and keeps them in memory as clean pages.
CHECKPOINT;
GO
DECLARE @OnlyDatabase sysname = N'MemoryByDbDemo';
SELECT COALESCE(DB_NAME(b.database_id), N'Resource database') AS DatabaseName,
       COUNT_BIG(*) AS Pages,
       CONVERT(decimal(12,1), COUNT_BIG(*) * 8 / 1024.0) AS BufferMB,
       CONVERT(decimal(12,1), SUM(CASE WHEN b.is_modified = 1 THEN 1 ELSE 0 END) * 8 / 1024.0) AS DirtyMB
FROM sys.dm_os_buffer_descriptors AS b
WHERE @OnlyDatabase IS NULL OR b.database_id = DB_ID(@OnlyDatabase)
GROUP BY b.database_id
ORDER BY COUNT_BIG(*) DESC;| DatabaseName | Pages | BufferMB | DirtyMB |
|---|---|---|---|
| MemoryByDbDemo | 2849 | 22.3 | 0.0 |
The memory stays the same, and the dirty share drops to almost nothing. That is why a database can use memory without causing any disk writes.
Find the Table Behind a Big Number
When one database stands out, the next question is which table fills it. The same view carries an allocation unit ID, so you can join it to the catalog from inside that database. This query lists user tables by buffer size.
SELECT OBJECT_NAME(p.object_id) AS ObjectName, COUNT_BIG(*) AS Pages,
       CONVERT(decimal(12,1), COUNT_BIG(*) * 8 / 1024.0) AS BufferMB
FROM sys.dm_os_buffer_descriptors AS b
JOIN sys.allocation_units AS au ON au.allocation_unit_id = b.allocation_unit_id
JOIN sys.partitions AS p ON p.hobt_id = au.container_id
WHERE b.database_id = DB_ID() AND au.type IN (1, 3)
  AND OBJECTPROPERTY(p.object_id, 'IsUserTable') = 1
GROUP BY p.object_id
ORDER BY COUNT_BIG(*) DESC;| ObjectName | Pages | BufferMB |
|---|---|---|
| Seeds | 2569 | 20.1 |
The demo table accounts for 20.1 MB of the 22.3 MB. The join covers in-row and row-overflow pages, which are allocation unit types 1 and 3. Large object pages join through another column. A table full of varchar(max) data needs a second branch in the query.
The Row With No Name
On a full instance you will see one row whose name is NULL before the label. The page belongs to database ID 32767, the hidden Resource database, which holds the system objects. DB_NAME returns NULL for it, so the script labels it. On the demo server it used about 18 MB. It’s real memory, but you can’t tune it.
What the Numbers Leave Out
You could argue that this is the memory a database uses, full stop. It isn’t, and the difference matters. The memory used by each database in this view covers data and index pages only. Compiled plans sit in the plan cache. In-memory OLTP tables and the columnstore object pool have their own memory clerks. The buffer pool count never includes them.
Plans can be assigned to a database through the dbid plan attribute. This query sums them for the demo database.
SELECT DB_NAME(CONVERT(int, pa.value)) AS DatabaseName, COUNT(*) AS CachedPlans,
       CONVERT(decimal(12,2), SUM(cp.size_in_bytes) / 1048576.0) AS PlanCacheMB
FROM sys.dm_exec_cached_plans AS cp
CROSS APPLY sys.dm_exec_plan_attributes(cp.plan_handle) AS pa
WHERE pa.attribute = N'dbid' AND pa.value = DB_ID(N'MemoryByDbDemo')
GROUP BY pa.value;| DatabaseName | CachedPlans | PlanCacheMB |
|---|---|---|
| MemoryByDbDemo | 5 | 0.71 |
Here the plans take about 0.7 MB against 22 MB of data pages. The plan cache size changes from run to run, and a later run showed six plans and 1.5 MB. The plan cache grows with the number of distinct queries, so a busy ad hoc workload fills it faster.
Cost and Meaning
The view returns one row per page. A server with 256 GB of buffer pool has about 33 million rows to read. Run the query off peak on big servers, and don’t schedule it every minute.
The count is also a snapshot. Pages come and go as queries run, and SQL Server decides what to keep. A small number right now doesn’t make a small database. A cold database, one nobody has read recently, shows little.
The old form of this query used COUNT(1) in one place and COUNT(*) in another. Both return the same value. Use COUNT(*) or COUNT_BIG(*) and keep it the same everywhere.
What to Remember
Read the buffer pool by database, and look at the dirty column next to the total. Add the plan cache when a database seems larger than its data. Then run the cleanup script.
USE master;
GO
IF DB_ID(N'MemoryByDbDemo') IS NOT NULL
BEGIN
    ALTER DATABASE MemoryByDbDemo SET SINGLE_USER WITH ROLLBACK IMMEDIATE;
    DROP DATABASE MemoryByDbDemo;
END;
Memory used is not the same as memory needed, it is what the server chose to keep.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

6 Comments. Leave new
This one is going in my scripts folder, thanks!
This is going to be really helpful on Monday…for “that” client and their 32GB RAM 600GB of databases
–Kevin3NF
I totally agree sir.
What about execution plan cache?
It has a NULL field with some MB calculated on that. Why is it so?
Why a COUNT(1) in the SELECT clause and a COUNT(*) in the ORDER BY clause?