
Resource bottlenecks show up in the wait statistics, once you remove the idle waits and measure a short interval. The raw view is a long list led by waits that mean nothing. This script cleans the list, measures an interval and groups the rest by resource.
Why the Raw Wait Numbers Mislead
The view sys.dm_os_wait_stats adds up every wait since the server started. Three problems follow. The totals cover days, so a problem from this morning hides in the history. Most of the time listed belongs to background threads that sleep by design. And a list of more than 1,500 wait types doesn’t tell you which resource is short.
A common sight is a single idle wait that holds more than 99 percent of the total wait time. On the test instance, the first five rows are all idle waits. Nobody should rank the raw list. To find resource bottlenecks, remove the idle waits, measure a short interval and group what is left by resource.
Step 1: Keep a List of Idle Waits
The first script builds the idle list in a temporary table. Each entry is a pattern for a LIKE comparison. In a pattern with a percent sign, the square brackets make the underscore match itself. A bare underscore matches any single character. The list is our own and short. Add a pattern when a wait type shows up that you know to be a background wait.
DROP TABLE IF EXISTS #IdleWait, #WaitBefore, #WaitAfter, #WaitDelta;
CREATE TABLE #IdleWait (WaitPattern nvarchar(80) NOT NULL PRIMARY KEY);
INSERT #IdleWait (WaitPattern)
VALUES (N'BROKER[_]%'), (N'CHECKPOINT_QUEUE'), (N'CLR[_]%'), (N'DIRTY_PAGE_POLL'), (N'DISPATCHER_QUEUE_SEMAPHORE'),
       (N'FT[_]IFTS%'), (N'HADR[_]FILESTREAM%'), (N'HADR[_]TIMER_TASK'), (N'HADR[_]WORK_QUEUE'), (N'LAZYWRITER_SLEEP'),
       (N'LOGMGR_QUEUE'), (N'MEMORY_ALLOCATION_EXT'), (N'ONDEMAND_TASK_QUEUE'), (N'PARALLEL_REDO_WORKER_WAIT_WORK'), (N'PRINT_ROLLBACK_PROGRESS'), (N'PVS_PREALLOCATE'),
       (N'PWAIT[_]%'), (N'QDS[_]%'), (N'REDO_THREAD_PENDING_WORK'), (N'REQUEST_FOR_DEADLOCK_SEARCH'),
       (N'SERVER_IDLE_CHECK'), (N'SLEEP[_]%'), (N'SOS_WORK_DISPATCHER'), (N'SP_SERVER_DIAGNOSTICS_SLEEP'),
       (N'SQLTRACE[_]%'), (N'WAIT[_]XTP[_]%'), (N'WAITFOR'), (N'XE[_]%'), (N'XTP_PREEMPTIVE_TASK');
Three entries answer common questions. PRINT_ROLLBACK_PROGRESS is the wait of a session that ends other sessions in a database. ALTER DATABASE with ROLLBACK IMMEDIATE does it. PWAIT_DIRECTLOGCONSUMER_GETNEXT and PARALLEL_REDO_WORKER_WAIT_WORK are waits of background log and redo threads. When one of them takes 99 percent of the wait time, the server is idle there.
Step 2: Measure an Interval
Now take a snapshot, let some work happen and take a second snapshot. The difference is what happened in between. In real use the work is whatever your server is doing. Run the script while the problem is happening, because an idle window shows an idle server. For a repeatable demo, the script creates a small database and runs 5,000 single row inserts between the snapshots. Each insert commits on its own, so each one waits for the log.
IF DB_ID(N'WaitScriptDemo') IS NULL CREATE DATABASE WaitScriptDemo;
GO
USE WaitScriptDemo;
GO
DROP TABLE IF EXISTS dbo.Ping;
CREATE TABLE dbo.Ping (PingID int IDENTITY(1,1) PRIMARY KEY, Note int NOT NULL);
GO
SET NOCOUNT ON;
SELECT wait_type, waiting_tasks_count, wait_time_ms, signal_wait_time_ms INTO #WaitBefore FROM sys.dm_os_wait_stats;
DECLARE @i int = 1;
WHILE @i <= 5000 BEGIN INSERT dbo.Ping (Note) VALUES (@i); SET @i += 1; END;
SELECT wait_type, waiting_tasks_count, wait_time_ms, signal_wait_time_ms INTO #WaitAfter FROM sys.dm_os_wait_stats;
SELECT a.wait_type,
       a.wait_time_ms - ISNULL(b.wait_time_ms, 0) AS WaitMs,
       a.signal_wait_time_ms - ISNULL(b.signal_wait_time_ms, 0) AS SignalMs,
       a.waiting_tasks_count - ISNULL(b.waiting_tasks_count, 0) AS Waits
INTO #WaitDelta
FROM #WaitAfter AS a
LEFT JOIN #WaitBefore AS b ON b.wait_type = a.wait_type
WHERE a.wait_time_ms - ISNULL(b.wait_time_ms, 0) > 0
  AND NOT EXISTS (SELECT 1 FROM #IdleWait AS i WHERE a.wait_type LIKE i.WaitPattern);
To measure a real problem, replace the insert loop with WAITFOR DELAY '00:00:10'. The script then records ten seconds of whatever the server does.
To see the totals since startup instead, add WHERE 1 = 0 to the first snapshot. The first snapshot is then empty, and the subtraction changes nothing. That view is useful on a server you have never seen. Clearing the counters with DBCC SQLPERF is the other way to start fresh. It erases the history for everyone who reads it. The snapshot method leaves it alone.
Step 3: Group the Waits by Resource
A list of wait types is hard to read. A group is easier. The next query maps each wait type to the resource it points at and totals the groups. Each group is a short pattern or a name. Anything not mapped lands in Other. Read the WaitMs column with one thing in mind. Every waiting task adds its own time, so a short window can show more wait time than the window lasted.
SELECT x.WaitGroup, SUM(d.WaitMs) AS WaitMs, SUM(d.SignalMs) AS SignalMs,
       CAST(100.0 * SUM(d.WaitMs) / SUM(SUM(d.WaitMs)) OVER () AS decimal(5,1)) AS PercentOfWait
FROM #WaitDelta AS d
CROSS APPLY (SELECT CASE
        WHEN d.wait_type LIKE N'LCK[_]M[_]%' THEN N'Locks'
        WHEN d.wait_type LIKE N'PAGEIOLATCH[_]%' THEN N'Data page reads'
        WHEN d.wait_type IN (N'WRITELOG', N'LOGBUFFER', N'HADR_SYNC_COMMIT') THEN N'Log writes'
        WHEN d.wait_type = N'SOS_SCHEDULER_YIELD' THEN N'CPU'
        WHEN d.wait_type LIKE N'CX%' OR d.wait_type = N'EXECSYNC' THEN N'Parallelism'
        WHEN d.wait_type LIKE N'RESOURCE[_]SEMAPHORE%' THEN N'Memory grants'
        WHEN d.wait_type = N'ASYNC_NETWORK_IO' THEN N'Client or network'
        WHEN d.wait_type LIKE N'PAGELATCH[_]%' THEN N'Hot pages'
        WHEN d.wait_type = N'THREADPOOL' THEN N'Worker threads'
        WHEN d.wait_type LIKE N'BACKUP%' OR d.wait_type = N'ASYNC_IO_COMPLETION' THEN N'Backups and file work'
        WHEN d.wait_type LIKE N'PREEMPTIVE[_]%' THEN N'Operating system calls'
        ELSE N'Other' END) AS x(WaitGroup)
GROUP BY x.WaitGroup
ORDER BY WaitMs DESC;| WaitGroup | WaitMs | SignalMs | PercentOfWait |
|---|---|---|---|
| Log writes | 499 | 140 | 99.6 |
| Operating system calls | 1 | 0 | 0.2 |
| Other | 1 | 0 | 0.2 |
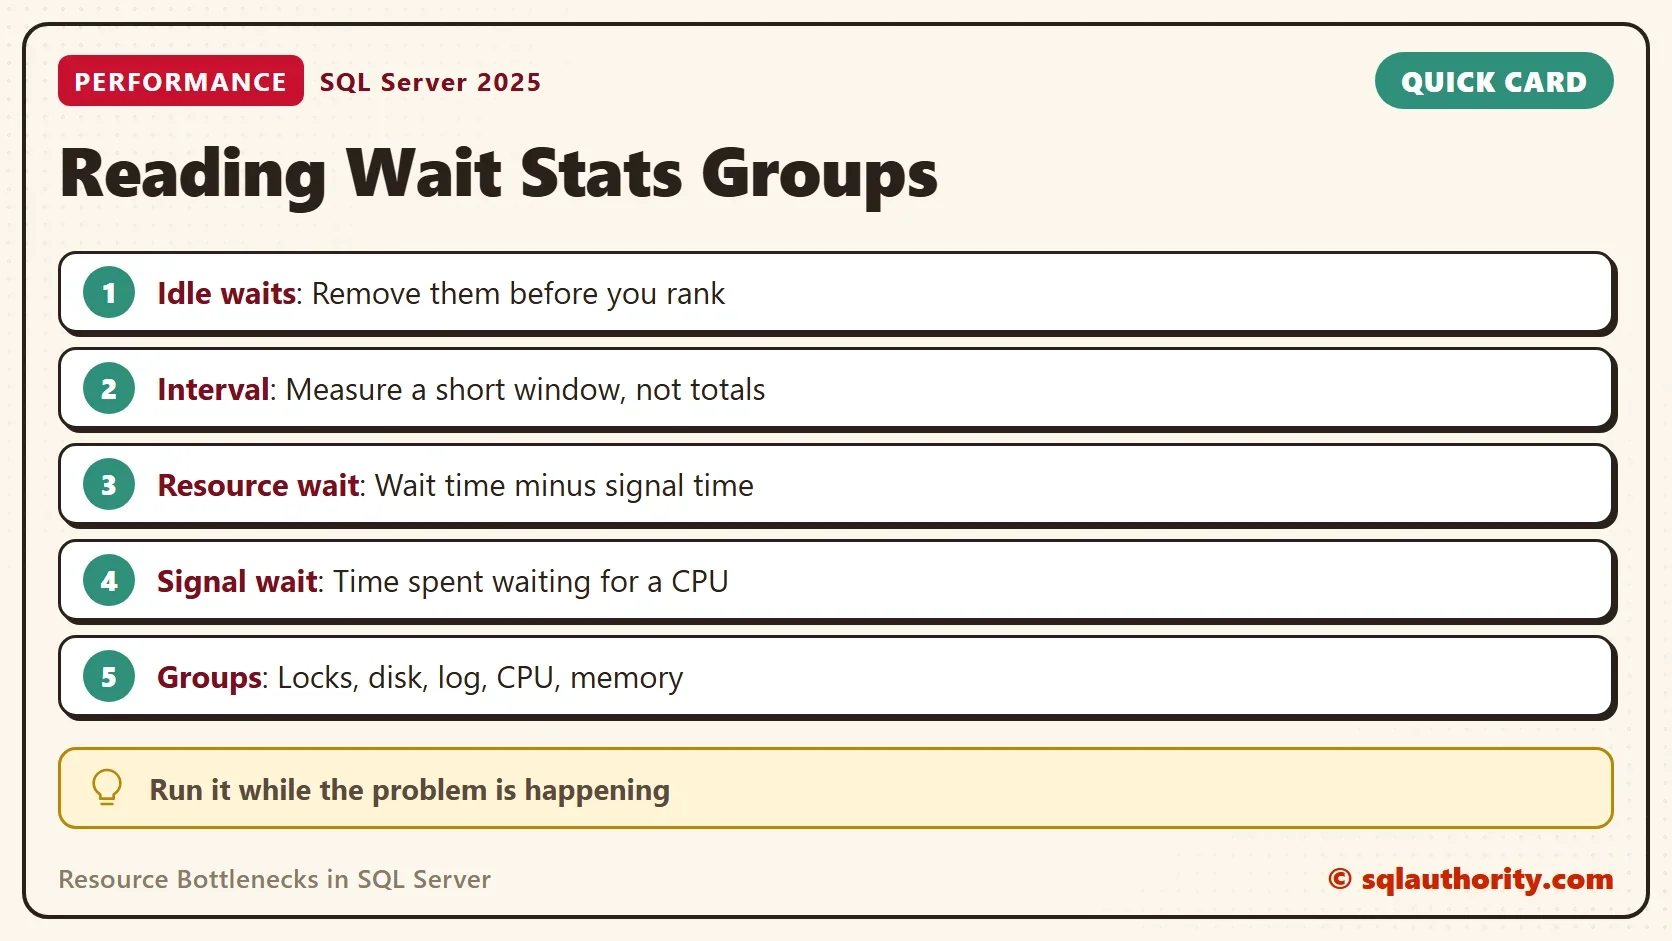
In this run, Log writes took 99.6 percent of the wait time. The demo was built to give that answer. Five thousand separate commits made five thousand trips to the log. The WaitMs and SignalMs columns hold totals for all waiting tasks.
Now look at the signal time. It was 140 ms out of 499 ms. That part is time spent waiting for a CPU after the log write had finished. The other 359 ms was the wait for the log write itself.
Step 4: Read the Top Waits
The group shows the area. The top waits show the detail. The query lists the five longest waits in the interval and splits each into signal time and resource time. The signal time is how long a task waited for a CPU after its resource was ready. The resource time is the wait for the resource itself.
SELECT TOP (5) wait_type, WaitMs, SignalMs, WaitMs - SignalMs AS ResourceMs, Waits
FROM #WaitDelta
ORDER BY WaitMs DESC;
| wait_type | WaitMs | SignalMs | ResourceMs | Waits |
|---|---|---|---|---|
| WRITELOG | 499 | 140 | 359 | 5011 |
| WAIT_ON_SYNC_STATISTICS_REFRESH | 1 | 0 | 1 | 1 |
| PREEMPTIVE_OS_QUERYREGISTRY | 1 | 0 | 1 | 3 |
WRITELOG leads with 5,011 waits, one for each commit and a few more from the system. The other rows last one millisecond and don’t matter. On a busy instance other waits join the list, so judge the order of the groups, not the exact percent. The fix for this pattern is to batch the inserts in one transaction. The commit then waits for the log once, not 5,000 times.
What Each Group Points To
- Locks: sessions block each other. Find the blocker and shorten its transaction.
- Data page reads: pages come from disk because they aren’t in memory. Look at the disk speed, the memory and the indexes behind the biggest reads.
- Log writes: commits wait for the log disk. Many tiny commits make it worse, so batch the work in larger transactions.
- CPU: queries wait for a processor. A high signal share on every group says the same.
- Parallelism: parallel queries wait for each other. CXCONSUMER is a benign wait in current versions, so judge this group by CXPACKET and by the queries behind it.
- Memory grants: queries wait for memory before they can start. Look for queries that ask for far more than they use.
- Worker threads: the server ran out of threads, which is serious. Check for a blocking chain.
- Backups and file work: backups and file operations wait for the disk. They matter when they run during business hours, so check the schedule.
- Other: wait types the script doesn’t map. Read the wait type in the top waits list and look it up before you decide that it matters.
- Operating system calls: SQL Server calls the operating system and waits for the answer. File operations are typical. These waits rarely name a bottleneck on their own.
You could argue that waits alone prove nothing. That’s right. A wait tells you where time goes, not why. Pair the top wait with the queries that cause it. Check the counters of the matching resource before you change anything. A change made on the wait total alone is a guess.
What to Remember
To find resource bottlenecks, remove the idle waits, measure an interval and group the rest. Then read the top group and its top waits, with the signal time next to the resource time. To find the queries, let the top wait name the resource. Then use the query stats view to name the statements that use it. Keep the idle list and the group names in your own script file. Extend them when a new wait type appears on your servers.
When you finish, run the cleanup script. It drops the temporary tables and the demo database.
DROP TABLE IF EXISTS #IdleWait, #WaitBefore, #WaitAfter, #WaitDelta;
GO
USE master;
GO
ALTER DATABASE WaitScriptDemo SET SINGLE_USER WITH ROLLBACK IMMEDIATE;
DROP DATABASE WaitScriptDemo;
A wait is not a verdict, it is a pointer to the one resource your server is short of.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

7 Comments. Leave new
Pinal,
I have just sent an attachment.Could you please review.
If you have sent email, I reply every email in six hours.
Hi Pinal, can you give me feedback on my results for wait time? I have attached a file
Hi Pinal,
We are using SQL Server 2016 developer edition and getting high wait stats: PARALLEL_REDO_WORKER_WAIT_WORK.
could you please help us to resolve this.
Thanks
Mahender Singh
You can disabled parallel redo by trace flag 3459
How to find the db query taking time while doing in the performance test. and how to sort it out.
Hi Pinal
I have SQL Server 2016, and it have very high PWAIT_DIRECTLOGCONSUMER_GETNEXT
Wait Type : PWAIT_DIRECTLOGCONSUMER_GETNEXT
Number of Waits : 5256047
Wait Time (sec) : 6694882.612
% Wait Time : 99.97%
Max Wait Time (ms) : 98689647
Avg Wait Time (ms) : 1273.7
Could you please help us to resolve this.
Thanks
Satti