
Here is Interview Question of the Week #034: what is the difference between DISTINCT and GROUP BY? Both can hand you a list of unique rows, so it is tempting to say they are the same thing. They are close cousins, not twins, and explaining that small gap is what makes a good answer.
The short answer I would give: Use DISTINCT when your goal is to remove duplicate result rows. Use GROUP BY when you want a calculation for each group, such as a count, sum, or maximum. That is the heart of it. Everything else is detail you can add if the interviewer keeps asking.
Here is a small table so that the three queries below can be run as written:
CREATE TABLE #Employees
(
    Employee nvarchar(40) NULL,
    [Rank] nvarchar(20) NULL
);
INSERT #Employees (Employee, [Rank]) VALUES
    (N'Alex', N'Senior'), (N'Alex', N'Senior'),
    (N'Blair', N'Junior'), (N'Blair', N'Senior'),
    (NULL, N'Junior'), (NULL, N'Junior');
The first query returns each employee-and-rank combination once. The second produces the same combinations by grouping on those two columns:
SELECT DISTINCT Employee, [Rank]
FROM #Employees
ORDER BY Employee, [Rank];

SELECT Employee, [Rank]
FROM #Employees
GROUP BY Employee, [Rank]
ORDER BY Employee, [Rank];
Now GROUP BY earns its place. COUNT(*) tells us how many original rows fell into each pair, which a simple DISTINCT list does not report:
SELECT Employee, [Rank], COUNT(*) AS EmployeeCount
FROM #Employees
GROUP BY Employee, [Rank]
ORDER BY Employee, [Rank];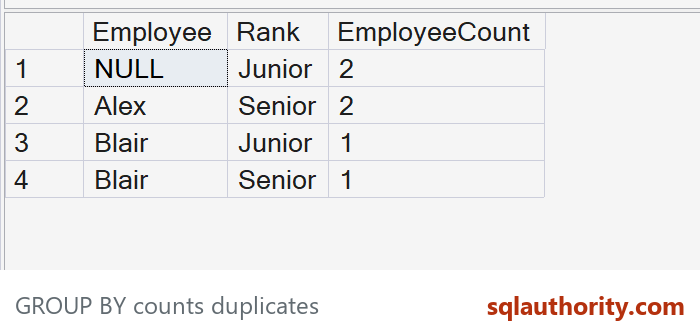
A few follow-up points are worth remembering. DISTINCT considers the complete selected row, so Alex, Senior and Blair, Senior are different. GROUP BY pairs with HAVING when you need to filter groups. Repeated NULL-containing pairs collapse to one distinct row or group. Neither keyword promises order; use ORDER BY for that.
Speed is usually not decided by the keyword alone. Simple equivalent queries may produce similar plans, while more involved expressions can produce different work. Run both on representative data and compare the actual plans when performance matters. My one-line answer remains: DISTINCT removes duplicate result rows; GROUP BY summarizes groups.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

4 Comments. Leave new
no .group by is faster! better in the long run. if need to work with subqueries, select distinct kill the CPU. group by already filter out duplicated row.
dba100 – please provide example.
can’t see why I just add a comment and when I submit that.
I am not going to type long again.
select distinct is a row by row operation, just like RBAR operation. with subqueries, it run each subqueries, which is worse already, and after that , drop that as select distinct see some ROW is duplicated.
we just under the same problem and we fix it by using group by.
other worse thing we saw is the function, RAM eating.
when compare with group by, group by do not have the additional SORT operator.
dba100 – Thanks for sharing your scenario.