
If you ever thought this is some sort of trick to bring you to the blog, well you are wrong. This infact is something worth a look and interesting thing to know. Before I start to explain you the finer details, let me tell you that this is NOT a new feature for performance improvement of the SQL Server Engine. What I am talking about is hypothetical indexes.
During profiling one of the databases, one of my DBA friends asked a question about why there is a difference in the indexes shown in SQL Server Management Studio vs. T-SQL query. Though it didn’t make sense to me, I asked for details and wanted him to get me the details. This leads to the learning which I thought was worth a share. Here is what I mean:
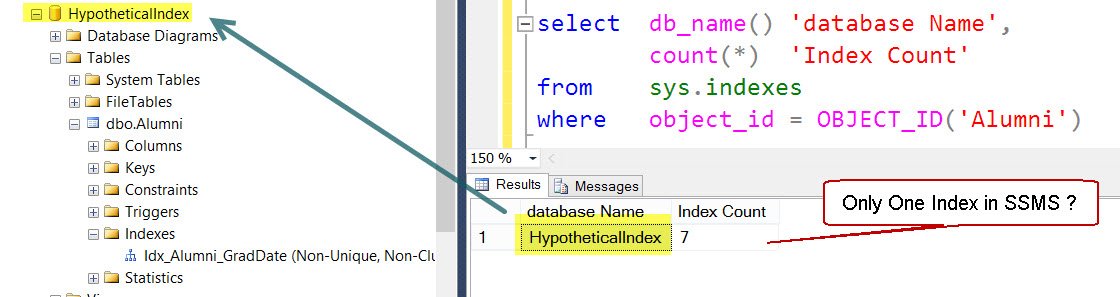
Trust me, there is absolutely no Photoshop trick in the above image. Sys.Indexes catalog view shows 7 entries for a table but object explorer shown only one index on the table which is the ONLY object inside the database.
Before we talk about the reason, you can play around with me by creating sample table using the below script.
USE MASTER
GO
IF DB_ID('HypotheticalIndex') IS NOT NULL
BEGIN
ALTER DATABASE HypotheticalIndex SET SINGLE_USER WITH ROLLBACK IMMEDIATE
DROP DATABASE HypotheticalIndex
END
CREATE DATABASE HypotheticalIndex
GO
USE HypotheticalIndex
GO
CREATE TABLE [Alumni]
(
[SSN]         [INT] IDENTITY(1, 1) NOT NULL,
[StudentName] [CHAR](200) NULL,
[GradDate]    [DATETIME] NULL
)
GO
SET NOCOUNT ON
GO
INSERT INTO Alumni
(StudentName,
GradDate)
VALUES      (RAND() * 1000,
DATEADD(dd, RAND() * 100, GETDATE()))
GO 60000 -- should take around 50 seconds
SET NOCOUNT OFF
GO
Above script would create a database and populate rows. Let’s create an index on the table.
CREATE INDEX Idx_Alumni_GradDate
ON Alumni(GradDate)
To create hypothetical index on the same column, we can run the below command:
CREATE INDEX Alumni_hyp_1
ON Alumni(GradDate)
WITH STATISTICS_ONLY=1
GO
Here the keyword is undocumented extension WITH STATISTICS_ONLY which is available with CREATE INDEX command.
Let us next look at sys.indexes output:
SELECT name,
index_id,
type_desc,
data_space_id,
is_hypothetical
FROM   sys.indexes
WHERE  OBJECT_ID = OBJECT_ID('Alumni')
AND    type_desc <> 'HEAP'
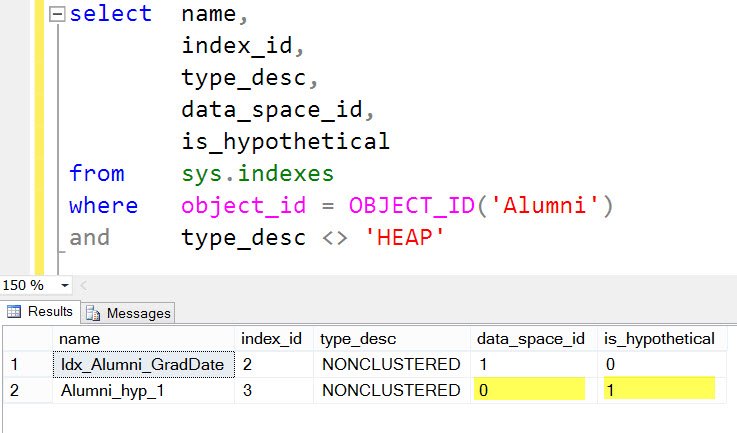
Notice the highlighted column values for hypothetical index. Data_space_id is zero because there is no physical storage for this index. It is not stored in any filegroup or file.
Let’s look at the statistics.
DBCC SHOW_STATISTICS (Alumni, Alumni_hyp_1) WITH STAT_HEADER
GO
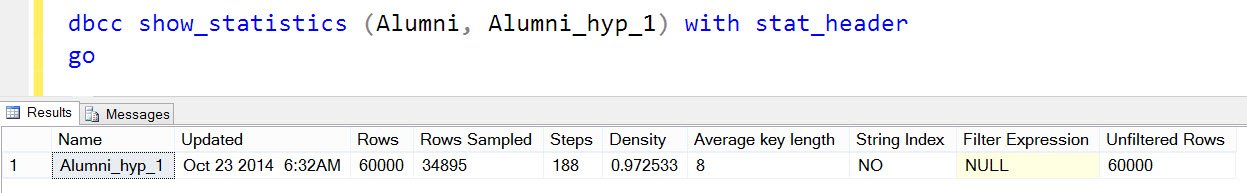
We can see that rows are sampled and statistics object is generated for hypothetical index.
This means that the hypothetical index is an index that has the metadata (in sys.indexes with is_hypothetical = 1) and a statistics associated to it (in sys.stats), but does not have physical storage. This is used only for costing evaluation of query plan in conjunction with “DBCC AUTOPILOT” and “SET AUTOPILOT ON” commands. These settings are for a future discussion and blog, let us move along.
Since SQL Server Management Studio is filtering out the hypothetical indexes in Object Explorer – this is the reason my friend saw a difference in T-SQL and SSMS.
STATISTICS_ONLY option is undocumented but I was playing around with the option and found something interesting. Based on the value passed to this parameter the statistics, sampling would be changed.
CREATE INDEX Alumni_hyp_0
ON Alumni(GradDate)
WITH STATISTICS_ONLY=0
GO
DBCC SHOW_STATISTICS (Alumni, Alumni_hyp_0) WITH STAT_HEADER
GO
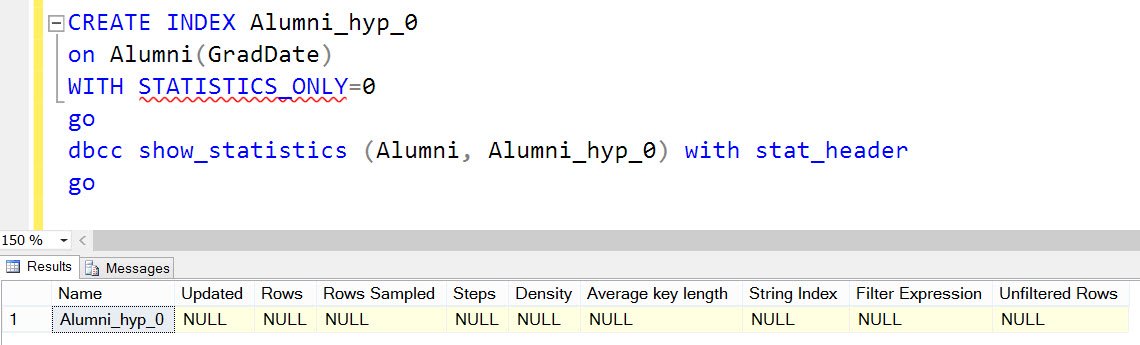
If we pass a value as zero the statistics isnot generated.
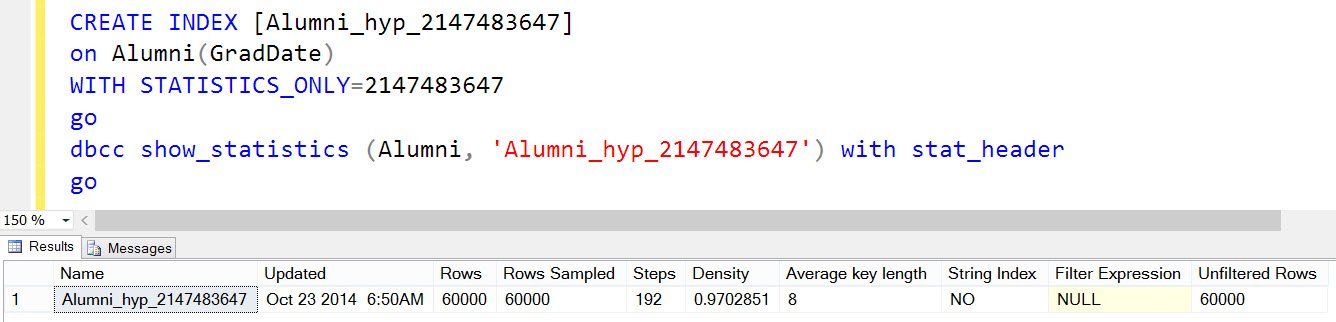
If I pass the highest value (2^31-1) = 2147483647 then sampling is done with Full Scan.
CREATE INDEX [Alumni_hyp_2147483647]
ON Alumni(GradDate)
WITH STATISTICS_ONLY=2147483647
GO
DBCC SHOW_STATISTICS (Alumni, 'Alumni_hyp_2147483647') WITH STAT_HEADER
GO
To find a hypothetical index in the database, we can run below query.
SELECT  *
FROM    sys.indexes
WHERE   is_hypothetical = 1
Generally the index name would be _dta_index because the DTA uses them behind the scene to evaluate the cost of an index by creating them hypothetically. If DTA exits gracefully than it does clean up these indexes. But if someone is losing patience while DTA is running and kills it using task manager, then those indexes would be left behind. It is safe to drop hypothetical indexes. They can be dropped using the normal DROP INDEX command. I must point out that if you apply recommendation provided by the DTA while tuning a query and don’t change the suggested name, they would have _dta_ in their name. The name doesn’t mean they are hypothetical – we need to use the is_hypothetical column to filter them.
How did I learn this? Someone asked how the Database Engine Tuning Advisor (a.k.a. DTA) works. How does it create and evaluate indexes on huge tables? So I captured profiler while running DTA and found many interesting facts and under the cover working of the tool. This blog is an idea after seeing profiler. Learning never stops if you are working with SQL Server!
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.

1 Comment. Leave new
Great post, I was getting crazy finding out why hypothetical indexes have a statistic but not an index in SSMS.