I use XML query when I need the selected markup, including its attributes and children. It returns XML rather than one SQL scalar. The example converts that small fragment to text for a readable comparison.
Select the subtree rather than its text
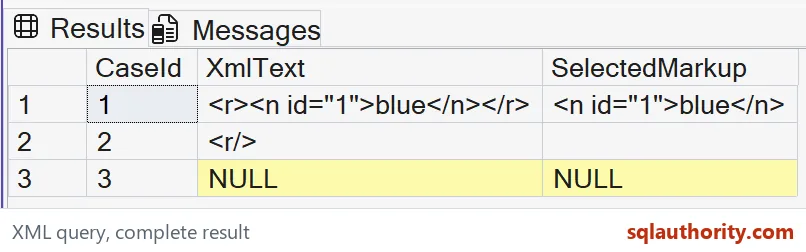
The first document contains an n element with an id attribute and text. The query path returns that element, including its markup. The expected displayed fragment is <n id=”1″>blue</n>.
Extracting only the word blue would answer a different question. I’d keep the method choice connected to the consumer’s requirement. A downstream XML operation can need the attribute and element structure. A human display can focus on the text instead.
WITH Documents AS
(
 SELECT CaseId, CAST(XmlText AS nvarchar(200)) AS XmlText,
        CAST(XmlText AS xml) AS XmlDocument
 FROM (VALUES (1,N'<r><n id="1">blue</n></r>'),(2,N'<r/>'),
              (3,CAST(NULL AS nvarchar(200)))) v(CaseId,XmlText)
)
SELECT CaseId, XmlText,
       CAST(XmlDocument.query('/r/n') AS nvarchar(200)) AS SelectedMarkup
FROM Documents
ORDER BY CaseId;
Keep the method type separate from the display type
The query method returns an XML instance. The outer cast gives SelectedMarkup an nvarchar(200) display contract for these short examples. That cast is visible in the SQL rather than implied by a screenshot.
I wouldn’t reuse this short width for arbitrary production fragments. A larger subtree needs an appropriate output capacity or its original XML type. The teaching display is deliberately bounded, while the method’s actual XML result remains a separate type decision.
Read an empty fragment
The second document has an r element but no n child. The path selects no nodes, and its displayed fragment is an empty string. That is a supplied document with an empty selection.
I’d retain this case because an empty display can look like missing input. The original XmlText column shows that a document was supplied. A consumer can then decide whether an empty selection is acceptable instead of guessing from a blank fragment alone.
Preserve a missing document
The third row supplies SQL NULL as its document. Its SelectedMarkup remains NULL, which is distinct from the empty fragment in the previous row. No default root or placeholder element is inserted.
I don’t merge those cases during extraction unless the application explicitly asks for normalization. They can require different explanations to a caller. A missing document and a document without the requested child haven’t established the same structural fact.

Review structure instead of serialized spelling
An XML result carries structure, while its text display serializes that structure. These small expected strings make the baseline readable. More complex documents can have namespace declarations and other serialization details that deserve separate review.
I’d avoid using raw text spelling as a universal XML equality rule. The requirement should state whether it concerns a particular serialized representation or the selected structure. This query chooses a simple fragment so that its complete expected text can be compared without that ambiguity.
Choose the method that matches the consumer
The value method is appropriate when the consumer needs one typed scalar. query is useful when the selected XML itself must remain available. Their output contracts differ even if both operations address the same document.
This SELECT performs no XML modification and creates no objects. I’d compare all three complete results on the target instance, then add the consumer’s namespace and shape cases. A successful small fragment doesn’t prove that every larger subtree fits a chosen text display width.
Look at the structure first, and the text display follows easily.
Selected markup is not a scalar label, it is an XML fragment with structure worth preserving.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.