
Stored Procedure Optimization is a short list of habits, and each one is easy to test. Two procedures answer the same question on a small orders table. One is written badly, one well, and logical reads tell them apart.
Build the Test Data
Every stored procedure optimization example below runs in a test database named ProcTipsDemo. The script creates 20,000 orders in a table with two indexes. One customer owns most of the orders, and that skew matters later. Run it on a test instance.
IF DB_ID(N'ProcTipsDemo') IS NULL CREATE DATABASE ProcTipsDemo;
GO
USE ProcTipsDemo;
GO
DROP TABLE IF EXISTS dbo.Orders;
CREATE TABLE dbo.Orders (
    OrderID    int IDENTITY(1,1) NOT NULL PRIMARY KEY,
    CustomerID int            NOT NULL,
    OrderDate  datetime2(0)   NOT NULL,
    Status     varchar(10)    NOT NULL,
    Total      decimal(10,2)  NOT NULL,
    ShipNote   char(100)      NOT NULL DEFAULT 'Standard shipping'
);
INSERT INTO dbo.Orders (CustomerID, OrderDate, Status, Total)
SELECT TOP (20000)
       CASE WHEN (n / 7) % 10 < 6 THEN 1 ELSE 2 + (n * 31) % 4000 END,
       DATEADD(MINUTE, (n * 37) % 1440, DATEADD(DAY, n % 1400, CAST('2023-01-01' AS datetime2(0)))),
       CASE WHEN n % 7 = 0 THEN 'Open' ELSE 'Shipped' END,
       10 + n % 90
FROM (SELECT ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) AS n
      FROM sys.all_objects AS a CROSS JOIN sys.all_objects AS b) AS nums
ORDER BY n;
CREATE INDEX IX_Orders_OrderDate ON dbo.Orders (OrderDate) INCLUDE (CustomerID, Total);
CREATE INDEX IX_Orders_CustomerID ON dbo.Orders (CustomerID);
SELECT COUNT(*) AS OrderCount, COUNT(DISTINCT CustomerID) AS Customers,
       SUM(CASE WHEN CustomerID = 1 THEN 1 ELSE 0 END) AS CustomerOneOrders
FROM dbo.Orders;| OrderCount | Customers | CustomerOneOrders |
|---|---|---|
| 20000 | 3886 | 12011 |
One Request, Written Two Ways
The first procedure collects five habits I see in real code. It uses the sp_ prefix and leaves out the schema. It returns every column and hides the date column inside a function. It never turns off row counts.
CREATE OR ALTER PROCEDURE dbo.sp_OrdersForDay @Day date
AS
SELECT * FROM Orders WHERE DATEDIFF(DAY, OrderDate, @Day) = 0;
The second one answers the same question the way I write it today.
CREATE OR ALTER PROCEDURE dbo.GetOrdersForDay @Day date
AS
BEGIN
    SET NOCOUNT ON;
    SELECT o.OrderID, o.CustomerID, o.OrderDate, o.Total
    FROM dbo.Orders AS o
    WHERE o.OrderDate >= @Day AND o.OrderDate < DATEADD(DAY, 1, @Day);
END;
SET NOCOUNT ON stops SQL Server from sending a rows affected message after every statement. In a loop of thousands of statements, those messages add traffic. The dbo schema name removes any doubt about which table is meant. It also spares SQL Server a search through the caller’s default schema. That certainty matters more than any speed gain. The column list lets the narrow date index answer the query on its own.
Now run both for one day and watch the reads. SET STATISTICS IO shows the logical reads, which count the pages SQL Server touched. SET STATISTICS TIME shows CPU and elapsed time the same way.
SET STATISTICS IO ON;
EXEC dbo.sp_OrdersForDay @Day = '2025-03-15';
EXEC dbo.GetOrdersForDay @Day = '2025-03-15';
SET STATISTICS IO OFF;
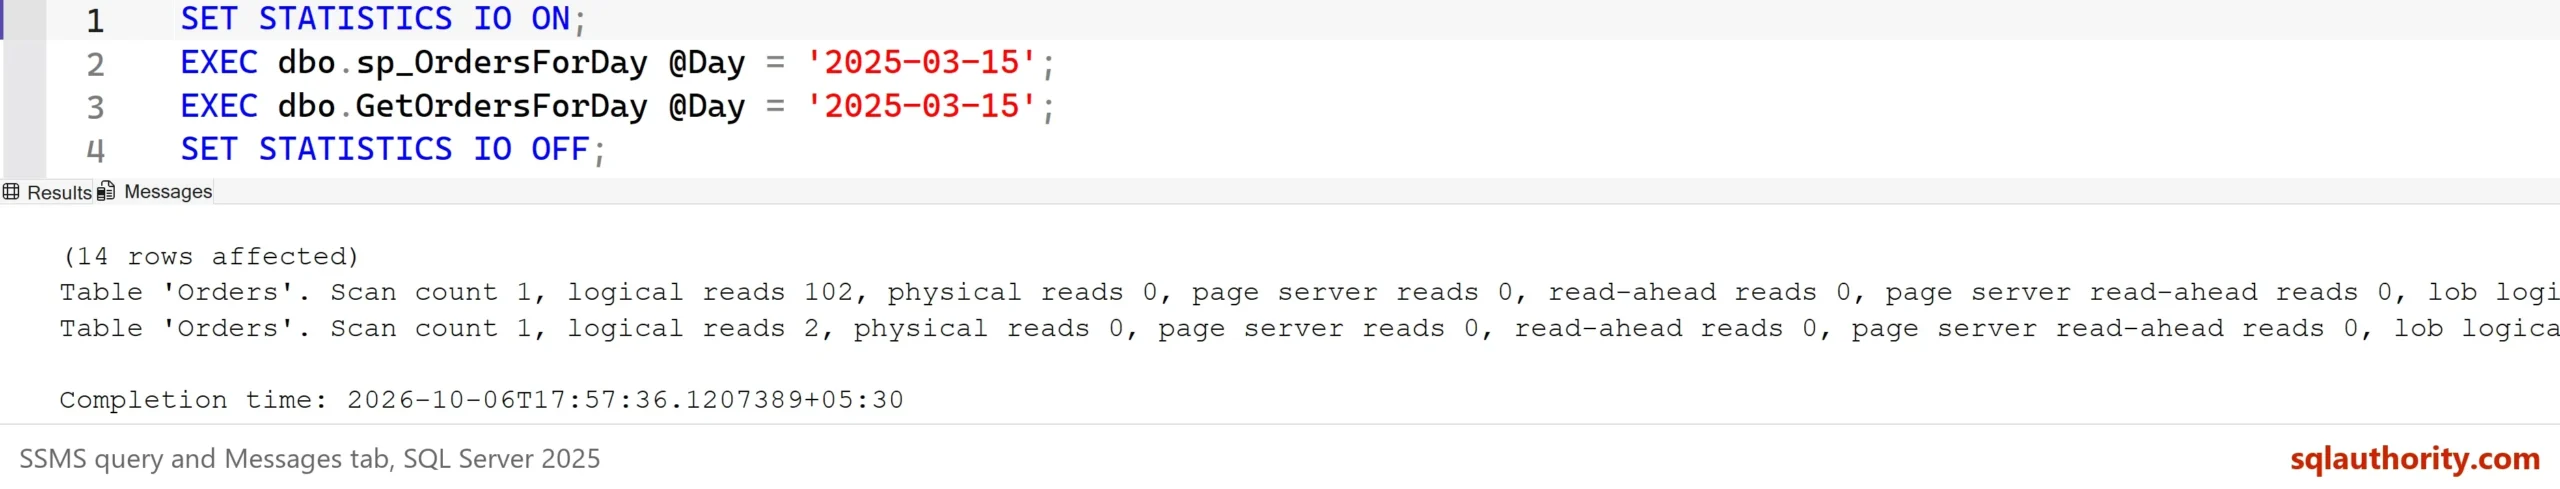
| Procedure | Rows returned | Logical reads | Rows affected message |
|---|---|---|---|
| sp_OrdersForDay | 14 | 102 | (14 rows affected) |
| GetOrdersForDay | 14 | 2 | none |
Both return the same 14 rows, and the reads fall from 102 to 2. Both changes help. SELECT * adds a lookup into the table for every row it returns. A function on the column hides it from the index. SQL Server must read the whole index and apply the function to every entry. A filter that can use an index seek is called sargable. Compare the bare column with a range, and it is.
Why the sp_ Prefix Is a Trap
SQL Server treats names that start with sp_ as system procedures. It looks for them first in its own system database. A common question is whether a dbo prefix on the call fixes that. This test creates a procedure with a real system name in the demo database. Then it calls the name three ways: plain, with dbo, and with the database name.
CREATE OR ALTER PROCEDURE dbo.sp_helpsort
AS
SELECT N'my own procedure' AS WhoAnswered;
GO
EXEC sp_helpsort;
EXEC dbo.sp_helpsort;
EXEC ProcTipsDemo.dbo.sp_helpsort;
All three calls returned the system procedure’s answer, the server’s default collation. The new procedure never ran. The documentation warns about exactly this. Pick a plain verb such as Get or Update, and skip any prefix.
Parameter Sniffing
SQL Server builds a procedure’s plan the first time it runs and reuses it afterward. The plan depends on the parameter value of that first call. This is parameter sniffing, and it explains many reports of a procedure that was fast yesterday. The next procedure counts the orders of one customer.
CREATE OR ALTER PROCEDURE dbo.GetCustomerSpend @CustomerID int
AS
BEGIN
    SET NOCOUNT ON;
    SELECT COUNT(*) AS OrderCount, SUM(Total) AS Spent
    FROM dbo.Orders
    WHERE CustomerID = @CustomerID;
END;
Customer 17 has 3 orders, and customer 1 has 12,011. The script calls the procedure with the small customer first, then the big one on the same plan. Then it forces a recompile and repeats the calls in the other order.
SET STATISTICS IO ON;
EXEC dbo.GetCustomerSpend @CustomerID = 17;
EXEC dbo.GetCustomerSpend @CustomerID = 1;
EXEC sys.sp_recompile N'dbo.GetCustomerSpend';
EXEC dbo.GetCustomerSpend @CustomerID = 1;
EXEC dbo.GetCustomerSpend @CustomerID = 17;
SET STATISTICS IO OFF;
| Call | Customer | Plan built for | Logical reads |
|---|---|---|---|
| 1 | 17 | customer 17 | 8 |
| 2 | 1 | customer 17 | 24045 |
| 3 | 1 | customer 1 | 74 |
| 4 | 17 | customer 1 | 74 |
The 8 reads for 3 orders fit a seek with one lookup per order. That plan is perfect for 3 orders and a disaster for 12,011. The 74 reads fit an index scan, so the small customer pays 74 instead of 8. Neither plan is wrong. Each one is wrong for the other customer.
OPTION (RECOMPILE) builds a fresh plan on every call. OPTIMIZE FOR tells SQL Server which value to plan for. Query Store hints, available in SQL Server 2022 and later, add a hint without touching the procedure text. SQL Server 2022 also added parameter sensitive plan optimization, which needs compatibility level 160 or higher. The demo database runs at level 170, so the feature was available. The numbers above show the plan was reused.
CREATE OR ALTER PROCEDURE dbo.GetCustomerSpend @CustomerID int
AS
BEGIN
    SET NOCOUNT ON;
    SELECT COUNT(*) AS OrderCount, SUM(Total) AS Spent
    FROM dbo.Orders
    WHERE CustomerID = @CustomerID
    OPTION (RECOMPILE);
END;
SET STATISTICS IO ON; EXEC dbo.GetCustomerSpend @CustomerID = 17; EXEC dbo.GetCustomerSpend @CustomerID = 1; SET STATISTICS IO OFF;
| Customer | Logical reads |
|---|---|
| 17 | 8 |
| 1 | 74 |
Each customer now gets the right plan. The price is a compile on every call. I save this for procedures that run a few times a minute, not thousands. Dynamic SQL has a similar rule. Build it with sp_executesql and a typed parameter, and one cached plan serves every value.
DECLARE @sql nvarchar(200) = N'SELECT COUNT(*) AS OrderCount FROM dbo.Orders WHERE CustomerID = @CustomerID;';
EXEC sys.sp_executesql @sql, N'@CustomerID int', @CustomerID = 1;
| OrderCount |
|---|
| 12011 |
Keep Transactions Short and Errors Loud
A transaction holds its locks until it ends, so keep it short. Do reads and validation before BEGIN TRANSACTION when you can. This procedure has one UPDATE, so the transaction only shows the pattern. It ships an open order and raises an error for anything else.
CREATE OR ALTER PROCEDURE dbo.ShipOrder @OrderID int
AS
BEGIN
    SET NOCOUNT ON;
    SET XACT_ABORT ON;
    BEGIN TRY
        BEGIN TRANSACTION;
        UPDATE dbo.Orders SET Status = 'Shipped' WHERE OrderID = @OrderID AND Status = 'Open';
        IF @@ROWCOUNT = 0 THROW 50001, N'Order not found or already shipped.', 1;
        COMMIT TRANSACTION;
    END TRY
    BEGIN CATCH
        IF @@TRANCOUNT > 0 ROLLBACK TRANSACTION;
        THROW;
    END CATCH;
END;
XACT_ABORT ON rolls the transaction back on most run-time errors. THROW inside CATCH raises the original error again, with its number and line, so the caller sees the real problem. The next script ships order 7 twice. The second call fails. A separate batch afterward checks that no transaction stayed open.
EXEC dbo.ShipOrder @OrderID = 7;
SELECT Status FROM dbo.Orders WHERE OrderID = 7;
GO
EXEC dbo.ShipOrder @OrderID = 7;
GO
SELECT @@TRANCOUNT AS OpenTransactions;
| Status |
|---|
| Shipped |
The second call printed this error. It is output, not code to run. The check after it shows no open transaction.
Msg 50001, Level 16, State 1, Procedure dbo.ShipOrder, Line 9
Order not found or already shipped.
| OpenTransactions |
|---|
| 0 |
Think in Sets, and Measure Before You Believe a Tip
A cursor handles one row per loop. A single UPDATE handles every row in one pass, and the optimizer plans the whole job at once. When I see a cursor, I first ask which single statement could replace it. Row by row is right only when each row needs an action that SQL can’t express.
Temp tables follow the same rule as any table. Index one only when later statements reuse or join it, and compare the reads before and after.
You could argue that most of these tips save microseconds, and a procedure that touches 14 rows hardly needs them. That’s true for NOCOUNT and the schema name. It isn’t true for the date test or for sniffing, where the cost grows with the table. A stored procedure optimization tip is only as good as the number you measure on your own data.
One more debate from the comments: SELECT 1 versus SELECT * inside EXISTS. The documentation says SQL Server ignores that select list, so use whichever reads better. SELECT * in a query that returns rows is another matter, because it drags every column along.
What to Remember
Qualify names, turn on NOCOUNT, avoid the sp_ prefix and compare bare columns with ranges. These habits cost nothing. In stored procedure optimization, test each tip with SET STATISTICS IO before you trust it. Keep the transaction around the writes only.
If a procedure is fast for some values and slow for others, suspect the sniffed plan first. Out-of-date statistics cause a similar surprise, which I cover in When Are Statistics Updated? What Triggers an Automatic Update. Run the cleanup script below when you finish.
USE master;
GO
DROP DATABASE IF EXISTS ProcTipsDemo;
A fast procedure is not a clever one, it is one that does less work for the same answer.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

181 Comments. Leave new
Nice article and very helpful your articles Pinal Dave…
Hi Pinal,
I am using a complex query in a Tabled value function for a Report Purpose. But it takes too much time to execute. so what is the best solution to do this.
What is the best way to use Transactions and Try/Catch error handling? To make it more interesting what is the best way to do same for queries with repeating logic (using WHILE for example) and committing or rollbacking set of changes depending if there was an error?
This is a very nice article and good source of learning. I am new to sql server basically from Oracle Background and I have some doubts regarding the performance of one of the SP which I have created recently in SQL Server.
— I have created a SP which is accepts 4 parameters and extracts results based on them.
— Out of 4 parameters, one is date (common to all tables used), 3 are string patterns.
— I have created 3 temp tables (#temp1, #temp2, #temp3) each getting data filtered based on 3 parameters from 3 base tables each.
— I am again creating one more temp table (#temp4) in which I am joining them (the 3 temp tables – #temp1, #temp2, #temp3) with one more heavy base table plus 1-2 small tables.
— Lastly, I am joining #temp4 with one more heavy base table which contains and gives the final result.
The SP is giving results in about a minute extracting around 175K rows. But in PROD same SP is hanging for hours. DBAs found that one of the small DB tables in SP is not picking up the updated statistics and hence the performance layoff.
My question is does using so many #temp tables degrade the performance of SP? What is an alternative to #temp tables. I have already tried table variables but hard luck. Also, we I am not sure creating DB staging tables in Database in SP is a good option as I read somewhere that DDL statements must be used minimum in any SP.
Your any kind would be appreciated. Thanks!
Hello pinal I’ve a concern…….
How we can improve the performance of a stored procedure.(i.e., If we take one sp yesterday it was working good but today it is taking more time). can you please help me with that..
and one more thing how we can improve the performance of database.(I checked cpu usage, memory,.. every thing fine but why it is more time….)could you please help me with that.
Means tables used in your sp, has more data now but your sp is woking on old cached execution plan. Just recompile your sp and it should work better.
makes sense. Thanks for helping.
How we can improve the performance of sp.
if you were writing kernel drivers of Windows 10 years ago that would be for windows vista. that os sucked by the way. congratulations for that.
Hola como están , tengo un problema con la carga de archivo en una aplicación web en c# y sql server, cuando intento importar datos de un archivo de excel con mas de 500 registros la aplicación saca error de timeout
alguien me puede ayudar con esto
mil gracias
[Hello as they are, I have a problem with the file upload in a web application in c # and SQL Server, when I try to import data from an Excel file with more than 500 records shows the application timeout error
Can someone help me with this
thank you]
Regediy — hkey_local_machine — software — Microsoft — asp.net — 1.1.4322.0
Add a new sword key name it as MaxHttpCollectionKeys
Edit the value of newly added key to 2001 in decimals. You may increase it if needed.
Be aware this key has been removed by MS to prevent the DOS attacks.
hello benjamin their is no issue.. dont mention “sp_”
the exact difference : select top 1 * from tbl order by desc = to get the entire row from the source table
select 1 from tbl order by desc = to get the single values retrieve from this select
does using dynamic sql inside a stored procedure enhances the performance compared to static sql?
how to use using IN clause in EXECUTE sp_executesql