An alert fires, and you need a first look before opening a dashboard. Five DMVs worth memorizing give you sessions, requests, waits, index use, and file activity.
Start the Five DMVs Worth Memorizing With Sessions
sys.dm_exec_sessions shows connected sessions and their context. Look at session_id, login_name, host_name, program_name, status, and last request times. This helps answer who is connected and whether a surge comes from one application or many. It does not prove which query is consuming resources right now.
I check user sessions first when the complaint sounds like connection pressure. A large number of sleeping sessions can be normal for a pool. Compare with a baseline before calling them a leak. The host and program fields are supplied by clients, so treat them as clues rather than security proof.
Which application is complaining, and does its session appear here? That question keeps the investigation tied to the user impact.
SELECT
    session_id, login_name, host_name,
    program_name, status, last_request_start_time
FROM sys.dm_exec_sessions
WHERE is_user_process = 1
ORDER BY session_id;
Look at Active Requests
sys.dm_exec_requests describes work executing now. It shows command, status, wait type, blocking session, CPU, elapsed time, and reads. Join it to sessions for application context. A snapshot can miss a query that runs quickly but repeats constantly. Capture another sample or use Query Store for history.
I look for blocking_session_id and wait_type before assuming high CPU. A request waiting on a lock needs a different investigation from a request burning CPU. A suspended request is not necessarily broken. It can be waiting for a resource and resume normally.
Do not kill a session because it tops one elapsed time column. Check the business operation and transaction state first. The longest running request can be the victim, not the blocker.
SELECT
    r.session_id, s.program_name, r.status,
    r.command, r.wait_type, r.blocking_session_id,
    r.cpu_time, r.total_elapsed_time
FROM sys.dm_exec_requests AS r
JOIN sys.dm_exec_sessions AS s
  ON s.session_id = r.session_id
WHERE r.session_id != @@SPID
ORDER BY r.total_elapsed_time DESC;
Read Waits as a Pattern
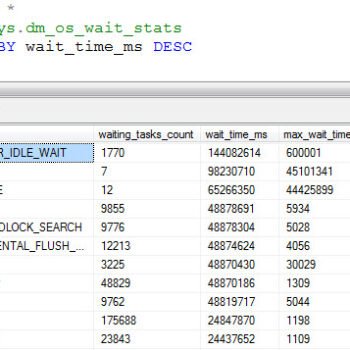
sys.dm_os_wait_stats aggregates waits since the last reset or engine start. It can show a broad workload pattern. It cannot identify the exact current query by itself. Compare intervals when possible. Exclude idle and background waits deliberately, based on the question you are asking.
A high wait total is not automatically a problem. A busy system accumulates waits. Look at the type, number of waiting tasks, and time period. Pair waits with active requests, file stats, and measured workload behavior before making a change.
I do not tune from a top waits screenshot alone. The screenshot is a direction sign, not a diagnosis. The query below shows raw values so you can decide what to filter and compare.
SELECT TOP (20)
    wait_type, waiting_tasks_count,
    wait_time_ms, signal_wait_time_ms
FROM sys.dm_os_wait_stats
ORDER BY wait_time_ms DESC;
Check Index Usage With Caution
sys.dm_db_index_usage_stats counts seeks, scans, lookups, and updates for indexes. Join it to sys.indexes and sys.objects within the current database. This helps find an index worth investigating, especially when write cost is high and read use is low.
Counters can reset on engine restart and other events. An unused index today can support a month end process. Do not drop it from one DMV snapshot. Review query plans, job schedules, and a meaningful observation period first.
The DMV also counts activity, not business value. One rare seek can serve a critical report. A million scans can be a normal workload pattern. Use the view to choose a question, then answer it with plans and application knowledge.
SELECT
    OBJECT_SCHEMA_NAME(i.object_id) AS SchemaName,
    OBJECT_NAME(i.object_id) AS TableName,
    i.name AS IndexName,
    u.user_seeks, u.user_scans,
    u.user_lookups, u.user_updates
FROM sys.indexes AS i
LEFT JOIN sys.dm_db_index_usage_stats AS u
  ON u.database_id = DB_ID()
 AND u.object_id = i.object_id
 AND u.index_id = i.index_id
WHERE i.object_id IN
    (SELECT object_id FROM sys.tables)
ORDER BY SchemaName, TableName, i.index_id;
Read File Stats Before Blaming Storage
sys.dm_io_virtual_file_stats reports I/O counters for database files. Join it to sys.master_files for file names and paths. Read counts and stall times together. A single large stall total without the number of operations can mislead. Calculate a rate from your own snapshot when comparing files.
These counters are cumulative. For a current incident, collect two snapshots over a known interval and calculate the difference. Check whether the interval overlaps a backup, index job, or application burst. File latency can be a symptom of heavy work, not just a storage fault.
I check file stats after requests and waits point toward I/O. Otherwise I can spend an hour inspecting a healthy disk while the real issue is blocking.
SELECT
    DB_NAME(v.database_id) AS DatabaseName,
    mf.name AS LogicalFileName,
    v.num_of_reads, v.io_stall_read_ms,
    v.num_of_writes, v.io_stall_write_ms
FROM sys.dm_io_virtual_file_stats(NULL, NULL) AS v
JOIN sys.master_files AS mf
  ON mf.database_id = v.database_id
 AND mf.file_id = v.file_id
ORDER BY DatabaseName, LogicalFileName;
Use the Five DMVs Worth Memorizing With Permission and Time Context
DMVs require the appropriate server or database state permissions. A denied query is not an empty server. Ask for a read only diagnostic role instead of using a powerful account by default. Record the time and instance for every sample.
Some values describe the moment, like active requests. Others accumulate since startup or reset, like wait stats. Mixing them into one sentence creates false precision. Label each result with its window. A useful incident note says what was seen and when.
Keep these five DMVs worth memorizing in a small script library. Test the scripts on your supported versions. When the next call arrives, you can spend time interpreting evidence instead of remembering a view name.
Move From Gauge to Cause With Five DMVs Worth Memorizing
A good first pass links the views. Sessions show the application. Requests show active work and blocking. Waits suggest the resource pattern. File stats show whether I/O is involved. Index usage offers a longer view of access patterns. Each answer narrows the next check.
Do not turn a DMV result directly into a configuration change. Validate with query plans, logs, and the application owner. The server supplies counters; the workload supplies meaning.
The emergency value of these views is speed. They let you ask better questions while the problem is still happening.
A sixth useful habit is to capture the engine start time beside cumulative counters. sys.dm_os_sys_info exposes sqlserver_start_time. If the engine restarted shortly before your sample, low index usage and wait totals tell you little about a monthly workload. I put the start time on every DMV report that can reset. It saves an argument about why yesterday and today look different.
Related reading on this blog: Representing sp_who2 with DMVs and Wait Stats Collection Scripts : Updated March 2021.

A DMV is not a cure, it is a gauge that tells you where to look next.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.