XQuery distinct-values removes repeated atomic values rather than selecting representative source nodes. I rebuild a small sorted XML result from repeated text. The example also keeps an empty document in view.
The source contains repeated uppercase A and B values plus lowercase a. The result should contain one of each distinct text value. Keeping uppercase and lowercase witnesses makes the comparison rule visible.
Extract values before rebuilding elements
The populated document has five v elements in the order B, A, B, a, A. A second document contains only its root element. Both are fixed XML expressions rather than stored data.
The data function obtains atomic values from the selected nodes. distinct-values removes repetitions from that sequence. A for expression then orders those values and creates one new v element for each.
The values wrapper makes the constructed result a simple XML structure. The SQL output includes its element count and uppercase and lowercase existence checks. These diagnostics remain alongside the complete XML value.
WITH Inputs AS
(
    SELECT 1 AS CaseId, CAST('<r><v>B</v><v>A</v><v>B</v><v>a</v><v>A</v></r>' AS xml) AS Doc
    UNION ALL
    SELECT 2, CAST('<r/>' AS xml)
), Deduplicated AS
(
    SELECT CaseId, Doc.query('<values>{
        for $v in distinct-values(data(/r/v))
        order by $v
        return <v>{$v}</v>
    }</values>') AS ResultXml
    FROM Inputs
)
SELECT CaseId, ResultXml,
       ResultXml.value('count(/values/v)', 'int') AS ValueCount,
       ResultXml.exist('/values/v[. = "A"]') AS HasUpperA,
       ResultXml.exist('/values/v[. = "a"]') AS HasLowerA
FROM Deduplicated
ORDER BY CaseId;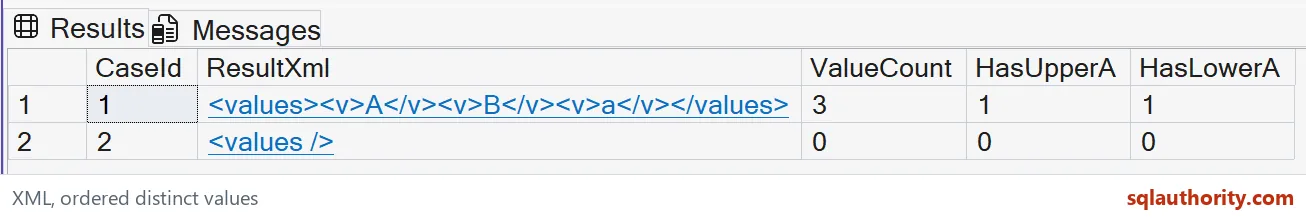

Read the populated and empty cases
The populated result should contain A, B and a in explicitly sorted order. ValueCount should be three. Both HasUpperA and HasLowerA should be one because those values remain distinct.
The empty source should produce an empty values wrapper with count zero. Both existence checks should be zero. No placeholder v element is added to represent a missing value.
The order comes from the explicit order by clause. The query does not rely on a hidden ordering promise from distinct-values itself. Keep that clause if the receiving contract requires this sequence.
The result elements are newly constructed nodes. They do not retain source-node identity or any unselected attributes. If those details matter, atomic-value deduplication alone does not define which source node to preserve.
Keep the comparison contract clear
distinct-values uses the default Unicode codepoint comparison for string values here. That preserves the distinction between A and a. A database’s familiar case-insensitive relational collation should not be assumed for this XQuery operation.
Untyped atomic XML values are treated as strings for this function. Mixed incompatible base types have restrictions. This example uses only simple text to isolate the duplicate-value behavior.
I don’t call the five source elements duplicates as complete records. They happen to repeat text values. Different attributes or nested content could make their full structures meaningful even when their text matches.
A rule that selects a representative original record needs a separate selection policy. The first node, latest node or highest-priority node can produce different retained details. None of those policies is implied by this atomic sequence.
Use the complete output as the test
The empty path is determined from a real XML input expression. It is not a literal statically empty argument substituted into the function. That keeps the demonstration within the intended runtime path case.
The query changes no source document or session setting. It only returns a new value. An application can compare that result with its required interchange shape before using it.
Compare both rows and every diagnostic column. It makes no performance or index claim. Keep repeated values, distinct case and empty input when adapting the example to a different XML source.
Try it on a few repeated values of your own and see what survives.
Deduplicating atomic values is not choosing a record, it is building a new list.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.