
Data mining looks for useful patterns and relationships in data. Supermarket purchases provide one example. Begin with the question and available evidence before choosing an algorithm.
From a supermarket question to a useful pattern
Counting the most popular product is ordinary aggregation. Finding products frequently purchased together asks a different question about relationships. Prediction asks what may happen next, using information available before that event. A pattern can support investigation, but does not explain its cause by itself.
A supervised model can learn from known outcomes, and useful input features may come from several permitted sources. Define the target, the input records and the information available at prediction time.
Analysts, developers and architects have different responsibilities
The analyst translates the business question into data and evaluates the result. The developer integrates useful results into an application or workflow. The architect coordinates data access, capacity, deployment and operational constraints. The roles can overlap, but someone must own the meaning of the outcome.
A model does not automatically reveal every meaningful relationship. Domain knowledge helps identify misleading variables, missing records and changes in the underlying business. Training should cover data preparation, evaluation and the chosen tools. An organization benefits when its analysts understand more than one narrow workflow.
A small market-basket example in ordinary T-SQL
The following example explores purchases with ordinary relational queries. It uses three orders and temporary tables only. Order 1 deliberately contains two lines for product 10. Deduplicating each order-product combination prevents that repeated line from becoming extra evidence.
SET NOCOUNT ON;
CREATE TABLE #BasketLines
(OrderId int NOT NULL, ProductId int NOT NULL, Quantity int NOT NULL);
INSERT #BasketLines VALUES
(1,10,2),(1,20,1),(1,10,1),(2,10,1),(3,20,1),(3,30,1);
SELECT DISTINCT OrderId, ProductId
INTO #Basket FROM #BasketLines WHERE Quantity > 0;

;WITH Pairs AS
(
    SELECT a.ProductId AS ProductA, b.ProductId AS ProductB,
           COUNT_BIG(*) AS PairBaskets
    FROM #Basket AS a
    JOIN #Basket AS b ON b.OrderId = a.OrderId
                     AND a.ProductId < b.ProductId
    GROUP BY a.ProductId, b.ProductId
), Products AS
(
    SELECT ProductId, COUNT_BIG(*) AS ProductBaskets
    FROM #Basket GROUP BY ProductId
), Totals AS
(
    SELECT COUNT_BIG(*) AS TotalBaskets
    FROM (SELECT DISTINCT OrderId FROM #Basket) AS orders
)
SELECT p.ProductA, p.ProductB, p.PairBaskets,
    CAST(p.PairBaskets * 1.0 / NULLIF(t.TotalBaskets,0)
         AS decimal(9,3)) AS Support,
    CAST(p.PairBaskets * 1.0 / NULLIF(a.ProductBaskets,0)
         AS decimal(9,3)) AS ConfidenceAtoB,
    CAST(p.PairBaskets * 1.0 / NULLIF(b.ProductBaskets,0)
         AS decimal(9,3)) AS ConfidenceBtoA,
    CAST(p.PairBaskets * 1.0 * t.TotalBaskets
         / NULLIF(a.ProductBaskets * 1.0 * b.ProductBaskets,0)
         AS decimal(9,3)) AS Lift
FROM Pairs AS p
JOIN Products AS a ON a.ProductId = p.ProductA
JOIN Products AS b ON b.ProductId = p.ProductB
CROSS JOIN Totals AS t
ORDER BY p.ProductA, p.ProductB;

DROP TABLE #Basket;
DROP TABLE #BasketLines;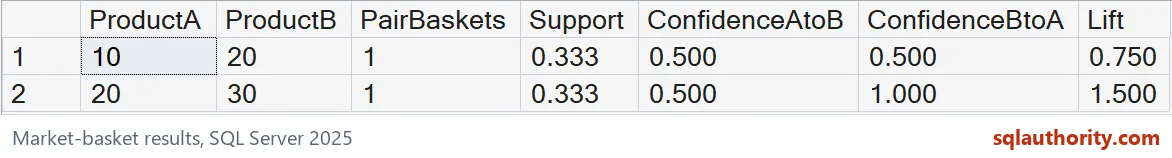
The denominator is the three orders containing at least one retained positive-quantity product. Support divides pair baskets by that order count. Confidence from A to B divides pair baskets by baskets containing A. Lift compares pair support with the product of the two individual supports.
Products 10 and 20 occur together in one basket, with support 0.333 and lift 0.750. Products 20 and 30 also share one basket, but their lift is 1.500. For that second pair, confidence from 20 to 30 is 0.500, while the reverse is 1.000. The tiny sample explains the calculations, rather than supporting a purchasing recommendation.
Set the time period, accepted order statuses and return policy before forming pairs. Require valid order and product identifiers, and define whether empty orders belong in the population. Review raw counts and a minimum evidence threshold alongside the ratios. A rare pair can look impressive while relying on very little data.

Choose evaluation that matches the question
Keep evaluation data separate from the records used to fit a predictive model. For future demand, respect time order and exclude information that becomes available only after the predicted event. Check missing values, duplicates, units and changing definitions. Compare against a simple baseline before treating a more complex model as an improvement.
Applications include forecasting demand, grouping customers, recommendations, fraud detection and risk analysis. Each application needs its own target, evidence and evaluation criteria. Capacity and suitability depend on the actual data, algorithm, platform and workload.
Use the resulting pattern to guide a decision whose assumptions you can explain.
Data mining is not a crystal ball, it is a test of patterns against evidence.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

3 Comments. Leave new
the explaination of datamining is too excellent and amazing:
Hi Pinal. Great article indeed.
I would like to do a build a linear regression model based on Printing machine toner Consumption. Do you recommend other Algorithms. Do you have an example about pattern recognition and analyzing continuous Consumption of a single Item. to forecast future demands
Thans a lot
omar Tharwat
I am a novice of dataming. Now I have a problem is to predicte: Who will buy something in the next month and which brands they will buy ?. The data is from a online shopping website, just like eBay. some data is given as blow(just a sample here) :
user_id brand_id type visit_datetime
10944750 13451 0 2013/4/15
10944750 21110 0 2013/4/17
23221235 21134 2 2013/4/12
………
………
In fact, There are a lot users and brands. The records are about 20 thousands, datetime from 2013/4/15 – 2013/8/15.
the “type” has means four actions : 0 is click, 1 is purchase, 2 is Favorites , 3 push to shopping cart.
So, we are going to predict type=1, and the time is September 2013. The output likes:
user1 -> brand1,brand2
user2 -> brand2.
I can only use sqlserver and excel do some basic analyze. I just want to know The right way to analyze these data and Which Algorithm or model to use. Thank you very much!
You can see this question on stackflow also:http://stackoverflow.com/questions/22635282/the-data-ming-on-users-online-shopping-records