SQL Server 2025 features, ranked the way the music magazines rank albums. By whether they changed anything, not by how loud the launch was. Every entry below was tried on build 17.0.4085.5 before it earned a place. Three function probes came back unrecognised with this lab’s settings, and they’re listed too.
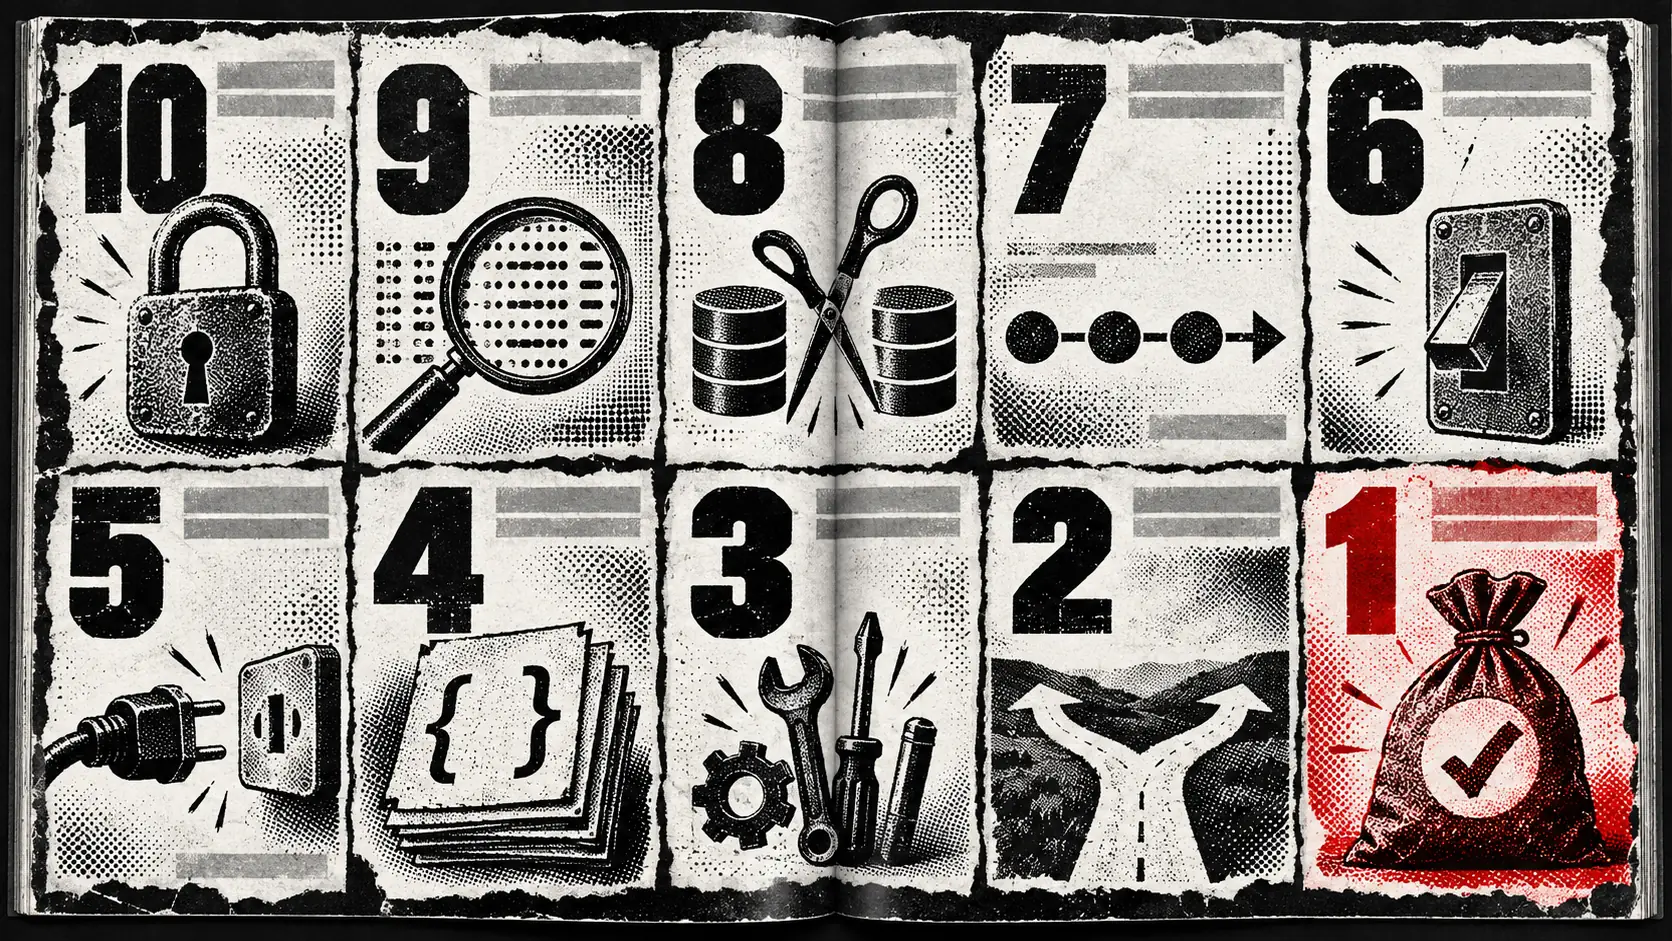
Twenty-four probes, each a TRY block. Twenty worked. Four came back no, and one of those four was a switch that is simply off. The ranking is mine. The measurements aren’t opinions.
10. Optimized locking
The column is_optimized_locking_on exists on every database. It was off on mine, because it needs accelerated database recovery switched on first.
Off is not the same as unavailable. Ranked low because I didn’t switch it on for a lab and can’t say I measured it. Ask me again after a month in production.
9. REGEXP functions
REGEXP_LIKE, REGEXP_REPLACE, REGEXP_COUNT and friends. They work and they’re correct.
Measured: a prefix match over 20,000 customer names took 2 ms with LIKE and 39 ms with REGEXP_LIKE. Use them for the patterns LIKE can’t express, not as a replacement for it.
8. The fuzzy string functions this lab couldn’t reach
EDIT_DISTANCE and JARO_WINKLER_SIMILARITY both returned “not a recognized built-in function name” with this lab’s settings. So did ANY_VALUE.
The fuzzy functions are documented as needing the preview features switch, which this lab left off. So this says nothing about whether they exist on the build. It says they aren’t reachable with the settings most instances have. If your plan depends on one, check your build and your settings before you write the code.
7. Vector data type and VECTOR_DISTANCE
You can declare VECTOR(3), insert into it, and compute cosine distance. All three worked first time.
Ranked in the middle because it’s real and it’s early. It changes what the database can hold. It hasn’t changed my week yet, because my week doesn’t have embeddings in it.
6. DOP feedback and CE feedback, on by default
Both database scoped configurations read 1 on a fresh database at level 170. I verified the switches, not the effect, so this entry is a note rather than a review.
Ranked sixth for the same reason optimized locking is tenth. Being on is not the same as being measured.
5. sp_invoke_external_rest_endpoint
It exists on the box. I didn’t call anything with it. My lab has no network access, and I won’t write about a thing I didn’t run.
It ranks fifth on shape alone. Calling a service from inside the engine is either the best or worst idea in this list. It depends entirely on who’s holding it.
4. The JSON data type
This one I expected to rank higher. A native JSON column, stored in a binary form.
Measured against the old way, 20,000 documents in an NVARCHAR(MAX) column. The same JSON_VALUE filter took 55 ms on nvarchar and 67 ms on the JSON type. Storage was 3,848 KB against 3,976 KB.
Neither faster nor smaller for that query on that data. The value is elsewhere: validation on write, and the functions that only take the new type. Adopt it for those reasons, not for speed you’ll measure on day one.
3. The small T-SQL things
|| for concatenation. UNISTR. BASE64_ENCODE and DECODE. PRODUCT as an aggregate. IS NOT DISTINCT FROM. DATE_BUCKET. GENERATE_SERIES.
Every one worked first time. None is a headline. Together they remove about a dozen small workarounds from my code. That adds up to a better week than any single big feature.
2. Parameter Sensitive Plan optimization
On by default at compatibility level 170, and it works. I proved that by finding the skew at which it starts producing a dispatcher plan. That’s a separate post.
The short version: it did nothing for a giant customer at 60 percent of the rows. In my test cases it fired only above a ratio between 90,000 and 122,500. That’s the heavy value’s rows against the estimate for the compiled one. It’s an observation, not a documented threshold. Useful, and narrower than the slide suggests.
1. Memory grant feedback with percentile and persistence
A sort spilled to tempdb on its first run. It got the right grant on its second, with no change from me. Executions two to twenty-nine reported the grant as stable and never spilled. Execution thirty ran on a freshly compiled plan.
That’s the feature that most changed a real week, because spills are the failure people don’t see. What the run shows is memory grant feedback working. It doesn’t isolate the persistence or the percentile mode, because I never compared them with those modes off.
Which SQL Server 2025 features to ignore for now
Anything that returned “not a recognized function” until you’ve checked whether a setting was the reason. Anything that needs a network path you haven’t secured. Anything you can’t switch on in a lab and measure yourself.
Upgrade for the sort that stops spilling and the dozen small workarounds you can delete. Everything else can wait for a cumulative update or two.
If you want the same twenty-four probes run against your build before you upgrade, that’s an afternoon’s work.
A feature list is not a reason to upgrade, it is a list of things to test before you do.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.