
Index key columns and included columns decide what an index can do. One query can list both for every index in a database. A name like IX_Orders_2 says nothing, but the columns say everything.
Why You Need the List
Key columns set the sort order of an index. A search can seek only when it starts with the leading key column. Included columns ride along at the leaf level. They let a query read its answer from the index without a trip back to the table.
Trouble starts when a table collects indexes over the years. Two indexes can share the same keys and differ by one included column. A third can be the first half of a fourth. Every one of them costs space and slows each insert and delete. An update pays only when it changes a column the index holds.
To judge the pile, put every index on one screen. You need its index key columns, its included columns and its use. The query below builds that list.
A Demo Table With Overlapping Indexes
The first script creates a database named IndexListDemo and one table with four nonclustered indexes. They overlap on purpose. IX_SeedOrders_Customer is the start of two others. The two CustomerDate indexes share their keys. A fourth index is filtered to open orders. Run it on a test server.
IF DB_ID(N'IndexListDemo') IS NULL CREATE DATABASE IndexListDemo;
GO
USE IndexListDemo;
GO
DROP TABLE IF EXISTS dbo.SeedOrders;
CREATE TABLE dbo.SeedOrders (
    OrderID    int IDENTITY(1,1) NOT NULL CONSTRAINT PK_SeedOrders PRIMARY KEY,
    CustomerID int           NOT NULL,
    OrderDate  date          NOT NULL,
    Status     varchar(12)   NOT NULL,
    Total      decimal(9,2)  NOT NULL,
    Note       nvarchar(200) NULL
);
CREATE INDEX IX_SeedOrders_Customer ON dbo.SeedOrders (CustomerID);
CREATE INDEX IX_SeedOrders_CustomerDate ON dbo.SeedOrders (CustomerID, OrderDate DESC) INCLUDE (Total);
CREATE INDEX IX_SeedOrders_CustomerDateCopy ON dbo.SeedOrders (CustomerID, OrderDate DESC) INCLUDE (Status);
CREATE INDEX IX_SeedOrders_OpenOrders ON dbo.SeedOrders (OrderDate) INCLUDE (CustomerID, Total) WHERE Status = 'Open';
INSERT INTO dbo.SeedOrders (CustomerID, OrderDate, Status, Total)
VALUES (1, '2026-01-05', 'Open', 20.00), (1, '2026-02-10', 'Shipped', 35.50),
       (2, '2026-02-11', 'Shipped', 12.25), (3, '2026-03-01', 'Open', 99.99);
Two queries give the usage view something to count.
SELECT COUNT(*) AS OrdersForCustomer1 FROM dbo.SeedOrders WHERE CustomerID = 1;

SELECT TOP (1) Total FROM dbo.SeedOrders WHERE CustomerID = 2 ORDER BY OrderDate DESC;
List Every Index With Its Columns
The next script stores the list in a temporary table, so the overlap check can reuse it. It starts from the index views and joins the usage view last. An index that nothing has used still appears, with zero reads.
DROP TABLE IF EXISTS #IndexList;
SELECT SCHEMA_NAME(o.schema_id) AS SchemaName,
       o.name AS TableName,
       i.name AS IndexName,
       i.type_desc AS IndexType,
       i.is_unique AS IsUnique,
       k.KeyColumns,
       ISNULL(n.IncludedColumns, N'') AS IncludedColumns,
       ISNULL(i.filter_definition, N'') AS FilterDefinition,
       ISNULL(u.user_seeks + u.user_scans + u.user_lookups, 0) AS Reads,
       ISNULL(u.user_updates, 0) AS Writes
INTO #IndexList
FROM sys.objects AS o
JOIN sys.indexes AS i ON i.object_id = o.object_id AND i.index_id > 0
CROSS APPLY (SELECT STRING_AGG(QUOTENAME(c.name) + CASE WHEN ic.is_descending_key = 1 THEN N' DESC' ELSE N'' END, N', ')
                    WITHIN GROUP (ORDER BY ic.key_ordinal)
             FROM sys.index_columns AS ic
             JOIN sys.columns AS c ON c.object_id = ic.object_id AND c.column_id = ic.column_id
             WHERE ic.object_id = i.object_id AND ic.index_id = i.index_id AND ic.is_included_column = 0) AS k (KeyColumns)
CROSS APPLY (SELECT STRING_AGG(QUOTENAME(c.name), N', ') WITHIN GROUP (ORDER BY c.name)
             FROM sys.index_columns AS ic
             JOIN sys.columns AS c ON c.object_id = ic.object_id AND c.column_id = ic.column_id
             WHERE ic.object_id = i.object_id AND ic.index_id = i.index_id AND ic.is_included_column = 1) AS n (IncludedColumns)
LEFT JOIN sys.dm_db_index_usage_stats AS u ON u.object_id = i.object_id AND u.index_id = i.index_id AND u.database_id = DB_ID()
WHERE o.is_ms_shipped = 0 AND o.type = 'U';

SELECT TableName, IndexName, IndexType, KeyColumns, IncludedColumns, FilterDefinition, Reads, Writes
FROM #IndexList
ORDER BY TableName, IndexName;| TableName | IndexName | IndexType | KeyColumns | IncludedColumns | FilterDefinition | Reads | Writes |
|---|---|---|---|---|---|---|---|
| SeedOrders | IX_SeedOrders_Customer | NONCLUSTERED | [CustomerID] | 0 | 1 | ||
| SeedOrders | IX_SeedOrders_CustomerDate | NONCLUSTERED | [CustomerID], [OrderDate] DESC | [Total] | 1 | 1 | |
| SeedOrders | IX_SeedOrders_CustomerDateCopy | NONCLUSTERED | [CustomerID], [OrderDate] DESC | [Status] | 1 | 1 | |
| SeedOrders | IX_SeedOrders_OpenOrders | NONCLUSTERED | [OrderDate] | [CustomerID], [Total] | ([Status]=’Open’) | 0 | 1 |
| SeedOrders | PK_SeedOrders | CLUSTERED | [OrderID] | 0 | 1 |
Each key column keeps its position, and DESC marks a descending key. Included columns come out in name order, because their order has no meaning. SQL Server refuses two ordered STRING_AGG calls with different orderings in one SELECT. The error is Msg 8711. So each list has its own subquery. STRING_AGG needs SQL Server 2017.
The usage join needs u.database_id = DB_ID(). The view holds rows for every database, and object IDs repeat between databases. Without the filter, the join returns extra rows with the counts from other databases. The counters also start again at an instance restart. A zero after a restart proves nothing. Reading the view needs VIEW SERVER STATE.
The Writes column counts statements, not rows. One INSERT of four rows added 1 to every index. Your Reads column depends on the queries you ran.
Find the Overlapping Indexes
A long list still needs a careful eye. This query does the first pass. It compares the key lists of indexes on the same table. It reports an index whose keys are the start of another index, and a pair with identical keys. The query never reports a unique or filtered index as the one to drop. Such an index enforces a rule or covers a slice.
SELECT a.TableName, a.IndexName,
       CASE WHEN a.KeyColumns = b.KeyColumns THEN N'Same keys as' ELSE N'Keys are the start of' END AS Relation,
       b.IndexName AS OtherIndex
FROM #IndexList AS a
JOIN #IndexList AS b ON b.SchemaName = a.SchemaName AND b.TableName = a.TableName AND b.IndexName <> a.IndexName
WHERE a.IsUnique = 0 AND a.FilterDefinition = N'' AND b.FilterDefinition = N''
  AND (a.KeyColumns = b.KeyColumns AND a.IndexName > b.IndexName
       OR LEFT(b.KeyColumns, LEN(a.KeyColumns) + 1) = a.KeyColumns + N',')
ORDER BY a.TableName, a.IndexName;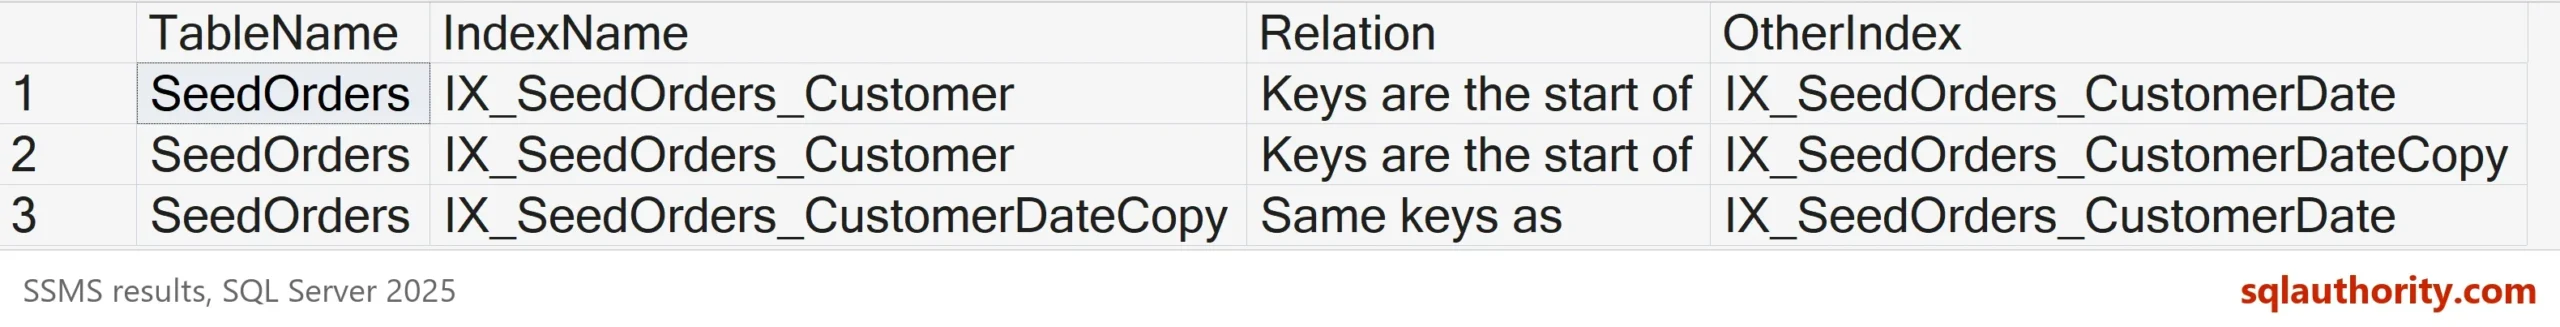
The pair with the same keys is the easy merge. Keep one index and give it both included columns, Total and Status. The single-key index is the start of both. A query that seeks on CustomerID can use the wider index instead. Check one more thing before you drop the narrower index. The wider index must also hold every included column of the narrower one, because the overlap query compares keys only.
Merge in a safe order. Create the wider index first, with the union of the included columns. Run the workload against it. Then disable the old indexes, and drop them after a quiet period. Creating before dropping means no query loses its index while you decide.
Before You Drop Anything
A report is evidence, not a verdict. Check the reads for each index across a full business cycle, including month end. A narrow index can still win a scan, because it has fewer pages to read. A wider replacement makes that scan slower. Disable the candidate first and watch the workload. A rebuild turns it back on. The Unused Index Script post shows that routine.
You could argue that Management Studio already shows these columns. It does, one index at a time, in the index properties. That works for a table with three indexes. A database with three thousand needs a query.
What to Remember
List the index key columns and the included columns for every index, together with reads and writes. Compare keys first, then included columns. Merge identical keys, and treat a shared leading key as a candidate, not a duplicate. Never drop an index that enforces a primary key or a unique constraint.
Keep the list of index key columns next to each large table in your notes. When the table changes, the list shows which index to touch. When you finish with the demo, run the cleanup script.
USE master;
GO
IF DB_ID(N'IndexListDemo') IS NOT NULL
BEGIN
    ALTER DATABASE IndexListDemo SET SINGLE_USER WITH ROLLBACK IMMEDIATE;
    DROP DATABASE IndexListDemo;
END;
A list of indexes is not a cleanup plan, it is the evidence for one.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.


5 Comments. Leave new
Hi, can your check the last line in the script?
This should be “AND i.type 0” imho …
This is very helpful Pinal. I guess the last line of the scipt has typo is “AND i.type 0”
Just convert all HTML entities in the script to ascii. Then it runs fine. This is a great toolbox addition, Pinal. Thanks to the client who shared it!
The LEFT JOIN to sys.dm_db_index_usage_stats needs AND u.database_id = DB_ID() added.
Yes, it avoids duplicates.