
To add column at specific position in SQL Server, you can’t ask ALTER TABLE to do it. The command always puts a new column last. You have three tested ways to get the order you want, and only one of them touches the table.
Why ALTER TABLE Has No AFTER Clause
People who come from MySQL write ALTER TABLE with an AFTER clause. SQL Server rejects it. The demo below builds a small plant shop table with three columns, in a database named AddColumnPositionDemo.
IF DB_ID(N'AddColumnPositionDemo') IS NULL CREATE DATABASE AddColumnPositionDemo;
GO
USE AddColumnPositionDemo;
GO
DROP TABLE IF EXISTS dbo.Plant;
CREATE TABLE dbo.Plant (
    PlantID   int IDENTITY(1,1) NOT NULL CONSTRAINT PK_Plant PRIMARY KEY,
    PlantName nvarchar(60) NOT NULL,
    Price     decimal(8,2) NOT NULL
);
INSERT INTO dbo.Plant (PlantName, Price)
VALUES (N'Basil', 3.50), (N'Rosemary', 4.25), (N'Mint', 3.00);
Now try to insert a Category column after PlantName.
ALTER TABLE dbo.Plant ADD Category nvarchar(30) NULL AFTER PlantName;
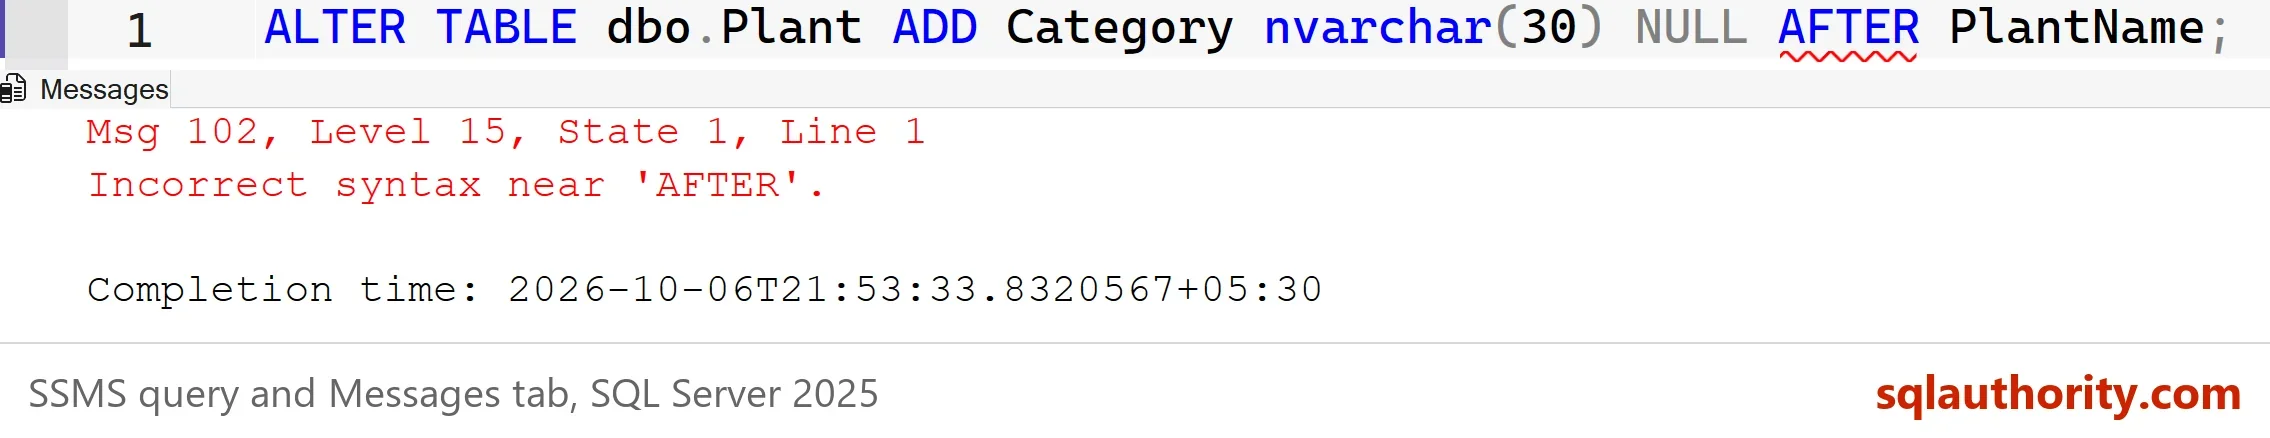
The error is Msg 102, a syntax error near AFTER. SQL Server has no such clause, and no setting adds one. The valid statement leaves it out. A GO follows it here, because a batch can’t use a column that the same batch adds.
ALTER TABLE dbo.Plant ADD Category nvarchar(30) NULL;
GO
UPDATE dbo.Plant SET Category = N'Herb';
SELECT name, column_id FROM sys.columns WHERE object_id = OBJECT_ID(N'dbo.Plant') ORDER BY column_id;
SELECT * FROM dbo.Plant;
| name | column_id |
|---|---|
| PlantID | 1 |
| PlantName | 2 |
| Price | 3 |
| Category | 4 |
| PlantID | PlantName | Price | Category |
|---|---|---|---|
| 1 | Basil | 3.50 | Herb |
| 2 | Rosemary | 4.25 | Herb |
| 3 | Mint | 3.00 | Herb |
Category is column 4, after Price. The engine treats a table as a set of columns. The stored order is only a number in the metadata. It matters to people and to SELECT *. It also matters to an INSERT with no column list and to loads that read a file by position.
Option 1: Name the Columns in the Query
The simplest way to add column at specific position is to leave the table alone. List the columns in the order you want: SELECT PlantID, PlantName, Category, Price FROM dbo.Plant. The result looks exactly as if the column had been inserted in the middle. It also protects the code from the next column someone adds. A star carries no such protection.
Option 2: Give Reports and Loads a View
A view helps when many programs read the table. It also helps when a flat file arrives in a fixed order. The first view below fixes the order for reports. The second one lists only the columns a file load fills, in the file’s order. It leaves out the identity column. Inserts through a simple view like this go straight to the table.
CREATE OR ALTER VIEW dbo.PlantList AS
SELECT PlantID, PlantName, Category, Price FROM dbo.Plant;
GO
CREATE OR ALTER VIEW dbo.PlantLoad AS
SELECT PlantName, Category, Price FROM dbo.Plant;
GO
INSERT dbo.PlantLoad VALUES (N'Thyme', N'Herb', 3.75);
SELECT * FROM dbo.PlantList ORDER BY PlantID;
| PlantID | PlantName | Category | Price |
|---|---|---|---|
| 1 | Basil | Herb | 3.50 |
| 2 | Rosemary | Herb | 4.25 |
| 3 | Mint | Herb | 3.00 |
| 4 | Thyme | Herb | 3.75 |
The new row got PlantID 4 from the identity column, and the view shows Category before Price. Nothing was copied. CREATE OR ALTER needs SQL Server 2016 SP1 or later.
Option 3: Rebuild the Table in the New Order
Sometimes the order has to live in the table itself. The rebuild creates a second table with the columns in the right order. It copies every row, drops the original and renames the copy. Everything runs in one transaction. Identity values keep their numbers because of SET IDENTITY_INSERT.
The first line of the script matters. SET XACT_ABORT ON makes any error roll the whole transaction back. Without it, SQL Server skips the failed statement and carries on. In a test, the copy failed on a column made too narrow. SQL Server skipped it, and the DROP TABLE and the COMMIT still ran. The table ended up with no rows. With XACT_ABORT on, the same failure rolled everything back, and the original table kept its two rows.
SET XACT_ABORT ON;
BEGIN TRANSACTION;
CREATE TABLE dbo.Plant_new (
    PlantID   int IDENTITY(1,1) NOT NULL CONSTRAINT PK_Plant_new PRIMARY KEY,
    PlantName nvarchar(60) NOT NULL,
    Category  nvarchar(30) NULL,
    Price     decimal(8,2) NOT NULL
);
SET IDENTITY_INSERT dbo.Plant_new ON;
INSERT INTO dbo.Plant_new (PlantID, PlantName, Category, Price)
SELECT PlantID, PlantName, Category, Price FROM dbo.Plant;
SET IDENTITY_INSERT dbo.Plant_new OFF;
DROP TABLE dbo.Plant;
EXEC sp_rename N'dbo.Plant_new', N'Plant';
EXEC sp_rename N'dbo.PK_Plant_new', N'PK_Plant', N'OBJECT';
COMMIT TRANSACTION;
SET XACT_ABORT OFF;
SELECT name, column_id FROM sys.columns WHERE object_id = OBJECT_ID(N'dbo.Plant') ORDER BY column_id; SELECT PlantID, PlantName, Category, Price FROM dbo.PlantList ORDER BY PlantID;
| name | column_id |
|---|---|
| PlantID | 1 |
| PlantName | 2 |
| Category | 3 |
| Price | 4 |
Category now sits in position 3. All four rows kept their IDs. The view still works, because it refers to the table by name. Each sp_rename call prints a caution about broken scripts. Read it, and check your own code for the old names.
The rebuild is not free. It copies every row and holds locks while it does. The script above copies only the columns and the primary key. Indexes, foreign keys, triggers, defaults and permissions must be scripted and recreated. A table that other tables point to with a foreign key can’t be dropped until those keys are removed. On a large table, that means a maintenance window.
The same rebuild puts a column first. List the new column first in the CREATE TABLE and in the column lists. For a file load by position, a view is one answer. A BULK INSERT with a format file, which maps each field of the file to a column, is another.
The SSMS Table Designer does the same work when you drag a column to the middle and save. It builds a new table, copies the data and drops the old one. The Designers page in the Options dialog has a setting named Prevent saving changes that require table re-creation. In SSMS 22 it sits under Tools, then Options, then Designers. Leave it on, so a drag doesn’t start a rebuild by accident. Deployments built with SqlPackage rebuild a table the same way when the column order differs.
Does Position Change Performance?
Not in a way you can use. Inside a row, SQL Server stores fixed length columns before variable length ones, whatever order you declared. Reordering columns is not a tuning step. The only reason to change the position is a human or program that reads by position.
You could argue that a view is a workaround, not an answer. It is. It also costs nothing, it can be changed in seconds, and it never risks the data. I keep the table in the order it grew and give people the order they need through a view.
What to Remember
Use a column list in every query and every INSERT. When a flat file or a reporting tool needs a fixed order, put a view in front of the table. To add column at specific position inside the table itself, rebuild it, and plan for the indexes and constraints.
Run the cleanup script when you finish. It drops the demo database.
USE master;
GO
ALTER DATABASE AddColumnPositionDemo SET SINGLE_USER WITH ROLLBACK IMMEDIATE;
DROP DATABASE AddColumnPositionDemo;
A column’s position is not part of the data, it is a promise you make to the people reading it.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

93 Comments. Leave new
I’m surprised we have all these professionals talking about views as if they are just a workaround for ordering columns or something to be avoided because of the maintenance overhead. Views should be an integral part of any database design. Almost all user access to the data should be controlled and Views can be an essential part of that control. You don’t give users uncontrolled access to the database, nor do you give them full access to individual tables. You give them a subset of data only accessible via views. If you have this as part your database security design, the order of the columns in the underlying data tables is irrelevant. If one group needs an additional column, you add it to the table and to their particular view without compromising the access enjoyed by the other users. None of the BI needs to be changed except for the group that requires the new column.
So please don’t look at views as a workaround or a column ordering add-on or something to be used occasionally because the data is a mess, see them as a serious tool for secure access to the data and make them part of the database design.
One last word with regard to bulk insert. My rule of thumb is to always bulk insert into a view. You don’t have to use temporary tables and it is easy maintenance if the source data format changes.
If column order is so irrelevant, then it is equally irrelevant for the logical ordering (that is displayed to the user) to be physically coupled to the physical ordering of the storage heap. The data dictionary just so happens to tell us the physical order, but there is no hard requirement for that to be so, and nowadays it is mostly a relic of when storage order actually mattered. While I agree that good SQL practices will make you immune to column order, arguing that its simple enough to fix in a view, or in a query, is arguing that SQL Server itself just needs to make the ordering configurable. A simple field added to the data dictionary to allow logical order to be specified differently than physical order would allow tools like SSMS, ER tools, and schema compare tools to ignore the physical ordering. You can’t dismiss ordering requirements as “unreasonable” without making the case that physical ordering never matters in the first place, so why establish any guarantees around it? The answer is, because sometimes it _does_ matter. Either way, a better architecture of the RDBMS engine / data dictionary would decouple the physical from logical and let it be dynamically configured _without_ the supplementary crutch of a view.
Well said.
Use Design! You can drag your column anywhere
What’s that?
I believe Thka is talking about SSMS, rightclick on table, choose Design. Then you can drag and drop a column to anywhere you want. Of course, in the background, it is performing a CREATE, INSERT, DROP, RENAME which is fine for a table with few or no rows. With a table with millions of rows as we have been talking about, SSMS will timeout.
Thanks for the clarification KISS. You are correct. Once you re-deign the table, generate a script and that can help you in avoiding timeout.
I have tables that are used to create flat files. I have the columns designed so that they are in the correct order and I can just concatenate them together. Now I need to add columns to the middle of those files. I get that I can do Select Col1 + Col4 + Col2 if I add them to the end of the table, but it just doesn’t look right if I’m doing something like Select top 1000 from SSMS or I’m looking at the table structure in object explorer.
Honestly, that will recreate the table as I mentioned in the blog post and not a great idea.
What about Sql Server Data Tools, we always work with the create definition of the table, does this tool update the database in the same way the ssms?
I have a need to add the column at specific location on the table because this table get new data from a export flat file. Currently the table has about 6 millions records and It gets about 100K new rows very 2 weeks. What is my best option? I would hate to go through to recreate table route that you mentioned but not recommended in your post.
Hi, what is the solution to add new column in specific position in sql server,
we have table with 5 default columns , later using web application we add new columns(run time), so it will adding after 5,6,7 and so on.
But now we change table structure according to customer needs, so we have to decide add 2 more column as default columns when first time creation of table. For newly create table no problem, but for exiting tables in customer place, we need to use one tool to add 2 columns in the position of 6 and 7, I know column position in not matter when retentive time we arrange it, but in our web application we skip 5 default columns and take others, so if table got 5 default and 4 run time added column, in this if add 2 more columns, it will adding in at last, so if skip 7 columns, then it will wrong.
For this we need to add columns at specific 6 and 7 location.
Note: by default we create 5 columns when create table.
Aravind
its a bad idea to think that if somebody needs to add a column at a given position then they dont know that they can use a specific column order when creating a sql query. In real word sometimes you actually need a column to be on that specific position because of some old programs that they use select * and you dont have access to the program code, is nothing you can do. So, as a general principle, offer a solution to the problem instead of saying this is a false problem, you need to do something else.
Hi Ionut,
To be super honest, if you have an application which is dependent on column order, I believe you will have to recreate the table in the order you want columns, you can’t add a column in middle in SQL Server unless you create and drop table.
I hope this helps.
I haven’t had time to read all of the comments here but my feeling is that this article doesn’t actually address the problem at all. Sure, I can retrieve the columns in whatever order I want without caring what order they’re in the table, but as a developer consistency is my friend, especially when tables can have dozens of rows. I’ve worked with databases where most tables have common columns (e.g. ‘Deleted’) but those columns are in different positions in every table and it’s very frustrating. I much prefer to locate certain common columns in the same position in every table, e.g. Primary Key column first, ‘Deleted’ penultimate and ‘LastModifiedBy’ last. The specific order isn’t important, but the fact that I always know where to find these columns in a table makes my life easier. As a result, if I’m adding a new column to a table I need to know how to add it somewhere other than at the end. I just achieve this by dragging it in SSMS (or using SQL Schema Compare in Visual Studio).
IS IT POSSIBLE ? AFTER CREATED TABLE , ADD THE ONE MORE ROW IN TABLE.
Just use INSERT statement to add new row
I’m always amazed that authorities insist there is one best practice. The best practice depends on the application as in the reasons for which something is applied. I don’t think that I read that a logical order of some kind might be there for the mere reason of easily finding it.
Views can make it easier to implement a security model. And if they are kept very simple as to only reference a single table can be effective. Even so, columns that have simple calculations can create performance issues. If Views are used to reference multiple tables, a user (another programmer) can further degrade performance by placing JOINs on two differing views that reference the same underlying table object, and even possibly cause unnecessary nesting. Naturally that further complicates diagnostics if there is a data issue. I see these issues often. I swore after the problems I’ve incurred that I would never use views again. My last data store only had two views where there were as many as a few hundred tables. Security was managed in other ways and perhaps not as complex as others that I’ve seen.
Bottom line is that every environment is different and every plan doesn’t have to be the same as to say that there is only one right way to do something. Master the fundamentals first. Apply and practice them to experience how they do or don’t work. Break the rule to make a best practice for the overall situation.
My apologies for another long narrative. But perhaps I would just like to see the answers simplified to a specific question. The best answer was that SQL Server doesn’t support it. Maybe there are physical/logical reasons, but maybe it doesn’t matter and Microsoft should just provide it.
Just my beef for the day..lol!
Here is the solution. Use ALTER table statement adding column(s) to the end. THEN use SSMS design mode for table to move column(s) to desired position(s) in the table. After you click “Save” it will not recreate table but change order of columns internally. So no timeout even on huge tables. You are welcome.
That actually drops and recreates the table behind the scene and very expensive operation.
That’s not good unfortunately, why is that Microsoft did not give this feature through scripts?
I couldnt belive that, it is really sad that you can do that in MySQL but in a Microsoft tool you cant, and worse you have to explain why you should get used to not having that feature and be happy to pay for it in production environments while in MySQL you dont have to.