I use XQuery node order to compare positions in a source document. The << and >> operators ask which node comes before or after another. They don’t sort the elements’ text or compare their business values.
Make source order visible
The fixed document places zebra first, apple second and middle third. This deliberately differs from a natural alphabetical arrangement. The first two text columns remain visible beside the positional comparisons.
Each operand selects one Item node from the same Doc value. Parenthesized paths with positional predicates make that selection explicit. I don’t extract strings and then ask the node operator to compare them. The source context is what makes the requested relationship meaningful.
WITH Source AS
(
 SELECT CAST(N'<Root><Item>zebra</Item><Item>apple</Item><Item>middle</Item></Root>' AS xml) AS Doc
)
SELECT Doc.value('(/Root/Item[1]/text())[1]','nvarchar(20)') AS FirstText,
       Doc.value('(/Root/Item[2]/text())[1]','nvarchar(20)') AS SecondText,
       Doc.value('if ((/Root/Item)[1] << (/Root/Item)[2]) then 1 else 0','int') AS FirstPrecedesSecond,
       Doc.value('if ((/Root/Item)[1] >> (/Root/Item)[2]) then 1 else 0','int') AS FirstFollowsSecond,
       Doc.value('if ((/Root/Item)[2] >> (/Root/Item)[1]) then 1 else 0','int') AS SecondFollowsFirst,
       Doc.value('if ((/Root/Item)[1] << (/Root/Item)[1]) then 1 else 0','int') AS FirstPrecedesSelf,
       Doc.value('if ((/Root/Item)[1] >> (/Root/Item)[1]) then 1 else 0','int') AS FirstFollowsSelf
FROM Source;
Read the precedes relationship
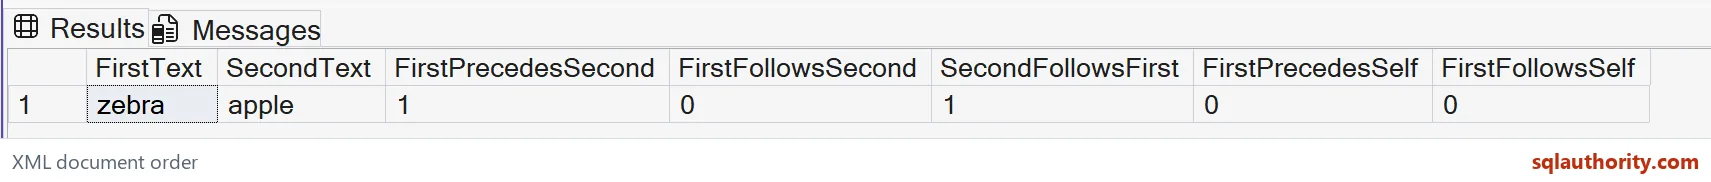
FirstPrecedesSecond expects one. The first Item occurs before the second Item in the document, regardless of their text. The << operator expresses that positional relationship.
I’d name the output Precedes rather than Smaller. Smaller can suggest a numeric or lexical comparison that this expression doesn’t perform. A report comparing process steps may care about their source sequence. That requirement should be stated explicitly instead of inferred from the visible values or a convenient alphabetical display.
Read the opposite direction
FirstFollowsSecond expects zero, while SecondFollowsFirst expects one. The >> operator reports whether its left node follows its right node. These two columns make the direction of the comparison visible.
I’d keep the operand order clear when adapting the expression. Swapping operands changes the question even though both nodes remain unchanged. A true result can otherwise be described backward in a caption. Complete aliases help a reviewer connect each decision to the actual paths used by the query.

Compare one node with itself
The final two columns compare the first Item with itself. Neither strict preceding nor strict following is true, so both expect zero. The node doesn’t occupy an earlier or later position than itself.
This is a useful boundary case beside the distinct-sibling comparisons. I’d retain it when writing an expected tuple for positional logic. A comparison intended to include identity needs another explicitly chosen rule. The strict order operators alone don’t express before-or-same or after-or-same.
Keep ordering concepts separate
Document order is a property of the source nodes. Sorting a derived report by text is another operation. That presentation choice shouldn’t silently change the relationship being described by these node comparisons.
I’d distinguish source position from any business sequence number stored in an attribute. The numbers might disagree with document order. The application must decide which convention governs its workflow. This example checks source order only, and makes no assumption about an external process definition.
Validate the selected nodes
The query reads inline XML and performs no writes. Its complete seven-column output shows the texts, both directions and the same-node controls. There is no separate dataset or hidden sorting step.
I’d inspect path cardinality before adapting the pattern to repeated nested groups. The fixed positions here always select one node. Optional elements or broader paths need their own handling. A positional comparison doesn’t establish that the selected nodes are the business records the consumer intended to compare.
Node order is source position, so preserve the node context and keep it separate from sorting the displayed values.
Node order is not sort order, it is where a node sits in the source document.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.