
This Missing Index Script lists the indexes SQL Server wishes it had, ranked by how much each one would save. The list is a set of suggestions, not orders. A wrong index costs you on every insert and delete, and on every update of its columns. Read each suggestion before you create it.
Where the Suggestions Come From
While SQL Server compiles a query, the optimizer notes any index that would have made the plan cheaper. It keeps those notes in three dynamic management views, which are system views that show live server state. One view holds the columns, one holds the counters, and one links the two.
The notes live in memory only, so a restart wipes them. A server that restarted yesterday hasn’t seen your month end. Creating an index on a table clears the notes for that table too, as the demo below shows.
One more limit surprises people. A query with a single possible plan is marked trivial, and it records no suggestion. A customer lookup against a table that has only its clustered index leaves the views empty.
A Table That Needs Help
The script below creates a database named MissingIndexDemo, used only for this example. It builds a garden center orders table with 200,000 rows and one index on Status. That index gives the optimizer a real choice to make. Run everything on a test instance.
IF DB_ID(N'MissingIndexDemo') IS NULL CREATE DATABASE MissingIndexDemo;
GO
USE MissingIndexDemo;
GO
DROP TABLE IF EXISTS dbo.Orders;
CREATE TABLE dbo.Orders (
    OrderID    int IDENTITY(1,1) NOT NULL PRIMARY KEY,
    CustomerID int           NOT NULL,
    OrderDate  date          NOT NULL,
    Status     tinyint       NOT NULL,
    Total      decimal(9,2)  NOT NULL,
    Notes      char(100)     NOT NULL DEFAULT 'none'
);
INSERT INTO dbo.Orders (CustomerID, OrderDate, Status, Total)
SELECT TOP (200000)
       1 + (ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) % 20000),
       DATEADD(DAY, ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) % 730, '2025-01-01'),
       ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) % 4,
       10 + (ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) % 90)
FROM sys.all_columns AS a CROSS JOIN sys.all_columns AS b;
CREATE INDEX IX_Orders_Status ON dbo.Orders (Status);
Now run three questions a garden center asks. One finds a customer’s orders since January. One lists everything for a customer. One totals September by customer. STATISTICS IO prints the pages each query reads, and we’ll compare those numbers later.
SET STATISTICS IO ON;
SELECT OrderID, OrderDate, Total
FROM dbo.Orders
WHERE CustomerID = 1234 AND OrderDate >= '2026-01-01';
SELECT OrderID, Total
FROM dbo.Orders
WHERE CustomerID = 1234;
SELECT CustomerID, SUM(Total) AS Spent
FROM dbo.Orders
WHERE OrderDate >= '2026-09-01' AND OrderDate < '2026-10-01'
GROUP BY CustomerID;
SET STATISTICS IO OFF;
Each query read the whole table, 3,138 pages. A shop runs the customer lookup all day, so this loop repeats it for 49 more customers.
DECLARE @c int = 1, @t decimal(9,2);
WHILE @c <= 49
BEGIN
    SELECT @t = Total FROM dbo.Orders WHERE CustomerID = @c;
    SET @c += 1;
END;
The Missing Index Script
The script joins the three views and builds a CREATE INDEX statement for each row. The score multiplies the average query cost, the average impact percentage and the times the index was wanted. Microsoft documents no unit for these numbers. So the score ranks suggestions, and it can’t promise seconds saved.
TimesWanted adds the seeks and scans that the index could have served. ImpactPct is the average percentage benefit SQL Server estimates for those queries. IndexesNow counts the indexes the table has today.
The COLLATE clauses prevent error 451, a collation conflict. Older scripts raise it when the database collation differs from the views. In a database created with the Modern_Spanish_CI_AS collation, the same concatenation fails without the clause and runs with it.
SELECT TOP (20)
       CONCAT(SCHEMA_NAME(t.schema_id), N'.', t.name) AS TableName,
       s.user_seeks + s.user_scans AS TimesWanted,
       CAST(s.avg_user_impact AS decimal(5, 1)) AS ImpactPct,
       CAST(s.avg_total_user_cost * s.avg_user_impact / 100.0 * (s.user_seeks + s.user_scans) AS decimal(18, 2)) AS Score,
       k.KeyList AS KeyColumns,
       k.IncludeList AS IncludedColumns,
       x.IndexCount AS IndexesNow,
       CONCAT(N'CREATE NONCLUSTERED INDEX ',
              QUOTENAME(CONCAT(N'IX_', t.name, N'_', nm.FirstKey, N'_', nm.KeyCount, N'cols')),
              N' ON ', QUOTENAME(SCHEMA_NAME(t.schema_id)), N'.', QUOTENAME(t.name),
              N' (', k.KeyList, N')',
              CASE WHEN k.IncludeList IS NOT NULL THEN CONCAT(N' INCLUDE (', k.IncludeList, N')') END,
              N';') AS CreateStatement
FROM sys.dm_db_missing_index_details AS d
JOIN sys.dm_db_missing_index_groups AS g ON g.index_handle = d.index_handle
JOIN sys.dm_db_missing_index_group_stats AS s ON s.group_handle = g.index_group_handle
JOIN sys.tables AS t ON t.object_id = d.object_id
CROSS APPLY (SELECT CONCAT_WS(N', ', d.equality_columns COLLATE DATABASE_DEFAULT, d.inequality_columns COLLATE DATABASE_DEFAULT),
                    d.included_columns COLLATE DATABASE_DEFAULT) AS k(KeyList, IncludeList)
CROSS APPLY (SELECT SUBSTRING(k.KeyList, 2, CHARINDEX(N']', k.KeyList) - 2),
                    (SELECT COUNT(*) FROM STRING_SPLIT(k.KeyList, N','))) AS nm(FirstKey, KeyCount)
CROSS APPLY (SELECT COUNT(*) FROM sys.indexes AS i WHERE i.object_id = d.object_id AND i.type > 0) AS x(IndexCount)
WHERE d.database_id = DB_ID()
ORDER BY Score DESC;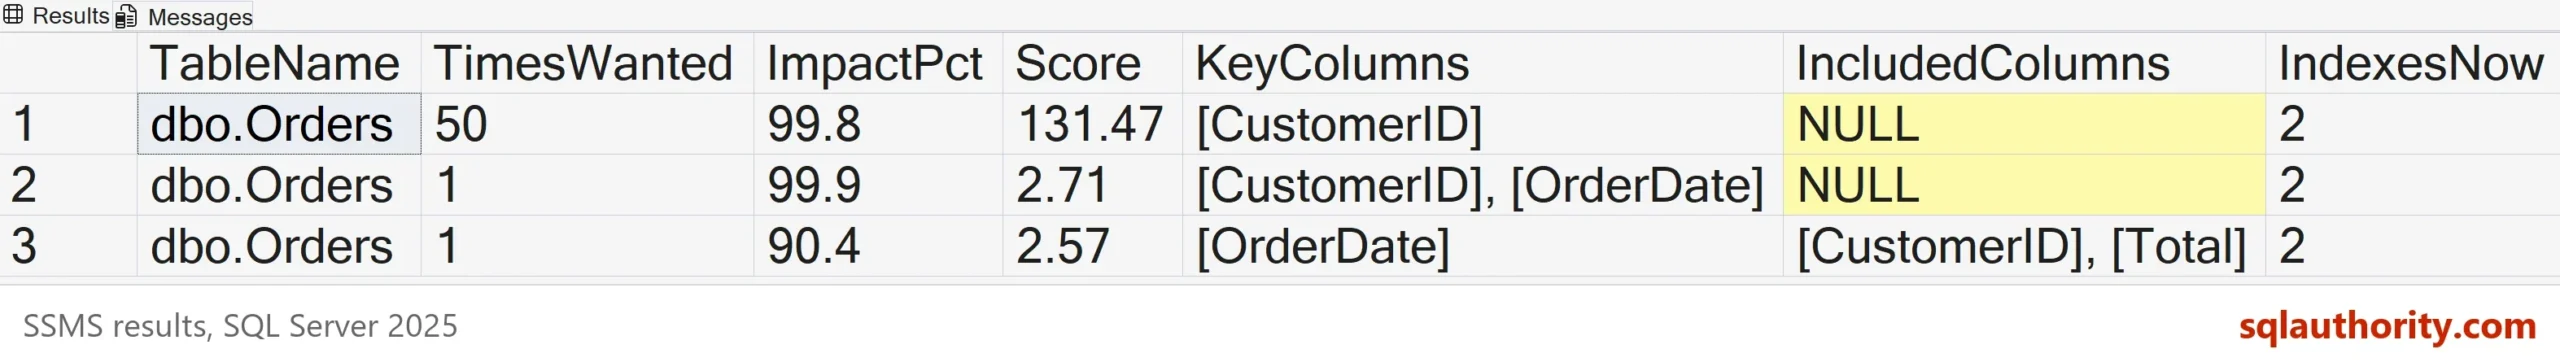
The customer lookup ranks first with a score of 131.47, because it ran 50 times. The date range query scores 2.71, and the September report scores 2.57. Both show an impact above 90 percent. A high impact on a query that ran once is a weak reason for an index.
Judge Each Suggestion Before You Create It
Start with the key. Equality columns, tested with =, come first, and inequality columns, tested with ranges such as >=, come after them. The script already lists them that way, so [CustomerID], [OrderDate] is ready to use. If two equality columns appear, the view’s order doesn’t tell you which should lead. Test both.
Next, read the INCLUDE list. Neither customer suggestion lists Total, yet both queries read it. Created exactly as suggested, the index left the date range query at 15 pages and the lookup at 33. Every row needed a trip back to the table. Adding INCLUDE (Total) brought both down to 3.
Then look for overlap. The lookup wants [CustomerID], and the date range query wants [CustomerID], [OrderDate]. One index with both columns serves both, so one index is enough. Several rows for the same key with different INCLUDE lists can merge the same way. Compare each suggestion with your existing indexes too. A suggestion can repeat a key you already have and differ only in its INCLUDE list. An index on OrderDate alone and a query that reads Total produce exactly that. The key repeats and INCLUDE ([Total]) is added.
Know the limits too. The feature suggests only nonclustered indexes, never filtered ones, and it ignores what an index costs to maintain. To estimate the space a suggestion needs, check a similar index in sys.dm_db_partition_stats. Or build it in a test copy first.
Last, count the indexes. The IndexesNow column shows how many the table has. My guide for a busy table is five to ten. Every index adds work to each insert and delete, and to each update that changes one of its columns.
Be careful with a key on a column that holds only a few values, such as a status flag. Check how selective it is before you trust the impact number. The views also don’t say which query wanted an index. Run the suspect query with the actual plan turned on. SSMS prints the suggestion in green text above the plan.
CREATE NONCLUSTERED INDEX IX_Orders_CustomerID_OrderDate
ON dbo.Orders (CustomerID, OrderDate) INCLUDE (Total);
GO
SET STATISTICS IO ON;
SELECT OrderID, OrderDate, Total
FROM dbo.Orders
WHERE CustomerID = 1234 AND OrderDate >= '2026-01-01';
SELECT OrderID, Total
FROM dbo.Orders
WHERE CustomerID = 1234;
SELECT CustomerID, SUM(Total) AS Spent
FROM dbo.Orders
WHERE OrderDate >= '2026-09-01' AND OrderDate < '2026-10-01'
GROUP BY CustomerID;
SET STATISTICS IO OFF;
| Query | Pages read before | Pages read after |
|---|---|---|
| Customer orders since January | 3,138 | 3 |
| One customer’s orders | 3,138 | 3 |
| September totals by customer | 3,138 | 548 |
Skip the suggestion for the September report. That’s my call: a month-end total doesn’t earn an index that every write to its columns must maintain. It still dropped to 548 pages. The new index is a thin copy of the table with every column that query needs.
Run the script again and it returns no rows. Creating the index cleared every suggestion for the table, so save the output before you create anything.
You could argue that disk is cheap, so you should create every suggestion. Disk isn’t the cost. Each new index is another structure that every insert and delete must change, and every update of its columns.
What to Remember
Treat the Missing Index Script as a source of leads, not decisions. Check the key order, the INCLUDE list and the overlap with what you have. Then check how many times it was wanted. Then create one index at a time and measure the reads again.
To find indexes to retire, read Unused Index Script: Find Indexes That Only Cost You Writes. When you finish testing, remove the example database.
USE master;
GO
ALTER DATABASE MissingIndexDemo SET SINGLE_USER WITH ROLLBACK IMMEDIATE;
DROP DATABASE MissingIndexDemo;
A missing index suggestion is not an order, it is a lead you check.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.


92 Comments. Leave new
Hi Pinal
How to get query detail or script that generate missing index record.
Currently, that is not available from SQL Server.
Hi Pinal,
I have an installation of SQL Server 2008 R2 (one of a few) and it’s reasonably busy system. I’m trying to optimise some of the indexes by using information from missing indexes tables.
What seems to be strange is that sys.dm_db_missing_index_group_stats table is empty?!
awesome dave, thanks!
Thanks dave
Hello Pinal, I have one doubt about the column Avg_Estimated_Impact. Is it a percent column? what type of info is it?
Doesn’t work. Returns error
Msg 451, Level 16, State 1, Line 9
Cannot resolve collation conflict between “SQL_Latin1_General_CP1_CI_AS” and “Latin1_General_100_CI_AS_KS_WS_SC” in add operator occurring in SELECT statement column 5.
Regarding the sort order of this query. I like to refer to https://learn.microsoft.com/en-us/sql/relational-databases/system-dynamic-management-views/sys-dm-db-missing-index-group-stats-transact-sql?view=sql-server-ver16
stated there is
ORDER BY avg_total_user_cost * avg_user_impact * (user_seeks + user_scans)DESC;
Why would take the avg_total_user_cost field out of the calculation? Is this by purpose what’s your vision on this?
Hi sir, my subscription is active. How can I get the SQl interview Q/A?
Hi! How to find the queries where missing indexes are suggested and measure the execution duration, pages reads and cpu usage without the index?
Is there a range until we should be verifing index on Avg_Estimated_Impact.