
Delete duplicate rows by numbering the rows in each group and removing every row after the first. In SQL Server that takes one short statement. The real work is deciding what counts as a duplicate and which copy survives.
Find the Duplicates Before You Touch Anything
The demo is a customer contacts table with both kinds of trouble. Maya Lopez was typed three times, once with a leading space and a new city. Noah Kim was typed twice, identically. Sam Rivera appears twice, once with capital letters. The script creates a database named DuplicateDemo for this post only, so run it on a test server.
IF DB_ID(N'DuplicateDemo') IS NULL CREATE DATABASE DuplicateDemo;
GO
USE DuplicateDemo;
GO
DROP TABLE IF EXISTS dbo.Contacts;
CREATE TABLE dbo.Contacts (
    ContactID int IDENTITY(1,1) NOT NULL PRIMARY KEY,
    FullName  nvarchar(80)  NOT NULL,
    Email     nvarchar(120) NOT NULL,
    City      nvarchar(60)  NOT NULL,
    CreatedOn date          NOT NULL
);
INSERT INTO dbo.Contacts (FullName, Email, City, CreatedOn)
VALUES (N'Maya Lopez', N'maya@example.com', N'Austin', '2026-01-10'),
       (N'Maya Lopez', N'maya@example.com', N'Austin', '2026-02-14'),
       (N'Maya Lopez', N' maya@example.com', N'Denver', '2026-03-02'),
       (N'Noah Kim', N'noah@example.com', N'Portland', '2026-01-20'),
       (N'Noah Kim', N'noah@example.com', N'Portland', '2026-01-20'),
       (N'Priya Shah', N'priya@example.com', N'Boston', '2026-02-01'),
       (N'Sam Rivera', N'sam@example.com', N'Chicago', '2026-02-11'),
       (N'Sam Rivera', N'SAM@example.com', N'Chicago', '2026-04-05');
To delete duplicate rows safely, first count them. The usual first look is GROUP BY with HAVING COUNT(*) > 1. That keeps only the groups that hold more than one row.
SELECT Email, COUNT(*) AS Copies
FROM dbo.Contacts
GROUP BY Email
HAVING COUNT(*) > 1
ORDER BY Email;
| Copies | |
|---|---|
| maya@example.com | 2 |
| noah@example.com | 2 |
| sam@example.com | 2 |
Maya shows two copies, but there are three. This server compares text without caring about case, which is why SAM matched sam. A trailing space is ignored in a comparison too. A leading space counts, so the third Maya row slipped through.
Clean the key before you compare it. LOWER(TRIM(Email)) removes spaces on both sides and ignores case, even on a case-sensitive database. TRIM removes only the space character by default, so tabs and line breaks from pasted data need more work. It needs SQL Server 2017 or later.
SELECT LOWER(TRIM(Email)) AS CleanEmail, COUNT(*) AS Copies
FROM dbo.Contacts
GROUP BY LOWER(TRIM(Email))
HAVING COUNT(*) > 1
ORDER BY CleanEmail;
| CleanEmail | Copies |
|---|---|
| maya@example.com | 3 |
| noah@example.com | 2 |
| sam@example.com | 2 |
Preview the Rows That Will Go
ROW_NUMBER gives each row a number inside its group. PARTITION BY defines the group, one per clean email address. ORDER BY decides who gets number 1, and that row stays. Here the newest row wins, and the highest ContactID breaks a tie.
The query lives inside a CTE, short for common table expression. A CTE is a named query written at the top of a statement. Run it as a SELECT first. Every row it lists with a number above 1 is a row the delete would remove. Read that list slowly. A wrong rank in a SELECT costs nothing, and a wrong rank in a DELETE costs data.
WITH Ranked AS (
    SELECT ContactID, FullName, Email, City, CreatedOn,
           ROW_NUMBER() OVER (PARTITION BY LOWER(TRIM(Email)) ORDER BY CreatedOn DESC, ContactID DESC) AS KeepRank
    FROM dbo.Contacts
)
SELECT ContactID, FullName, Email, City, CreatedOn, KeepRank
FROM Ranked
WHERE KeepRank > 1
ORDER BY ContactID;| ContactID | FullName | City | CreatedOn | KeepRank | |
|---|---|---|---|---|---|
| 1 | Maya Lopez | maya@example.com | Austin | 2026-01-10 | 3 |
| 2 | Maya Lopez | maya@example.com | Austin | 2026-02-14 | 2 |
| 4 | Noah Kim | noah@example.com | Portland | 2026-01-20 | 2 |
| 7 | Sam Rivera | sam@example.com | Chicago | 2026-02-11 | 2 |
Four rows are on the list. Maya’s newest row, the one with Denver, is safe. That matters, because the newest row holds the latest address. To keep the oldest row instead, change DESC to ASC and run the preview again.
Delete Duplicate Rows Inside a Transaction
Now swap the SELECT for a DELETE to delete duplicate rows for real. SQL Server lets you delete from a CTE that reads one table, and the rows disappear from that table. The OUTPUT clause saves every deleted row into an archive table, so nothing is lost. The preview promised four rows, so the script commits only when exactly four are deleted.
DROP TABLE IF EXISTS dbo.ContactsDeleted;
CREATE TABLE dbo.ContactsDeleted (
    ContactID int NOT NULL,
    FullName  nvarchar(80)  NOT NULL,
    Email     nvarchar(120) NOT NULL,
    City      nvarchar(60)  NOT NULL,
    CreatedOn date          NOT NULL
);
SET XACT_ABORT ON;
BEGIN TRANSACTION;
WITH Ranked AS (
    SELECT ContactID, FullName, Email, City, CreatedOn,
           ROW_NUMBER() OVER (PARTITION BY LOWER(TRIM(Email)) ORDER BY CreatedOn DESC, ContactID DESC) AS KeepRank
    FROM dbo.Contacts
)
DELETE FROM Ranked
OUTPUT deleted.ContactID, deleted.FullName, deleted.Email, deleted.City, deleted.CreatedOn INTO dbo.ContactsDeleted
WHERE KeepRank > 1;
IF @@ROWCOUNT = 4
    COMMIT TRANSACTION;
ELSE
    ROLLBACK TRANSACTION;
SELECT ContactID, FullName, Email, City, CreatedOn FROM dbo.Contacts ORDER BY ContactID;
SELECT ContactID, Email FROM dbo.ContactsDeleted ORDER BY ContactID;| ContactID | FullName | City | CreatedOn | |
|---|---|---|---|---|
| 3 | Maya Lopez | maya@example.com | Denver | 2026-03-02 |
| 5 | Noah Kim | noah@example.com | Portland | 2026-01-20 |
| 6 | Priya Shah | priya@example.com | Boston | 2026-02-01 |
| 8 | Sam Rivera | SAM@example.com | Chicago | 2026-04-05 |
| ContactID | |
|---|---|
| 1 | maya@example.com |
| 2 | maya@example.com |
| 4 | noah@example.com |
| 7 | sam@example.com |
Four rows remain, one per person, and the Maya address still begins with a space. The second table shows the four deleted rows, safe in the archive. If the count had differed, the script would have rolled back. The archive rows would have gone with it. SET XACT_ABORT ON rolls the transaction back on most run time errors too.
The CTE must read a single table. If it joins two tables, SQL Server refuses with Msg 4405, because the change affects multiple base tables. Rank the rows in one table first, then join. PARTITION BY needs every column listed, because there is no star shortcut. The old text and ntext types can’t be compared at all, so partition by other columns or move to varchar(max).
Tables With No Key
Many import tables have no key, and some rows are identical in every column. The same pattern works to delete duplicate rows here too. Partition by every column, and use ORDER BY (SELECT NULL), because no copy is better than another.
DROP TABLE IF EXISTS dbo.ContactImport;
CREATE TABLE dbo.ContactImport (FullName nvarchar(80) NOT NULL, Email nvarchar(120) NOT NULL);
INSERT INTO dbo.ContactImport (FullName, Email)
VALUES (N'Maya Lopez', N'maya@example.com'), (N'Maya Lopez', N'maya@example.com'),
       (N'Noah Kim', N'noah@example.com'), (N'Noah Kim', N'noah@example.com'),
       (N'Priya Shah', N'priya@example.com');
WITH Ranked AS (
    SELECT ROW_NUMBER() OVER (PARTITION BY FullName, Email ORDER BY (SELECT NULL)) AS KeepRank
    FROM dbo.ContactImport
)
DELETE FROM Ranked WHERE KeepRank > 1;
SELECT FullName, Email FROM dbo.ContactImport ORDER BY FullName;
Five rows went in and three came out: Maya, Noah and Priya, once each. Deleting from the CTE works on a table without a key, because SQL Server tracks each row by its position.
Stop New Duplicates From Arriving
A cleanup fixes today’s mess, and a unique index stops tomorrow’s. A plain unique index on Email isn’t enough. It would accept a value with a leading space, which is what hid the third Maya row. Index the cleaned value instead. A persisted computed column stores LOWER(TRIM(Email)), and the unique index sits on that column.
ALTER TABLE dbo.Contacts ADD CleanEmail AS LOWER(TRIM(Email)) PERSISTED;
CREATE UNIQUE INDEX UX_Contacts_CleanEmail ON dbo.Contacts (CleanEmail);
Now try to add Maya again, with capital letters and a leading space.
INSERT INTO dbo.Contacts (FullName, Email, City, CreatedOn) VALUES (N'Maya Lopez', N' Maya@Example.com', N'Dallas', '2026-05-01');
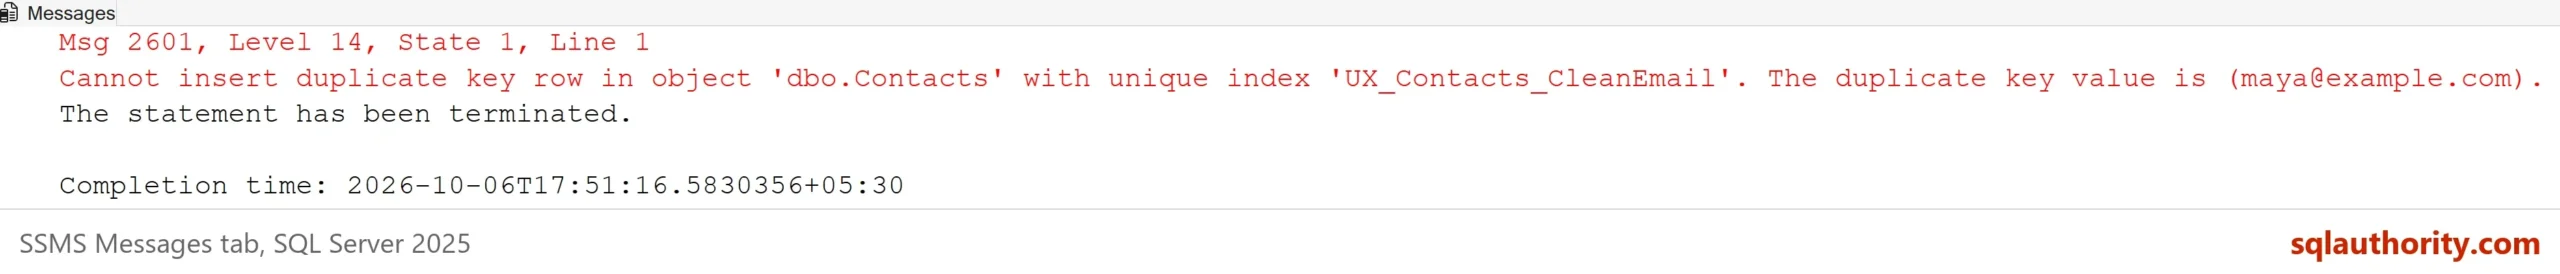
The statement fails, even though the new value differs from the stored one in spaces and capitals. The message reads as follows.
Msg 2601, Level 14, State 1, Line 1
Cannot insert duplicate key row in object 'dbo.Contacts' with unique index 'UX_Contacts_CleanEmail'. The duplicate key value is (maya@example.com).
The statement has been terminated.
For a load that runs every few minutes, the unique index is the better answer than a nightly cleanup. A load that contains a duplicate fails as a whole, though. You can filter the duplicates out before the insert. The index option IGNORE_DUP_KEY = ON is another route. It stores the new rows and prints Duplicate key was ignored for the rest. The load succeeds while rows are dropped. Use it only when that’s what you want.
When Deleting Is the Wrong Tool
You could argue that for a table with hundreds of millions of rows, deleting is a poor choice. Copy the rows you keep into a new table and swap the names. That avoids one huge delete and a huge log. It’s a fair point, and it costs a maintenance window plus rebuilding the indexes and constraints.
If you do delete, work in batches. One transaction with millions of rows grows the transaction log, while small batches let the log be reused between them. Ranking needs a sort unless an index helps. On 50,000 test rows, the plan for the ranking query has a Sort operator. With an index on the cleaned column, CreatedOn DESC and ContactID DESC, in the query’s order, the Sort disappears. A plain index on Email doesn’t help LOWER(TRIM(Email)), which is why the computed column matters.
What to Remember
Find the duplicates with a cleaned key. Preview with the same CTE as a SELECT. Delete inside a transaction, and commit only when the row count matches the preview. Choose the row to keep with ORDER BY, because the database can’t guess which copy is the right one. For a big cleanup, copy the table first, since a committed delete can’t be undone.
When I finish a cleanup, I add the unique index on the cleaned value before anyone loads data again. Without it, the duplicates return and the delete becomes a weekly chore. When you finish testing, remove the example database.
USE master;
GO
ALTER DATABASE DuplicateDemo SET SINGLE_USER WITH ROLLBACK IMMEDIATE;
DROP DATABASE DuplicateDemo;
A duplicate row is not a data problem, it is a rule nobody wrote down.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.


146 Comments. Leave new
NIce post.. helped me a lot…
Hello Pinal Sir ,
I am little bit confuse in one thing that if we have thousands of records in a table then how can we find the duplicate records and delete it by CTE. In your example , u mention only 7 rows data…Please guide
Pinal,
This works great!!! In order to keep the records where that were changed most recently, I changed the order by so that the most recently changed row was the first row – order by lastname, firstname, changedate desc.
As always I appreciate your blogs!
hi pinal,
I usually select duplicate rows by the other way:
select x,x,sum(1)
from TBL
order by x,x
GRACIAS ME AHORRASTE UN TEDIOSO TRABAJO!!!.EXCELENTE APORTE.
i used this valuable query but its throw an error like “semi colon missing in previous line of query”. if i put semi colon, is there any problem that terminate the stored procedure. after this i using some queries whether it will execute or not ?
Awesome and neat way to do it than putting in a staging table.
very clear demonstration, easy to understand.
thanks Pinal!!!!
Thanks Pinal Dave.
Worked Beautifully!!! Thanks Pinal Dave!
It worked !! thanks a lot
Great!!! Thanks a lot!!!
Great technique. Thanks for the informative post.
thanks Aashika. I am glad you liked it.
Hi Pinal,
I have below script and want to delete duplicated but when i run the query then i got an error msg like
”Msg 4405, Level 16, State 1, Line 2
View or function ’employeeDetails’ is not updatable because the modification affects multiple base tables.”
with employeeDetails
(SNO,ID,Title,FName,Lname,Contact,Payrate)
as
(select ROW_NUMBER()over(PARTITIOn by a.employeeID order by c.PayFrequency)SNO, a.EmployeeID,a.Title,b.FirstName,b.LastName,b.Phone,c.PayFrequency from HumanResources.Employee a inner join Person.Contact b on a.ContactID=b.ContactID
inner join HumanResources.EmployeePayHistory c on a.EmployeeID=c.EmployeeID)
delete from employeeDetails where sno>1
Please help
Thanks
Jaya sharma
perfect trick, thank you so much… u’ve help me….
Thank Very much this query helped me lot
Thanks Dinesh. I am glad that this helped you.
Hi, Pinal, is this applicable/advisable to use in a million records/rows?
Will it affect the performance?
thanks,
deleting rows in cte, but how does it deletes rows from original table – what is the inner algorithm behind it. I checked many blogs but no answer is satisfactory yet.
Your youtube video demonstrates an ENTIRELY DIFFERENT method than that which this page discusses. Very confusing!