I use REGEXP_MATCHES when I need rows for every pattern match and the groups inside each match. The full matched text and captured values are separate outputs. Keeping both makes extraction easier to review.
Confirm the supported environment
This example targets SQL Server 2025 and the standard compatibility-level 170 route. REGEXP_MATCHES is a table-valued function, not an older scalar string helper. The query doesn’t change database compatibility or any configuration.
I’d check those prerequisites before copying it into an application. A working pattern alone isn’t proof that an older deployment supports the function. Keep environment assumptions beside the copyable SQL.
SELECT match_id AS MatchId, start_position AS StartPosition,
       end_position AS EndPosition,
       CAST(match_value AS nvarchar(20)) AS MatchValue,
       CAST(substring_matches AS nvarchar(max)) AS CaptureGroups,
       CAST(JSON_VALUE(CAST(substring_matches AS nvarchar(max)),'$[0].value') AS nvarchar(10)) AS LetterGroup,
       CAST(JSON_VALUE(CAST(substring_matches AS nvarchar(max)),'$[1].value') AS nvarchar(10)) AS NumberGroup
FROM REGEXP_MATCHES(CAST(N'A7 B12 A3' AS nvarchar(40)),N'([A-Z])([0-9]+)','c')
ORDER BY match_id;

SELECT match_id AS MatchId, start_position AS StartPosition,
       end_position AS EndPosition,
       CAST(match_value AS nvarchar(20)) AS MatchValue,
       CAST(substring_matches AS nvarchar(max)) AS CaptureGroups,
       CAST(JSON_VALUE(CAST(substring_matches AS nvarchar(max)),'$[0].value') AS nvarchar(10)) AS LetterGroup,
       CAST(JSON_VALUE(CAST(substring_matches AS nvarchar(max)),'$[1].value') AS nvarchar(10)) AS NumberGroup
FROM REGEXP_MATCHES(CAST(N'plain' AS nvarchar(40)),N'([A-Z])([0-9]+)','c')
ORDER BY match_id;
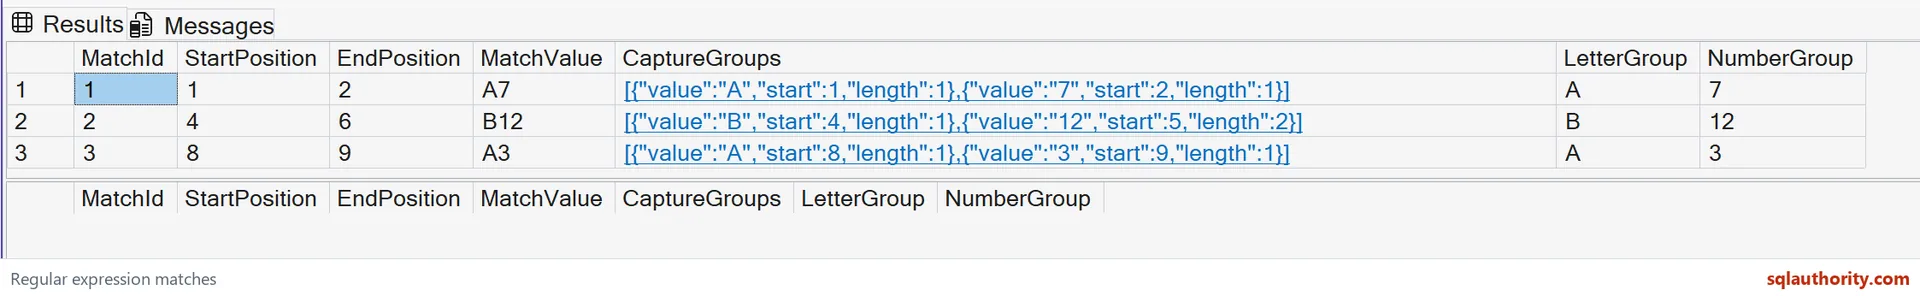
Separate matches from capture groups
The input contains A7, B12 and A3 separated by spaces. The pattern has two parenthesized groups: one uppercase ASCII letter and one or more digits. The explicit c flag requests case-sensitive matching.
MatchValue retains each complete match. The substring_matches JSON contains the individual captured group values with their starts and lengths. I cast that document to nvarchar(max) for display. The two extracted group columns then make the intended fields easy to read without hiding the full capture document.
Keep capture order visible
The first JSON array entry belongs to the letter group, and the second belongs to the digit group. JSON_VALUE reads those explicit positions. Each displayed group has an outer nvarchar(10) cast for a fixed SQL column contract.
I’d update that extraction if the pattern’s group structure changes. Adding another parenthesized capture can change array positions even when full matches still look correct. The complete JSON column exposes that difference. A successful match doesn’t automatically prove that every downstream group binding still addresses the intended field.
Preserve repeated values
The first and third matches both capture A as their letter. They remain separate match rows because their complete values and positions differ. The expected sequence is A7, B12, A3 ordered by match_id.
I’d retain those rows rather than applying DISTINCT to the letter column prematurely. A consumer may need each source occurrence, not just the set of recognized letters. This example preserves the complete matches and captures. Any later deduplication needs its own key and explicit business purpose.
Read positions and no-match state
The full matches occupy positions one through two, four through six, and eight through nine in the fixed input. The capture documents locate the individual letter and digit groups within those matches.
The second statement uses plain text with no matching token. Its expected result has the same columns and zero rows. A nonmatching input produces no row at all. I’d handle that empty result separately instead of inventing one row containing a successful-looking empty token.

Validate the whole extraction
Both statements read only constant strings and perform no writes. The inputs are short and bounded. This example makes no universal performance claim for arbitrary regex patterns or large text.
I’d compare all three complete tuples, their capture documents and the empty second result during validation. A row count alone would miss swapped group bindings. Test the application’s own punctuation, case and token rules separately. The small ASCII pattern explains capture extraction, not every possible identifier format.
Keep the full match and its groups together, because a matching row can still bind the wrong group.
A matching row is not a correct binding, it is only a match until its groups are checked.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.