
Log backup on secondary replica fails with error 35296 in the second availability group of a distributed availability group. One of my clients had me help configure Always On availability groups for the first time. I explained the topologies, the pros and the cons, and helped with the end-to-end implementation. If you want help with something similar, contact me.
The Error
After my help, the client felt comfortable and built a distributed availability group on their own. They told me things were going well, but the log backup job failed on one replica. This is the message from the job history:
Log backup for database "SQLAuthority" on secondary replica failed because the new backup information could not be committed on the primary database. Check the database status in the SQL Server error log of the server instance that is hosting the current primary replica. If the primary database is participating in the availability group, retry the operation. [SQLSTATE 42000] (Error 35296) BACKUP LOG is terminating abnormally.What the Client Saw
To keep it simple, picture the deployment like this:
myAG1 (myNode1, myNode2) <- myDistributedAG -> myAG2 (myNode3, myNode4)The distributed availability group sits between myAG1 and myAG2. myNode1 is the global primary, and myNode3 is a forwarder. The job fails on myNode4.
Why It Happens
I tried it in my lab and got exactly the same error. When I searched further, I found that it is by design. The documentation covers backups in a distributed availability group. You can run them on the secondary replicas of the group that holds the active primary. You can also run them on the primary replica of a secondary group.
You can’t run a backup on a secondary replica inside a secondary availability group. Those replicas only talk to the primary replica of their own group. Only replicas that talk directly to the global primary replica can run backups. In the example above, myNode2 and myNode3 can run the backup, and myNode4 can’t.
How to Check
Find out which replica the failing job runs on, and where that replica sits in the topology. If it’s a secondary replica of a secondary availability group, you’re looking at this limit.
The Fix
I told the client about the limitation. They understood it and changed their scripts. The backup now runs on a replica that talks directly to the global primary.
How to Prevent It
Before you schedule backups on a distributed availability group, map each replica. Put the backup jobs only on the replicas that can run them. Have you seen such errors while working with availability groups? Please share them in the comments.
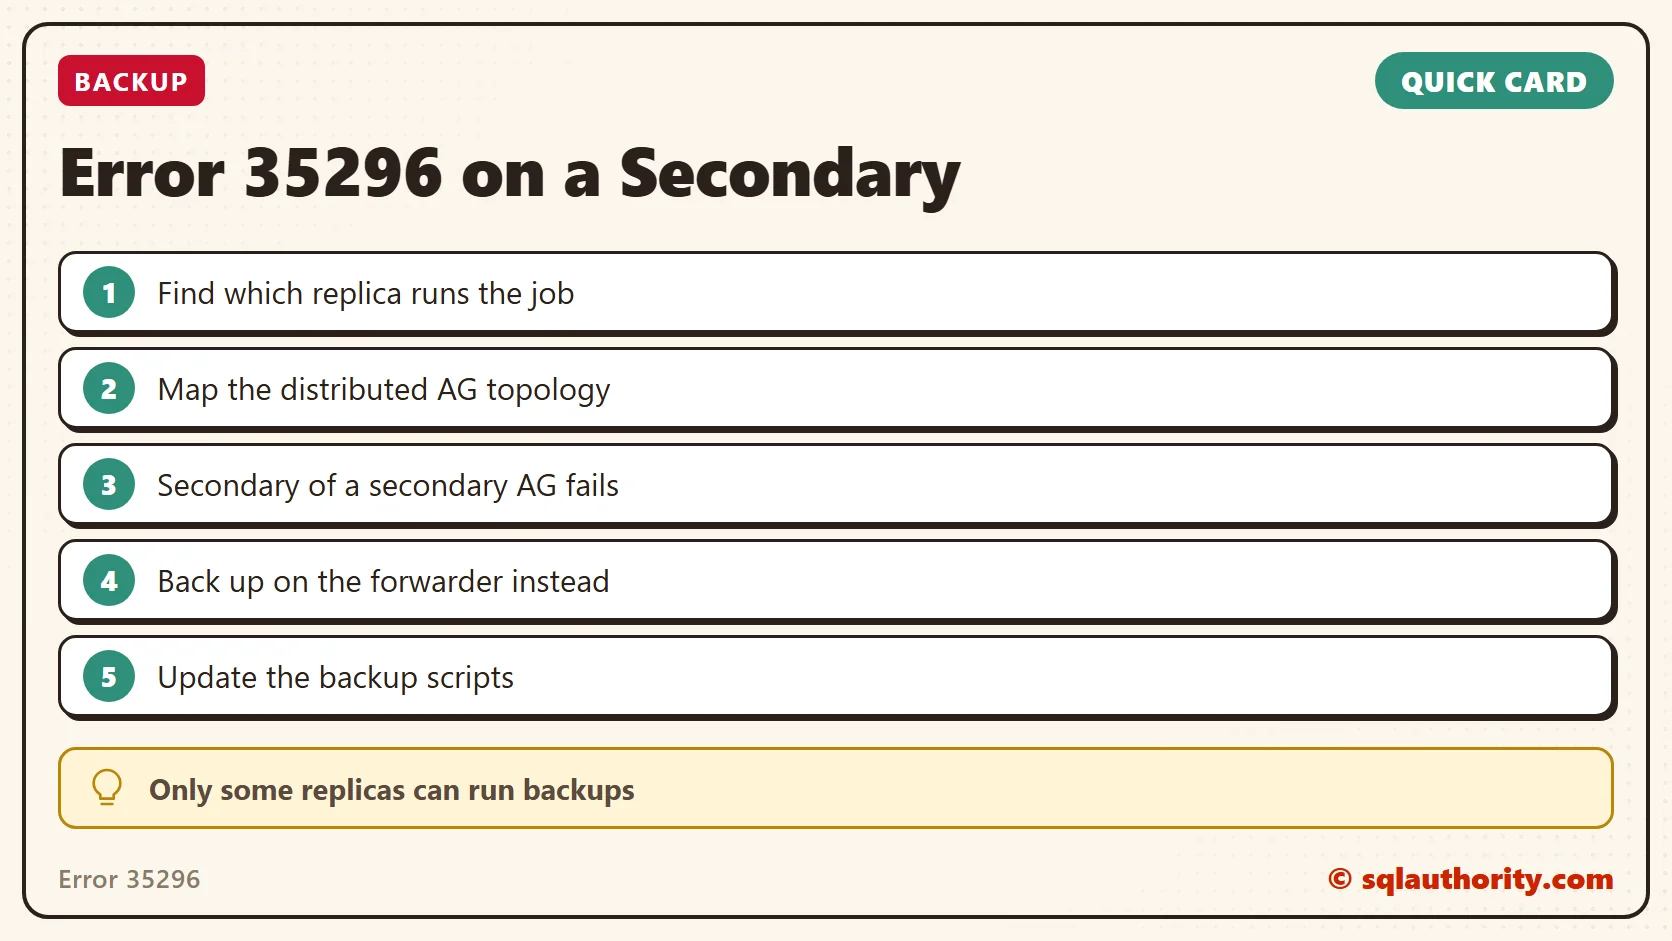
Error 35296 is not a broken backup, it is a limit of distributed availability groups.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.

1 Comment. Leave new
What were the script modifications that were made? Were you able to determine when a node was a secondary behind a forwarder?