Many people know how to add a column to an index key, but fewer can explain why an included column is different. That is the practical interview question I wanted to answer.
Question: What is an included column in a SQL Server nonclustered index?
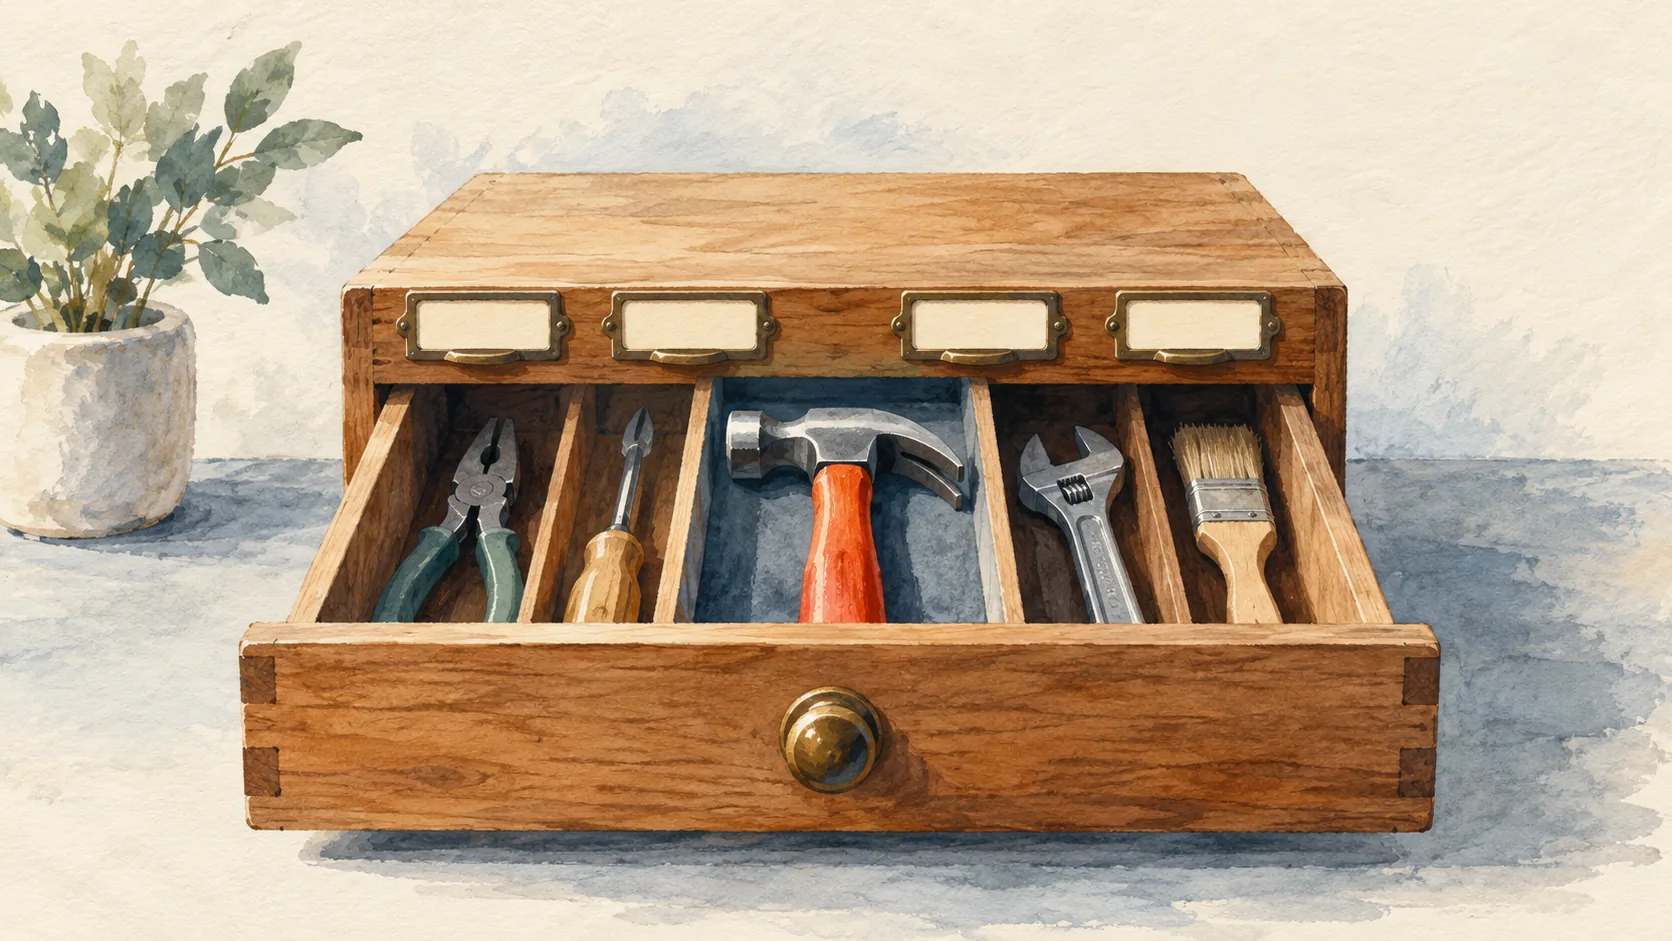
Answer: The key columns form the ordered search path. INCLUDE stores additional nonkey values at the leaf level so a query can retrieve them without going back to the base row. The included values do not become ordered navigation keys. A query is covered only for the columns and predicates it actually uses.
My original example searched Person.Address by postal code and returned address details. In the historical AdventureWorks schema, the relevant pattern was:
USE AdventureWorks;
GO
CREATE NONCLUSTERED INDEX IX_Address_PostalCode
ON Person.Address (PostalCode)
INCLUDE (AddressLine1, AddressLine2, City, StateProvinceID);
GO
SELECT AddressLine1, AddressLine2, City, StateProvinceID, PostalCode
FROM Person.Address
WHERE PostalCode BETWEEN '98000' AND '99999';
Run the CREATE statement only in an approved sample or scratch database where that index name is free. To measure a benefit, capture the same query’s actual plan and logical reads before and after. The original claim of a guaranteed significant improvement was too broad: it depends on the data and the plan selected.
The other original example used Production.Document (Title, Revision) as the key and FileName as included payload. That remains a useful way to explain why a wide output value may belong at the leaf instead of in the ordered key. Check the exact AdventureWorks schema and existing indexes before creating either demonstration index.
CREATE NONCLUSTERED INDEX IX_Document_Title
ON Production.Document (Title, Revision)
INCLUDE (FileName);
An included column can hold some data types that cannot be ordinary key columns, and its bytes do not count toward the nonclustered key-size limit. That does not make it free. Wider leaf rows consume storage and memory, and changes to included values maintain the index. Do not include every output column by habit. A column cannot be repeated in the INCLUDE list or listed both as a key and an included column; these useful restrictions were part of my original explanation.
The older article quoted a 16-key-column, 900-byte nonclustered key limit. Those were the limits before SQL Server 2016. For ordinary nonclustered indexes in SQL Server 2016 and later, the limit is 32 key columns and 1,700 bytes; the clustered key still has its own 900-byte limit. State the version when you give a limit in an interview.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.