Checking data compression settings means looking at every index and every partition, not just the table. One table can use PAGE on one structure, ROW on another and nothing at all on a third.
Why one table has more than one answer
A junior DBA once asked me, “Is the Orders table compressed?” I wanted to say yes, but the honest answer was “which part of it?” The table is really a set of physical structures. The clustered index holds the rows. Each nonclustered index holds its own copy of some columns. Every one of them has its own compression setting.
If the index is partitioned, it gets worse. Each partition can have a different setting. So a table-level label hides real differences. The only reliable way to know is to read the catalog at the level where the setting lives.
Let me build a small table so you can see this happen. It uses one demo table, dbo.CompressionDemo, and nothing else.
Start with a table that has no compression
The table gets a clustered primary key and 1,000 rows. The padding column repeats the same word, which gives compression something to chew on. The check afterwards reads sys.partitions for this one table. You should see a single row for the clustered index, with data_compression_desc set to NONE and 1000 rows.
DROP TABLE IF EXISTS dbo.CompressionDemo;

CREATE TABLE dbo.CompressionDemo
(
    Id       int      NOT NULL PRIMARY KEY CLUSTERED,
    Category int      NOT NULL,
    Payload  char(100) NOT NULL
);

INSERT dbo.CompressionDemo (Id, Category, Payload)
SELECT value, value % 10, 'repeat'
FROM GENERATE_SERIES(1, 1000);

SELECT index_id, partition_number, rows, data_compression_desc
FROM sys.partitions
WHERE object_id = OBJECT_ID(N'dbo.CompressionDemo')
ORDER BY index_id, partition_number;
A new index does not inherit the setting
Now rebuild the clustered index with PAGE compression. Then add a nonclustered index on Category, and this time say nothing about compression. Many people assume the new index follows the table. It does not. It starts with NONE, and only your next rebuild changes that.
The result has two rows. Index 1 shows PAGE and index 2 shows NONE. Both report 1000 rows.
ALTER INDEX ALL ON dbo.CompressionDemo
REBUILD WITH (DATA_COMPRESSION = PAGE);

CREATE INDEX IX_CompressionDemo_Category
    ON dbo.CompressionDemo (Category);

SELECT index_id, partition_number, rows, data_compression_desc
FROM sys.partitions
WHERE object_id = OBJECT_ID(N'dbo.CompressionDemo')
ORDER BY index_id, partition_number;
This is the mistake I see most often. Someone compresses the big clustered index, announces the job is done, and forgets the other indexes. Months later the nonclustered indexes are still full size.
Read the full inventory
Let me give the second index ROW compression, so the table now has two different settings. Then run the inventory query. It joins sys.partitions to sys.indexes and sys.objects, so every row carries the schema, table, index name, index ID and partition number.
The grain matters here. One row means one partition of one index. If you group by table, you lose the very thing you came to find.
ALTER INDEX IX_CompressionDemo_Category ON dbo.CompressionDemo
REBUILD WITH (DATA_COMPRESSION = ROW);

SELECT SCHEMA_NAME(o.schema_id) AS SchemaName,
       o.name AS TableName,
       i.name AS IndexName,
       p.index_id,
       p.partition_number,
       p.rows AS MetadataRows,
       p.data_compression_desc
FROM sys.partitions AS p
JOIN sys.indexes AS i
  ON i.object_id = p.object_id AND i.index_id = p.index_id
JOIN sys.objects AS o
  ON o.object_id = p.object_id
WHERE o.type = 'U' AND o.is_ms_shipped = 0
ORDER BY SchemaName, TableName, p.index_id, p.partition_number;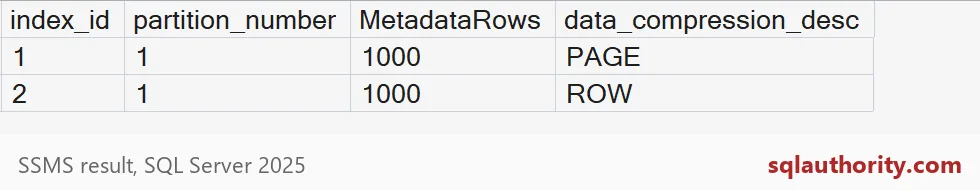
The clustered index reports PAGE and the category index reports ROW. Each shows MetadataRows of 1000, because both structures describe the same 1,000 rows. So do not add those numbers up. You would count the table twice.
Also remember that MetadataRows comes from the catalog. It is handy for an inventory, but it is not a fresh COUNT of the table.

Check your own server
Run the inventory query in any database you care about. It lists the user tables that your login is allowed to see. For a first look, a summary is easier to read. This one counts partitions by setting, so a long list collapses into a few lines.
In the demo it returns one PAGE partition and one ROW partition. On a real database, a NONE count next to a big table is usually where the savings are hiding.
SELECT p.data_compression_desc, COUNT(*) AS PartitionCount
FROM sys.partitions AS p
JOIN sys.objects AS o ON o.object_id = p.object_id
WHERE o.type = 'U' AND o.is_ms_shipped = 0
GROUP BY p.data_compression_desc
ORDER BY p.data_compression_desc;

DROP TABLE IF EXISTS dbo.CompressionDemo;
A setting tells you what is configured, not what you saved. It promises no percentage and no faster query. Data patterns, row layout and write CPU all play a part. So test a representative copy before you rebuild a large structure.
Next time someone asks if a table is compressed, ask them which index they mean.
Table compression is not one setting, it is a setting for each partition.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.