I cast SUM integer values before the aggregate when the total can exceed int. Each input row can fit its type while their combined total cannot. The accumulator’s return type matters too.
Keep valid rows and a wider total
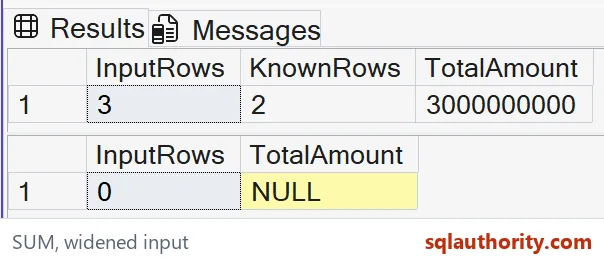
The first query supplies two amounts of 1.5 billion and one missing amount. Each known value fits int. Their expected total is three billion, which exceeds the positive int range.
The example casts each amount to bigint inside SUM. That gives the aggregate a bigint input and a bigint result. It avoids executing an intentionally overflowing int aggregate just to demonstrate the problem, while keeping the original input type explicit.
WITH Amounts AS
(
 SELECT CAST(Amount AS int) AS Amount
 FROM (VALUES (1500000000),(1500000000),(CAST(NULL AS int))) v(Amount)
)
SELECT COUNT(*) AS InputRows, COUNT(Amount) AS KnownRows,
       SUM(CAST(Amount AS bigint)) AS TotalAmount
FROM Amounts;

WITH Amounts AS
(
 SELECT CAST(Amount AS int) AS Amount
 FROM (VALUES (1500000000),(1500000000),(CAST(NULL AS int))) v(Amount)
)
SELECT COUNT(*) AS InputRows, SUM(CAST(Amount AS bigint)) AS TotalAmount
FROM Amounts
WHERE 1=0;
Widen before accumulation
SUM(int) returns int and SUM(bigint) returns bigint. Casting the final result after SUM doesn’t change the type used during the earlier aggregation. The placement of the cast is therefore part of the solution.
I’d review the expression inside the aggregate rather than only its alias or destination type. A report column named LargeTotal can still use a narrow accumulator. Likewise, assigning that result to a wider consumer won’t repair an overflow that occurred before assignment.
Expose missing amounts alongside the total
InputRows counts three supplied rows, while KnownRows counts two non-NULL amounts. SUM ignores the missing amount and adds the two known values. Those counts explain the coverage of the resulting total.
I don’t replace every missing amount with zero automatically. An unknown amount can represent incomplete data rather than a confirmed zero. Keep the total and its coverage separate. A reviewer can then distinguish a complete calculation from a partial one.
Read the empty set deliberately
The second query filters out every input row. Its expected row count is zero and its total is NULL. An aggregate without GROUP BY still returns one row here, even though no source rows remain.
I’d keep that case when a consumer expects a numeric total. A zero default can be useful for display, but it changes the missing-result contract. Add that default deliberately at the appropriate boundary. An empty set doesn’t prove that known amounts sum to zero.
Review arithmetic before SUM as well
The cast protects this direct amount expression. If the aggregate instead sums a product, the multiplication’s type needs review before aggregation. Two int factors can overflow in their product before a later SUM sees the value.
I’d widen an operand early enough for that calculation too. A wide accumulator doesn’t make every preceding expression wide. Keeping the full expression visible helps identify where each intermediate value is produced and which type governs its available range.

Match the final contract to the requirement
bigint has a larger range, but it isn’t unlimited. The application’s allowed amounts and maximum row count still need a documented bound. Fractional money or quantities also need an appropriate exact decimal type instead of integer widening alone.
These SELECT statements create no objects and change no data. Their complete expected outputs check the type placement and the empty-set contract. I’d retain the exact inputs and actual results when validating the expression against the target SQL Server instance.
Run it on your own numbers and see where the total stops fitting.
A wider destination is not a wider accumulator, it is the input cast that changes SUM’s return type.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.
Discover more from SQL Authority with Pinal Dave
Subscribe to get the latest posts sent to your email.