Outdated statistics in SQL Server cause the strangest performance problems I get called about, because nothing is broken. The query is fine, the index is fine, the hardware is fine. The optimizer is making excellent decisions about a table that stopped existing eighteen months ago.
What Statistics Are, Without the Jargon
The optimizer normally uses statistics instead of reading every row to estimate a query result. Statistics summarize values and their distribution. Creating or refreshing statistics can itself read data during compilation.
That summary is a statistics object. The spread lives in a histogram of up to 200 steps. That histogram covers the first column of the statistic, and some density information comes with it. It’s a description of your data, not the data.
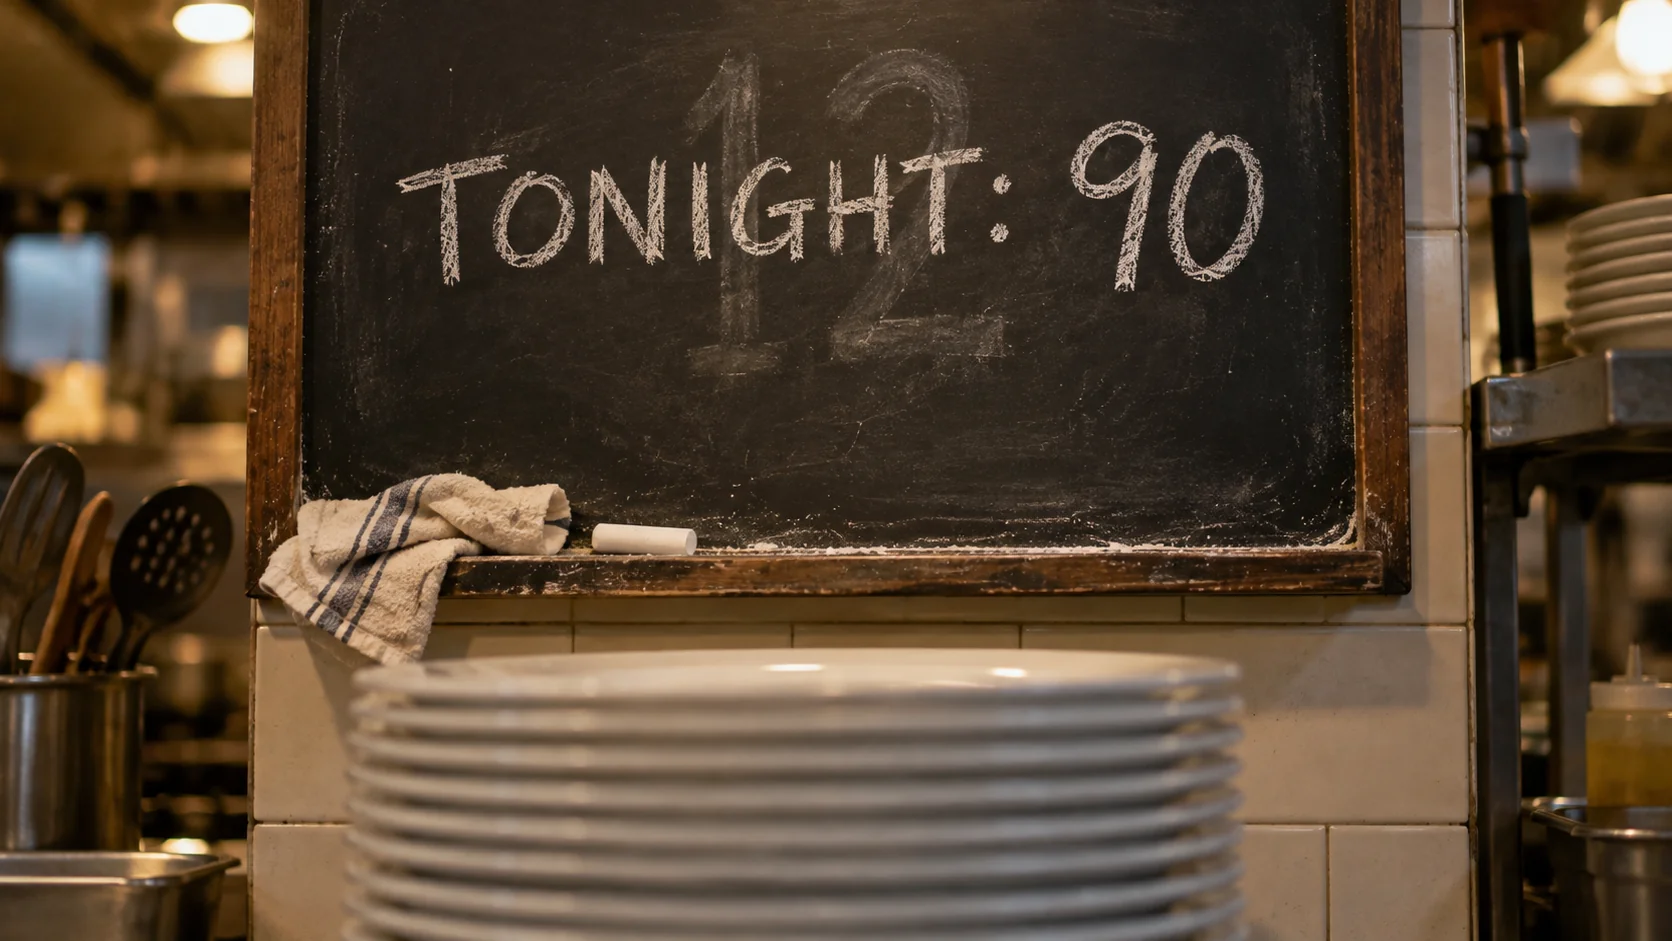
The optimizer uses that description to guess how many rows a query will touch, then picks a strategy to match. It’s a chef planning dinner from last month’s reservation list. If last month says twelve guests and ninety people walk in, that kitchen is in trouble. Nobody in it is incompetent.
Why the Guess Matters So Much
Row estimates influence access methods and join selection. Nested loops can suit a small outer input with efficient inner lookups. Larger inputs may favor hash or merge joins, depending on indexes, ordering, memory, and estimated costs.
Estimates also influence memory grants for sorts and hash joins. Insufficient memory can cause spills to tempdb. Excessive grants can reserve memory other queries need. Memory grant feedback can adjust later executions in supported configurations, but it does not eliminate every estimation problem.
Estimates affect plan costs, which influence parallelism alongside configuration and available alternatives. An early estimation error can affect later operators. A query can therefore become slower without any code change.
But Auto Update Is On
It usually is, and that’s why most teams assume this is handled. Auto update isn’t continuous, though. It fires when enough rows have changed, and that threshold has moved over the years.
For tables above 500 rows, the old threshold formula was 500 plus twenty percent of the row count. At one hundred million rows, that gives 20,000,500 modifications. Smaller tables have different thresholds.
SQL Server 2016 and later use dynamic thresholds by default at compatibility level 130 or higher. Above 500 rows, take the smaller of the old formula and the square root of 1,000 times the row count. Trace flag 2371 enables dynamic thresholds on supported older versions and newer engines using lower compatibility levels.
For a million-row table, those formulas give 200,500 and approximately 31,623. I went looking for the real line on SQL Server 2025, adding rows 500 at a time. Auto update first fired at 32,000 modifications. Steps of 500 only bracket the boundary, so read that as close to the formula, not as an exact threshold.
Crossing the threshold does not immediately launch a scheduled refresh. A query that needs the statistics can trigger an update. With synchronous updating, that work can add latency to the triggering query.
AUTO_UPDATE_STATISTICS_ASYNC allows queries to compile using existing statistics while the refresh runs in the background. That can affect multiple executions, and the background work still consumes resources.
The other is sampling. Auto update usually reads a fraction of the table and extrapolates from it. For evenly spread data that’s fine. For skewed data, the sample can miss the shape.
The Day That Isn’t in the Histogram
This one bites hardest, and it has a name: the ascending key problem. Your orders table has a date column. Statistics were updated last night, so the histogram ends at yesterday. Today’s orders arrive, and somebody runs a report filtered to today.
I built exactly that on SQL Server 2025: a million rows spread over 400 days, with full-scan statistics. Then I added 20,000 orders dated today, below the refresh threshold. These two queries count today’s rows, once with each cardinality estimator. They need the same Orders table and data.
SELECT COUNT_BIG(*) FROM dbo.Orders
WHERE  OrderDate >= CAST(CAST(GETDATE() AS date) AS datetime2(0))
OPTION (RECOMPILE);

SELECT COUNT_BIG(*) FROM dbo.Orders
WHERE  OrderDate >= CAST(CAST(GETDATE() AS date) AS datetime2(0))
OPTION (RECOMPILE, USE HINT('FORCE_LEGACY_CARDINALITY_ESTIMATION'));
Each query returned one result row containing the count 20,000. The index seek estimated 6,000 matching rows with the current estimator and one with the legacy estimator. The first estimate was about 3.3 times too low. These estimates describe this dataset and configuration, not every ascending-key query.
Then I joined the same filter to a customer table to see what the estimate does to the work. With stale statistics and legacy estimation, nested loops incurred 120,043 logical reads. After updating the relevant statistic, the estimate became 19,867 and a hash join incurred 18,220 logical reads. Logical reads count page accesses, including repeated accesses, rather than distinct pages or physical disk reads.
With the stale statistic, the current estimator’s plan used a merge join and made 17,363 logical reads. That was fewer reads than the refreshed legacy plan, despite a less accurate estimate. Better estimates do not guarantee fewer reads, and logical reads alone do not establish elapsed-time improvement. Compare plans, reads, CPU time, and elapsed time for your workload.
The legacy hint selects the older estimator on the same engine. It does not recreate an older SQL Server release. Compatibility level 110 or lower normally uses legacy estimation, but settings and hints can override estimator selection.
What to Check
Run this in the database you are investigating, with permission to inspect statistics. The persisted_sample_percent column requires a supporting build, including SQL Server 2016 SP1 CU4 or later.
SELECT SCHEMA_NAME(o.schema_id) + '.' + o.name AS TableName,
       s.name AS StatName,
       sp.last_updated,
       sp.rows,
       sp.rows_sampled,
       sp.modification_counter,
       sp.persisted_sample_percent
FROM sys.stats AS s
JOIN sys.objects AS o ON o.object_id = s.object_id
CROSS APPLY sys.dm_db_stats_properties(s.object_id, s.stats_id) AS sp
WHERE o.type = 'U'
ORDER BY sp.modification_counter DESC;
Two columns tell you most of it. Compare rows_sampled against rows. Ninety million rows summarized from two million is a picture drawn from about 2.2 percent of the data.
For disk-based tables, modification_counter tracks modifications to the leading statistics column since its last update. The rows value reflects that update, not necessarily the current table size. A large counter suggests investigation; it does not establish that the statistic caused a slow query.
A NULL last_updated can mean no statistics blob exists, such as for an empty table or an empty filtered set. Check the table and filter before deciding whether that matters. Insufficient permissions can instead produce an empty function result, which CROSS APPLY omits.
The Fix
Schedule targeted updates around meaningful data changes, such as a large load, when measurements justify them. A nightly schedule is an option, not a universal requirement. If using a maintenance solution, check its only-modified setting rather than assuming it is enabled.
For the handful of tables that drive your worst plans, name the statistic and sample harder:
UPDATE STATISTICS dbo.Orders IX_Orders_OrderDate WITH FULLSCAN;A full scan reads all rows, so measure its cost and target the relevant statistic. In my test, a later automatic update sampled 95,382 of 1,060,000 rows, about nine percent. The sample rate changed, but the statistic also incorporated newer data. A smaller sample alone does not prove that estimates became worse.
If you want that rate to stick, ask for it:
UPDATE STATISTICS dbo.Orders IX_Orders_OrderDate
WITH FULLSCAN, PERSIST_SAMPLE_PERCENT = ON;
That option arrived in SQL Server 2016 SP1 CU4 and SQL Server 2017 CU1. While the persisted rate remains 100 percent, automatic updates retain the cost of a full scan. Truncating the table or updating statistics on an empty object can reset it.
Older builds can also lose the persisted rate during an index rebuild. Retention fixes arrived in SQL Server 2016 SP2 CU17, SQL Server 2017 CU26, and SQL Server 2019 CU10.
A nonpartitioned, nonresumable rowstore index rebuild refreshes its index statistics with a full scan. Partitioned and resumable index operations have sampling exceptions. Statistics refresh can explain a rebuild’s benefit, but page density and other factors can also matter.
Rebuilding that index does not refresh separate column statistics. In my test, the rebuilt index came back fully sampled. An automatically created statistic on another column still showed 353,333 modifications since its last update.
If your weekend job rebuilds indexes for that side effect, look at the clock. A statistics job that runs in minutes can buy the same thing. I wrote about the rest of that habit in Your Index Rebuild Maintenance Plan Is Rebuilding Indexes Nobody Uses.
Why This One Is Worth Your Attention
It shows up as randomness, and randomness is the hardest thing to get a team to investigate. The query is fast in the morning and slow in the afternoon. It’s fast in test and slow in production with identical code. It was fine for a year, and then it wasn’t.
People start blaming the network, the storage, the other team, the phase of the moon. Nobody suspects the small summary object that nobody has looked at since the database was built. Update the statistic, then check the estimate and the reads again.
The optimizer is not guessing badly, it is answering from a description of your data nobody has corrected.
Published by Pinal Dave on SQLAuthority. More of my work at pinaldave.com.